Skill Issue: AutoResearch and the Loopy Era of AI · AI Field Notes
| Field 字段 | Value 内容 | | --- | --- | | Video ID | kwSVtQ7dziU | | Duration 时长 | 01:06:31 | | Chapters 章节 | 13 | | Bilingual semantic paragraphs 双语语义段落 | 134 | | Transcript source 字幕来源 | User-provided English auto-genera
Document profile 文档信息
| Field 字段 | Value 内容 |
|---|---|
| Video ID | kwSVtQ7dziU |
| Duration 时长 | 01:06:31 |
| Chapters 章节 | 13 |
| Bilingual semantic paragraphs 双语语义段落 | 134 |
| Transcript source 字幕来源 | User-provided English auto-generated SRT 用户提供的英文自动字幕 |
| Translation mode 翻译方式 | Paragraph-level academic translation; not sentence-by-sentence 语义段落级学术翻译,非逐句对照 |
| Obsidian | Native Markdown; local images; CSS snippet included 原生 Markdown、本地图片、附 CSS snippet |
Method and limitations 方法与限制
English
The transcript was reconstructed from auto-generated captions, merged into semantic paragraphs, and translated at paragraph level. The English text preserves the supplied captions rather than silently rewriting them. Obvious recognition errors are documented separately. Research notes distinguish interview claims from independently verifiable documentation and analytical inference.
简体中文
本文档依据自动生成字幕重建正文,并按语义合并为段落,再进行段落级翻译。英文部分保留用户提供字幕的基本形态,不对原文进行无提示改写;明显的语音识别错误另行列出。研究注释明确区分访谈中的观点、可独立核验的公开文档事实,以及分析性推断。
Auto-generated captions can misidentify product names, technical terms, speaker changes, and punctuation. Consult the video when exact wording is material.
自动字幕可能错误识别产品名称、技术术语、说话人切换与标点。涉及精确措辞时,应回看原视频。
Contents 目录
- 00:00:00 — Opening and introduction
- 00:02:55 — What capability limits remain?
- 00:06:15 — What mastery of coding agents looks like
- 00:11:16 — Second-order effects of natural-language coding
- 00:15:51 — Why AutoResearch
- 00:22:45 — Relevant skills in the AI era
- 00:28:25 — Model speciation
- 00:32:30 — Building collaboration surfaces for humans and AI
- 00:37:28 — Analysis of jobs-market data
- 00:48:25 — Open versus closed-source models
- 00:53:51 — Autonomous robotics
- 01:00:59 — MicroGPT and agentic education
- 01:05:40 — Conclusion
Research synthesis 研究综合
1. The bottleneck moves from production to orchestration 瓶颈从产出转向编排
English
The interview’s most consequential claim is that code generation is no longer the central scarce resource for an advanced user. Once multiple agents can produce artifacts in parallel, the human bottleneck becomes choosing objectives, allocating tasks, maintaining shared context, resolving conflicts, and deciding what evidence is sufficient. This is a transition from individual production to portfolio management of machine work.
简体中文
访谈中最重要的判断是:对高级使用者而言,代码生成本身不再是核心稀缺资源。当多个智能体能够并行产生产物后,人类瓶颈转移到目标选择、任务分配、共享上下文维护、冲突解决以及证据充分性判断。这意味着工作形态从个人直接生产转向对机器工作组合的管理。
2. Persistent agents increase both leverage and attack surface 持久智能体同时扩大杠杆与攻击面
English
A persistent “claw-like” agent adds memory, identity, scheduled operation, tool credentials, and a sandbox around the base model. These additions enable long-running projects and asynchronous coordination, but they also create durable state that can be poisoned, privileges that can be abused, and actions that may execute without immediate human review. Secure designs therefore require least privilege, isolated workspaces, provenance, approval gates, rate limits, and reversible operations.
简体中文
类似 claw 的持久智能体在基础模型之外增加记忆、身份、计划执行、工具凭据和沙箱。这些能力支持长期项目与异步协作,但也引入可被污染的持久状态、可能被滥用的权限,以及缺乏即时人工审查的动作。因此,安全架构需要最小权限、隔离工作区、来源追踪、审批关卡、速率限制和可逆操作。
3. AutoResearch is a constrained optimization system AutoResearch 是受约束的优化系统
English
The public AutoResearch repository confirms a deliberately narrow loop: the agent edits only train.py, prepare.py and the evaluation harness remain fixed, each training experiment receives a five-minute wall-clock budget, and val_bpb is the primary metric with lower values preferred. Git commits and keep/discard decisions provide explicit state transitions. The architecture is effective because it converts research into a sequence of cheap, comparable, mechanically scored trials.
简体中文
公开的 AutoResearch 仓库确认了一个刻意收窄的实验闭环:智能体只修改 `train.py`,`prepare.py` 与评测框架保持固定;每次训练获得五分钟墙钟预算,以越低越好的 `val_bpb` 为主指标;Git 提交与保留/丢弃决策形成显式状态转移。该架构之所以有效,是因为它把研究转化为一系列成本较低、可以比较、可由机器评分的试验。
4. program.md creates a meta-optimization layer program.md 构成元优化层
English
In AutoResearch, the human increasingly programs the research organization rather than each experiment. program.md specifies the agent’s operating policy, constraints, logging discipline, and stopping behavior. Improving this file changes the distribution of future experiments. The system therefore has two optimization levels: model-training changes inside train.py and research-policy changes inside program.md.
简体中文
在 AutoResearch 中,人类逐渐不再逐个设计实验,而是编程整个研究组织。`program.md` 规定智能体的运行策略、约束、日志纪律和停止行为;对该文件的改动会改变后续实验的分布。因此,系统具有两个优化层级:`train.py` 内的模型训练改动,以及 `program.md` 内的研究策略改动。
5. Parallel swarms require stronger coordination than sequential loops 并行智能体群需要比串行循环更强的协调机制
English
The public baseline is a sequential single-GPU loop. Scaling it to multiple agents or untrusted compute is not a free multiplier: experiments can duplicate one another, contaminate shared state, exploit evaluation weaknesses, or merge incompatible changes. A credible multi-agent research system needs experiment identity, immutable inputs, isolated branches, resource leases, statistically aware evaluation, artifact signing, provenance graphs, and a controlled merge policy.
简体中文
公开基线是单 GPU 的串行循环。扩展到多智能体或不受信任的计算资源,并不会自动获得线性收益:实验可能重复、污染共享状态、利用评测漏洞,或产生无法合并的改动。可信的多智能体研究系统需要实验身份、不可变输入、隔离分支、资源租约、具备统计意识的评测、产物签名、来源图谱和受控合并策略。
6. Model speciation reduces correlated failure 模型分化可以降低相关性失败
English
The interview argues for a future with differentiated models and agent roles rather than one universal worker. From a systems perspective, heterogeneity can improve search coverage and reduce correlated errors, provided outputs are judged by shared tests. However, diversity also raises integration cost because agents differ in tool use, formatting, risk tolerance, and failure modes.
简体中文
访谈设想的未来不是单一通用模型承担全部工作,而是模型与智能体角色发生分化。从系统角度看,只要所有输出接受共同测试,异质性就能扩大搜索覆盖并降低相关性错误;但多样性也会提高集成成本,因为不同智能体在工具使用、格式、风险偏好和失败模式上并不一致。
7. Labor-market conclusions require task-level evidence 劳动力市场结论需要任务级证据
English
The conversation raises plausible mechanisms such as productivity expansion, demand elasticity, and Jevons-style rebound effects. These mechanisms cannot by themselves establish net employment outcomes. U.S. BLS projections for 2024–2034 show growth of 3.1% for all occupations, 10.1% for computer and mathematical occupations, and 15.8% for software developers, but the projections are not causal estimates of generative-AI impact and should not be treated as validation of any single narrative.
简体中文
访谈提出了生产率扩张、需求弹性和类似 Jevons 效应的反弹机制。这些机制本身不足以确定净就业结果。美国劳工统计局对 2024—2034 年的预测为:全部职业增长 3.1%,计算机与数学职业增长 10.1%,软件开发者增长 15.8%;但这些数据不是生成式 AI 影响的因果估计,不能用于单独验证任何一种叙事。
8. Bits and atoms remain separated by physical interfaces 比特与原子仍由物理接口隔开
English
Agents can scale rapidly in digital environments because actions are cheap, copyable, and often reversible. Robotics introduces sensor noise, actuator limits, latency, wear, safety envelopes, and irreversible consequences. The relevant architecture must connect perception, world modeling, planning, control, and safety monitoring; language-model capability alone does not remove these physical constraints.
简体中文
智能体在数字环境中容易扩展,因为动作成本低、可复制且通常可逆。机器人系统则受到传感器噪声、执行器限制、延迟、磨损、安全包络以及不可逆后果的约束。相关架构必须连接感知、世界建模、规划、控制和安全监测;仅提高语言模型能力并不会消除这些物理限制。
9. microGPT is an educational compression, not a production recipe microGPT 是教育性压缩,而非生产方案
English
Karpathy’s microGPT page presents a dependency-free Python implementation of roughly 200 lines containing a dataset, tokenizer, scalar autograd, a GPT-2-like network, Adam, training, and inference. Its value is conceptual completeness: it exposes the algorithmic skeleton. Production systems add tensor kernels, batching, distributed execution, numerical engineering, monitoring, data governance, and many other layers.
简体中文
Karpathy 的 microGPT 页面给出约 200 行、无依赖的 Python 实现,包含数据集、分词器、标量自动微分、类 GPT-2 网络、Adam、训练与推理。其价值在于概念完整性,即显露算法骨架;生产系统还需要张量内核、批处理、分布式执行、数值工程、监控、数据治理等大量附加层。
Concept map 概念图谱
Multi-agent orchestration topology 多智能体编排拓扑
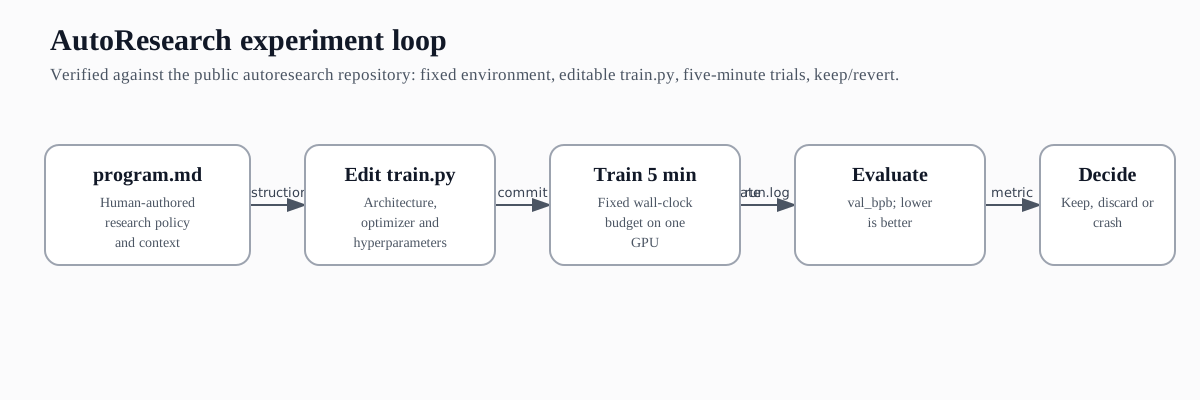
AutoResearch experiment loop AutoResearch 实验闭环
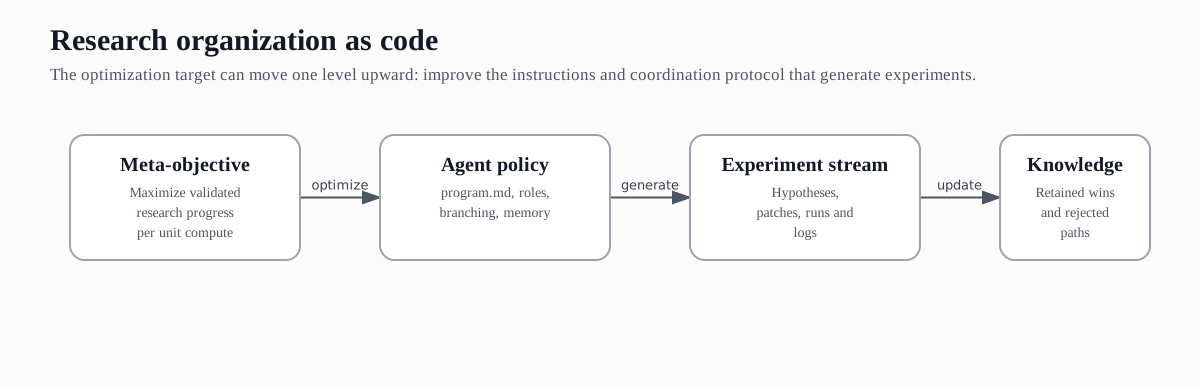
Research organization as code 研究组织即代码
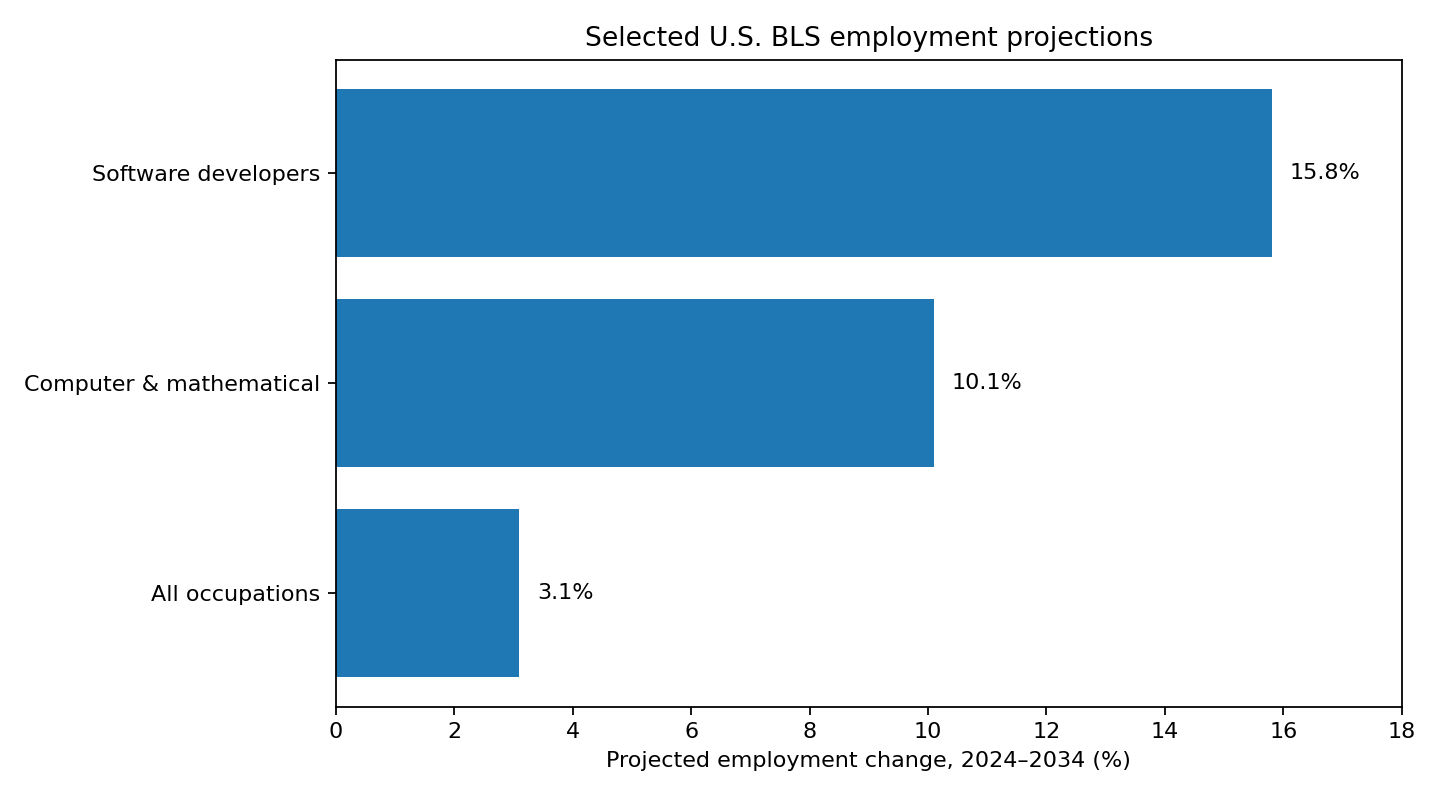
Selected U.S. BLS employment projections, 2024–2034. These projections are not causal estimates of AI impact. 美国劳工统计局 2024—2034 年部分就业预测;这些预测并不是 AI 影响的因果估计。
Analytical comparison 分析对照
| Layer 层级 | Sequential baseline 串行基线 | Multi-agent extension 多智能体扩展 | Main risk 主要风险 |
|---|---|---|---|
| Goal 目标 | One metric and one branch 单指标、单分支 | Portfolio of hypotheses 假设组合 | Metric gaming 指标投机 |
| Execution 执行 | Edit → run → evaluate 修改→运行→评估 | Parallel workers and resource leases 并行 worker 与资源租约 | Duplicate or conflicting trials 重复或冲突实验 |
| State 状态 | Git + results.tsv | Event log, provenance graph, shared memory 事件日志、来源图、共享记忆 | State contamination 状态污染 |
| Evaluation 评估 | Single measured score | Repeats, confidence and Pareto checks 重复实验、置信度与 Pareto 检查 | Noise mistaken for progress 把噪声误判为进步 |
| Trust 信任 | Local controlled machine | Heterogeneous or untrusted compute 异构或不受信任计算 | Artifact tampering 产物篡改 |
| Merge 合并 | Keep or reset one branch | Controlled reconciliation across branches 跨分支受控协调 | Incompatible improvements 改进不可兼容 |
Key terms 关键术语
| Term | Working definition 工作定义 | Status 性质 |
|---|---|---|
| Code agent | An LLM-based system coupled to repository, shell, editor, tests and state-management tools. 与仓库、终端、编辑器、测试和状态管理工具结合的 LLM 系统。 | Analysis |
| Claw | Informal interview term for a persistent agent wrapper with memory, identity, tools and continuous operation. 访谈中的非正式术语,指带记忆、身份、工具与持续运行能力的持久智能体封装。 | Transcript |
| AutoResearch | Karpathy’s public constrained loop for autonomous experiments on a simplified single-GPU nanochat training setup. Karpathy 公开的受约束自主实验循环,用于简化的单 GPU nanochat 训练。 | Official |
| program.md | Human-editable instruction and research-policy file controlling the agent loop. 人类可编辑的指令与研究策略文件,用于控制智能体循环。 | Official |
| val_bpb | Validation bits per byte; the repository’s vocabulary-size-independent metric, lower is better. 验证集每字节比特数;仓库采用的词表无关指标,越低越好。 | Official |
| Research org as code | The analytical idea that roles, policies, memory and evaluation protocols can be represented as executable instructions. 将角色、策略、记忆和评测协议表示为可执行指令的分析概念。 | Analysis |
Editorial notes on caption recognition 字幕识别编辑说明
- Open Claude Open Claw → OpenClaw
Nana Banana→ Nano BananaNan Chat→ nanochatQuinn→ Qwenarchive papers→ arXiv papers- scale issue → likely “skill issue” in context 按语境可能为 skill issue
Full bilingual transcript 中英双语全文
Chapter 1: Opening and introduction
Chapter start 章节起点: 00:00:00
00:00:00
Open at 00:00:00 从此处播放
English
Code’s not even the right verb anymore, right? [laughter] But I have to express my will to my agents for 16 hours a day. Manifest. [music] How can I have not just a single session of Claude code or Codex or some of these agent harnesses? How can I have more of them? How can I do that appropriately? The agent part is now taken for granted. Now the claw-like entities are taken for granted and now you can have multiple of them and now you can have instructions to them and now you can have optimization over the instructions. But there >> [laughter]
简体中文
“Code”甚至已经不是合适的动词了,?我每天十六个小时都在向智能体表达自己的意图,更准确地说,是把意图‘显化’出来。问题不再是如何运行一个 Claude Code、Codex 或其他 agent harness 会话,而是如何同时运行更多会话、怎样合理地组织它们。智能体本身已经成为默认前提;类似 ‘claw’ 的持久智能体也逐渐成为默认前提。接下来,你可以拥有多个智能体,为它们编写指令,甚至进一步优化这些指令。
00:00:24
Open at 00:00:24 从此处播放
English
>> I mean this is why it gets to the psychosis is that this is like infinite and everything is a skill issue. Hi listeners, welcome back to No Priors. Today I’m here with Andre Karpathy and we have a wide-ranging conversation for you about code agents, the future of engineering and AI research, how more people can contribute to research, what’s happening in robotics, his prediction for how agents can reach out [music] into the real world, and education in this next age. Welcome, Andre.
简体中文
这就是为什么人会进入近乎‘精神失控’的状态:可能性似乎没有边界,所有失败最后都像是 skill issue。各位听众,欢迎回到 No Priors。今天的嘉宾是 Andrej Karpathy。我们将广泛讨论代码智能体、工程与 AI 研究的未来、如何让更多人参与研究、机器人技术的进展、智能体如何延伸到现实世界,以及下一阶段的教育。Andrej,欢迎。
00:00:56
Open at 00:00:56 从此处播放
English
Andre, thanks for doing this. Yeah, thank you for having me. Uh so it’s been a very exciting couple of months in AI. Uh yeah, you could say that. >> I remember um walking into the office at some point and you were like really locked in and I was asking what you were up to and you’re like, I just I have to code for 16 hours a day or code’s not even the right verb anymore, right? But I have to um express my will to my agents for 16 hours a day. Manifest um because like there’s been a jump in capability.
简体中文
Andrej,感谢你参加。——谢谢邀请。——过去几个月 AI 领域极其活跃。——确实可以这么说。——我记得有一次走进办公室,看到你完全沉浸在工作中。我问你在做什么,你说:‘我必须每天编程十六个小时。’但现在‘编程’甚至已经不是准确的动词;你更像是在持续向智能体表达意志,因为模型能力发生了一次明显跃迁。
00:01:26
Open at 00:01:26 从此处播放
English
Uh what’s happening? Tell me about your experience. Yeah, I kind of feel like I was just in this perpetual I still am often in this state of AI psychosis just like all the time um because there was a huge unlock in what you can achieve as a person as an individual, right? Because you were bottlenecked by, you know, your typing speed and so on. But now with these agents it really, I would say in December is when it really just something flipped where I kind of went from 80/20 of like, you know, uh to like 20/80 of writing code by myself versus just delegating to agents. And I don’t even think it’s 20/80 by now. I think it’s a lot more than that. I don’t think I’ve typed like a line of code probably since December basically.
简体中文
究竟发生了什么?你的体验是什么?——我感觉自己一直处于某种持续的 AI psychosis 状态,现在仍经常如此。原因是,个人能够完成的事情突然出现了巨大解锁。过去你的产出受限于打字速度等人类输入带宽;而到了大约十二月,某个开关似乎被拨动了。我从大约 80% 自己写代码、20% 委托智能体,迅速反转到 20% 自己写、80% 委托。现在甚至远不止 20/80。严格说来,我可能从十二月以后就没有亲手输入过一行代码。
00:02:00
Open at 00:02:00 从此处播放
English
>> [laughter] >> Um which is like an extremely large uh change. Um I was talking to it like for example, I was talking about it to for example my parents and so on and I don’t think like a normal person actually realizes that this happened or how dramatic it was. Like literally like if you just find a random software engineer or something like that at their at their desk and what they’re doing, like their default workflow of, you know, building software is completely different as of basically December.
简体中文
这是非常剧烈的变化。我向父母等非技术人士解释时,发现普通人并没有意识到这件事已经发生,更没有意识到它有多么重大。现在随便观察一名坐在工位上的软件工程师,其构建软件的默认工作流,与十二月以前已经完全不同。
00:02:25
Open at 00:02:25 从此处播放
English
Uh so I’m just like in this state of psychosis of trying to figure out like what’s possible, uh trying to push it to the limit. How is it how can I have not just a single session of, you know, um Claude code or Codex or some of these agent harnesses? How can I have more of them? How can I do that uh appropriately? And then how can I use these claws? What are these claws? Uh and uh so there’s like a lot of new things. I want to be at the forefront of it, you know, and I’m very antsy that I’m not at the forefront of it and I see lots of people on Twitter doing all kinds of things and they all sound like really good ideas and I need to be at the forefront or I feel extremely nervous. And so I guess I’m
简体中文
因此,我一直处在探索边界的焦虑状态:怎样不只运行一个 Claude Code、Codex 或其他 harness 会话,而是运行更多?怎样正确组织这些会话?怎样利用这些 claws?claw 究竟应当是什么?新问题不断出现。我希望站在最前沿;当我看到 Twitter 上其他人展示各种似乎非常有效的做法时,如果自己没有立即跟上,就会非常紧张。所以我一直在追问……
Chapter 2: What capability limits remain?
Chapter start 章节起点: 00:02:55
00:02:56
Open at 00:02:56 从此处播放
English
just in this psychosis of like what’s possible like because it’s unexplored fundamentally. Well, if you’re nervous, the rest of us are are nervous. We have a we have a team that we work with at Conviction that their setup is everybody is like, you know, none of the engineers write code by hand and they they’re all microphoned and they just like whisper to their agents all the time. It’s the strangest work setting ever.
简体中文
这种技术从根本上仍处于未探索状态,所以我不断追问:到底可能做到什么?——如果连你都紧张,其他人就更紧张了。我们在 Conviction 合作的一支团队已经采用一种极端工作方式:工程师几乎不手写代码,每个人都戴着麦克风,持续低声向自己的智能体下达指令。整个办公环境非常奇特。
00:03:19
Open at 00:03:19 从此处播放
English
Uh and I thought they were crazy and now I like I fully accept I was like, oh this was the way. Like you’re just ahead of it. Um what uh how do you think about your own capacity now to like explore or to do projects? Like what is it limited by? Yeah, what is it limited by? Uh just I think everything like so many things even if they don’t work, I think to a large extent you feel like it’s a skill issue. It’s not that the capability is not there. It’s that you just haven’t found a way to string it together of what’s available. Like I just don’t I didn’t give good enough instructions in the agents from the file or whatever it may be. I don’t have a nice enough memory tool that I put in there or something like that. So it all kind of feels like skill issue when it doesn’t work to some extent. You want to see how you can parallelize them etc. and you want to be Peter Steinberg basically. Uh so Peter is famous. He has a funny photo
简体中文
起初我觉得他们疯了,现在却完全接受:他们只是提前进入了正确的工作方式。你怎样理解自己当前探索项目的能力边界?现在真正限制你的是什么?——几乎所有问题都可能成为限制,但即使系统没有工作,你往往仍觉得这是 skill issue,而不是基础能力不存在。更像是你尚未找到正确的组合方式:也许给智能体的指令不够好,仓库中的说明文件不够清晰,或者没有合适的 memory tool。于是,任何失败都像是用户技能不足。你会继续尝试并行化,并希望达到 Peter Steinberger 那种工作状态。他有一张很有名的照片。
00:04:04
Open at 00:04:04 从此处播放
English
where he’s in front of a monitor with lots of uh like he uses Codex. So lots of Codex agents tiling the the monitor and they all take about 20 minutes if you prompt them correctly and use the high effort. And so they all take about 20 minutes. They have multiple, you know, 10 repos checked out. And so he’s just um going between them and giving them work. It’s just like you can you can you can move in much larger macro actions. It’s not just like here’s a line of code, here’s a new function.
简体中文
照片里,他面对一块显示器,屏幕上平铺着许多 Codex 智能体窗口。若 prompt 得当并使用较高 reasoning effort,每个任务大约运行二十分钟。他同时检出十个左右的 repository,在多个会话之间不断切换、分配工作。此时操作粒度不再是一行代码或一个函数,而是大得多的 macro action。
00:04:27
Open at 00:04:27 从此处播放
English
It’s like here’s a new functionality and delegate it to agent one. Here’s a new functionality that’s not going to interfere with the other one. Give it agent two. And then try to uh review their work as best as you can >> [laughter] >> depending on how much you care about that code. Like where are these macro actions that I can like manipulate my software repository by? And like another agent is doing some like research, another agent is writing code, another one is coming up with a plan for some new implementation. And so everything is just like happens in these like macro actions over your repository. Um and you’re just trying to become like really good at it and develop like a muscle memory for it is extremely um Yeah, it’s very rewarding number one because it actually works. Uh but it’s also kind of like the new thing to learn. So that’s why hence the psychosis.
简体中文
例如,把一项完整的新功能交给 agent 1;把另一项不会与前者冲突的功能交给 agent 2;随后尽可能审查它们的成果——审查强度取决于你对这段代码有多在意。你开始思考:有哪些宏观操作可以直接改变整个软件仓库?一个智能体做研究,一个智能体写代码,另一个智能体为新实现制定方案。所有活动都以 repository 级的 macro action 发生。你要训练新的肌肉记忆,熟练组织这些动作。它令人上瘾,一方面因为确实有效,另一方面因为这本身就是一项全新的技能。
00:05:07
Open at 00:05:07 从此处播放
English
Yeah, I I do feel like my instinct is like whenever I’m waiting for an agent to complete something, the obvious thing to do is like, well, I can do more work, right? Like if I have access to more tokens then like I should just parallelize at tasks. And so that’s that’s very stressful because if you don’t feel very bounded by your ability to spend on tokens, then you know, you are the bottleneck in the system that is max capability. Yeah, if you’re not maximizing your subscription at least.
简体中文
我的本能也是:只要有一个智能体还在运行,就应该立即启动更多任务。只要还有 token 可用,就应当把任务并行化。这样会带来很大压力:如果 token 开销并不构成硬约束,那么系统达到最大能力时,真正的瓶颈就是你本人。——至少应该把订阅额度用满。
00:05:34
Open at 00:05:34 从此处播放
English
And ideally for multiple agents. Like if you run out of the quota on Codex, you should switch to Claude or whatnot. I don’t know. Like that’s what I’ve been trying to do a little bit and I feel nervous when I have subscription left over. That just means I haven’t maximized my token throughput. So I actually kind of experienced this when I was a PhD student. You would feel nervous when your GPUs are not running.
简体中文
理想情况下,还应同时使用多个供应商的智能体。Codex 配额用完,就切换到 Claude 或其他系统。我也在尝试这样做;只要订阅额度还有剩余,我就会紧张,因为这说明自己没有最大化 token throughput。这让我想起博士阶段:当 GPU 没有运行时,你会感到不安。
00:05:51
Open at 00:05:51 从此处播放
English
Like you have GPU capability and you’re not maximizing your the available flops to you. But now it’s not about flops, it’s about tokens. So what is your token throughput and what token throughput do you command? I would actually argue that it’s very interesting that we had, you know, at least 10 years where in many engineering tasks people just did they didn’t feel compute bound.
简体中文
你已经拥有 GPU 资源,却没有充分利用可用 FLOPs。现在对应的资源不再是 FLOPs,而是 tokens。关键问题变成:你的 token throughput 是多少,你能够调度多大的 token throughput?过去至少十年,在很多工程任务中,人们通常不觉得自己受 compute 限制,这一点很有意思。
00:06:12
Open at 00:06:12 从此处播放
English
Right? Um and now the entire industry feels that now. They feel like they they
简体中文
而现在,整个行业突然重新感到资源受限;模型能力发生跃迁之后,人们意识到,限制不再是能否访问计算机,而是自己能否有效调度计算。
Chapter 3: What mastery of coding agents looks like
Chapter start 章节起点: 00:06:15
00:06:16
Open at 00:06:16 从此处播放
English
they felt resource bound uh and now that you have this big capability jump, you’re like, oh, actually it’s not, you know, my ability to access the computer anymore. Like I’m I’m the binding constraint. Yeah, it’s a skill issue. Which is very empowering cuz um yeah, cuz you could be getting better. So that’s why that’s why I think it’s very addictive because there’s unlocks when you when you get better.
简体中文
人自身成为 binding constraint。——所以还是 skill issue。这反而很有赋权感,因为它意味着你可以通过提升技能继续解锁能力。这也是它如此容易令人沉迷的原因:每当你掌握一种更好的工作方式,就会出现新的产出跃迁。
00:06:37
Open at 00:06:37 从此处播放
English
Where do you think it goes? Like if you just think about like, okay, you know, Andre’s iterating and everybody else is for 16 hours a day getting better at using coding agents. Like what does it look like in a year? Of like you’ve reached mastery. >> [laughter] >> Yeah, what does mastery look like, right? At the end of the year or like two, three years, five years, 10 years, etc.
简体中文
未来会走向哪里?假设 Andrej 和其他人每天十六个小时练习使用代码智能体,一年后所谓‘精通’会是什么样?两年、三年、五年甚至十年后的 mastery 又意味着什么?
00:06:55
Open at 00:06:55 从此处播放
English
Well, I think everyone is basically interested in like going up the stack. So I would say it’s yeah, it’s not about a single session with your agent. Multiple agents, how do they collaborate and teams and so on. So everyone’s trying to figure out what that looks like. And then I would say Claude is also kind of an interesting direction because it really, when I say a Claude, I mean this like layer that kind of takes persistence to a whole new level.
简体中文
所有人都在尝试向技术栈更高层移动。重点不再是一个人和一个智能体的单次会话,而是多个智能体如何组成团队、如何协作。大家都在探索这一形态。另一个重要方向是 OpenClaw 这类持久智能体层:它把 persistence 提升到新的水平。
00:07:14
Open at 00:07:14 从此处播放
English
Like it’s something that like keeps looping. It’s it’s like um it’s not something that you are interactively in the middle of. It kind of like has its own little sandbox, its own little you know, it kind of like does stuff on your behalf even if you’re not looking kind of thing. Um and then also has like maybe more sophisticated memory systems etc. that are not yet implemented in agents. So um Open Claude has a lot more sophisticated memory I would say than what you would get by default uh which is just a memory compaction when your context runs out, right? You think that’s the piece that resonated for more users versus like perhaps like broader tool access? For Open Claude? Yeah. Uh there’s like I think there’s at least five things that are really good ideas in here. Yeah, good job, Peter. I mean Peter has done a really amazing job. Um I saw him recently. Uh and I talked to him about it and I he’s very humble
简体中文
这类系统会持续循环运行,而不是要求人始终处于交互中心。它拥有自己的 sandbox,可以在你没有注视时代表你处理任务,也可能具备比普通代码智能体更复杂的 memory system。默认智能体通常只在 context window 耗尽时做一次 memory compaction;OpenClaw 的记忆明显更复杂。——相比更广泛的工具权限,你认为持久性和记忆正是它吸引更多用户的原因吗?——我认为其中至少同时包含五项很好的创新。Peter 做得非常出色。我最近见到他时,他本人很谦逊。
00:07:58
Open at 00:07:58 从此处播放
English
about it. But I think he innovated simultaneously in like five different ways and put it all together. Um so for example like the soul and D document. Like he actually really crafted a personality that is kind of compelling and interesting. And I feel like a lot of the current agents they don’t get this correctly. I actually think a Claude has a pretty good personality. It feels like a teammate uh and it’s excited with you etc.
简体中文
但我认为他在五个方向上同时创新,并把它们整合成了一个系统。例如 `SOUL.md` 等人格设定文档确实塑造出有吸引力的 personality。许多当前智能体并没有处理好这一层。Claude 的人格相对不错,使用时更像一个与你共同工作的 teammate,也会对你的进展表现出兴奋。
00:08:29
Open at 00:08:29 从此处播放
English
I would say um for example Codex is a lot more dry um which is kind of interesting because [laughter] in it’s true. You know, it doesn’t it and the other thing I would say is for example with Claude I think they dialed the sycophancy fairly well where when Claude gives me praise, I do feel like I slightly deserve it because sometimes I kind of give it like not very well formed thoughts and uh I give it an idea that I don’t think it’s fully baked and it doesn’t actually react very strongly.
简体中文
相比之下,Codex 更为干燥和工具化。另一个差异是,Claude 对 sycophancy 的调节比较准确。当它表扬我时,我有时确实觉得自己略微配得上这种肯定。因为当我给出一个尚未成形、自己也不确定的想法时,它通常不会过度反应。
00:08:51
Open at 00:08:51 从此处播放
English
It’s like, oh yeah, we can implement that. But when it’s a really good idea by my own account, it does uh seem to reward it a bit more. And so I kind of feel like I’m trying to like earn its praise which is really weird. And so I do think the personality matters a lot uh and I think a lot of the other uh tools maybe don’t appreciate it as much. And I think in this aspect also Peter really cares about this and so that was correct. And then the memory system and then uh just, you know, he’s just having fun with this um and then the the single WhatsApp portal to all of the automation.
简体中文
它可能只说‘可以实现’;但当我自己也认为某个想法确实很好时,它的积极反馈会明显增强。结果我甚至会产生一种试图赢得它表扬的奇怪心理。因此,personality 的确非常重要,其他工具可能低估了这一点。Peter 显然很重视它。除此之外,还有记忆系统、持续运行的趣味性,以及通过单一 WhatsApp portal 接入全部自动化。
00:09:18
Open at 00:09:18 从此处播放
English
>> Yeah. Is there something that you have done personally with your claws beyond software engineering that you think is fun or interesting? Yeah, so in January I had a claw I went through a period of claw psychosis. So I built um I have a claw basically that takes care of my home and I call him Dobby the elf uh claw. Um and uh basically I used uh the agents to find all of the smart home subsystems of my home on the local area network which I was kind of surprised that it worked out of the box. Like I just told it that I think I have Sonos at home.
简体中文
你有没有在软件工程之外,用自己的 claw 做过有趣的事情?——今年一月,我经历了一段 ‘claw psychosis’。我构建了一个负责管理家庭的 claw,称它为精灵 Dobby。通过智能体,我让它自动发现本地局域网中的全部 smart-home subsystem。令我惊讶的是,这几乎开箱即用。我只告诉它:家里应该有 Sonos。
00:09:48
Open at 00:09:48 从此处播放
English
Like can you try to find it? And it goes and it did like IP scan of all of the um basically um computers on the local area network and and found the Sonos thing uh the Sonos uh, system and it turned out that there’s no password protection or anything like that. It just logged in and it’s like, “Oh, yeah, you have these Sonos systems installed. I Let me try to reverse engineer how it’s working.” It does some web searches and it finds like, “Okay, these are the API endpoints.” And then it’s like, “Do you want to try it?” And I’m like, “Whoa, like you just did that.” And I’m like, “Yeah, can you try to play something in the study?” And, uh, it does and music comes out and I’m like, “I can’t believe I just That’s crazy. That’s like three prompts. Yeah.
简体中文
我问它能否找到 Sonos。它扫描局域网上所有设备的 IP,发现了 Sonos 系统。该系统似乎没有额外密码保护,它直接接入后说:‘你安装了这些 Sonos 设备,我来分析其工作方式。’随后它搜索网页,找到 API endpoints,并询问是否要测试。我让它在书房播放音乐,音乐真的响了。整个过程大约只有三个 prompt,令人难以置信。
00:10:20
Open at 00:10:20 从此处播放
English
>> I can’t believe I just typed in like, “Can you find my Sonos?” and then suddenly it’s playing music. And it did the same for lights. And so like it kind of hacked in, figured out the whole thing, uh, created APIs, created dashboard so I could see the command, uh, kind of center of like all of my lights in the home. And then it was like switching lights on and off and, you know, so I can ask it like, “Dobby, it’s sleepy time.” And when it’s sleepy time that just means all the lights go off, etc. and like so on. So it controls all of my lights, my HVAC, my shades, uh, the pool and, uh, the spa and also my security system. So I have a camera pointed outside of the house and anytime someone rolls in I have a Quinn, uh, a Quinn, uh, model that looks at the videos. So first of all there’s change detection. Right.
简体中文
我只输入‘能否找到我的 Sonos’,几步之后它就开始播放音乐。对灯光系统也是如此:它自行发现协议、建立 API 和 dashboard,让我看到并控制家中所有灯光。我可以说:‘Dobby,该睡觉了。’这会触发全部灯光关闭。它现在控制灯光、HVAC、窗帘、泳池、spa 以及部分安防系统。屋外摄像头的视频先进行 change detection;检测到变化后,再交给一个 Qwen 视觉模型分析。
00:10:59
Open at 00:10:59 从此处播放
English
>> And then based on change detection it goes to Quinn and then it actually like tells me, um, it sends me a text to my WhatsApp. It shows an image from the outside and it says, “Hey, a FedEx truck just pulled up. FedEx truck just pulled up and you might want to check it and you got new mail or something like that.” And Dobby just text me this. This is really incredible. Um, so so Dobby is
简体中文
视觉模型完成分类后,Dobby 会通过 WhatsApp 给我发送消息,附上屋外截图,例如:‘一辆 FedEx 卡车刚刚驶入,你可能需要查看,可能有新的快件。’由家庭智能体主动完成这种通知,确实非常惊人。于是,Dobby……
Chapter 4: Second-order effects of natural-language coding
Chapter start 章节起点: 00:11:16
00:11:18
Open at 00:11:18 从此处播放
English
in charge of the house. I text through with it through WhatsApp, um, and it’s been like really fun to have these macro actions that maintain my house. I haven’t like really pushed it, uh, like way more beyond that and I think people are doing a lot more crazy things with it, uh, but for me even just the home automation setup I used to use like six apps, uh, completely different apps and I don’t have to use these apps anymore. Like Dobby controls everything in natural language. It’s amazing. Um, and so I think like I haven’t even pushed the paradigm fully but already that is so helpful and so inspiring I would say. Do you think that’s indicative of like what people want from a user experience perspective with software, right? Because I I don’t think, you know, it’s pretty ignored that it takes humans effort to like learn new software, like new UI. Yeah. I think, uh, to some extent that’s right.
简体中文
Dobby 现在负责管理整个住宅。我通过 WhatsApp 与它交流,由它执行维护家庭环境的 macro action。虽然我还没有把这一范式推到更远——其他人可能已经在做更激进的事情——但仅家庭自动化就非常有价值。过去我需要使用六个彼此独立的应用,现在这些应用都不必再打开;Dobby 可以用自然语言控制全部设备。即使还没有充分挖掘这种范式,它已经非常实用并且具有启发性。——从软件用户体验的角度看,这是否反映了人们真正想要的交互方式?学习每一套新软件和 UI 本身需要人类投入,但这一成本通常被忽视。——在一定程度上确实如此。
00:12:00
Open at 00:12:00 从此处播放
English
It’s like working backwards from how people think an AI should be because what people have in their mind of like what an AI is is not actually what an LLM is by by like in the raw sense. Like LLM is a token generator, you know, like more tokens come out. But what they think of is like this this persona identity that they can tell stuff and it remembers it, you know?
简体中文
这相当于从人们心目中‘AI 应当是什么’倒推产品形态。普通人对 AI 的直觉,并不是原始意义上的 LLM。裸 LLM 本质上只是 token generator:输入一些 token,再生成更多 token。但人们期待的是一个具有 persona 和 identity 的实体,可以向它交代事情,而且它会记住。
00:12:19
Open at 00:12:19 从此处播放
English
And, uh, it’s just kind of an entity behind the WhatsApp. It’s like a lot more understandable. Mhm. Uh, so I think to some extent it’s like matching the expectations that humans already have for what an AI should behave but under the hood it’s like a lot of technical details go into that. And LLMs are too raw of a primitive, uh, to actually, um, type check as AI I think for most people if that makes sense. Yeah. Um, I think that’s like how we understand what the AI is and like the, um, description of it as Dobby or some persona obviously resonates with people. Um, I also think that it it uh, the unification that you did across your six different software systems for your home automation speaks to a different question of like do people really want all of the software that we have today? Yeah.
简体中文
WhatsApp 背后存在一个持续工作的实体,这种形态更符合人类直觉。为了达到这种体验,底层需要大量工程细节。对多数用户而言,原始 LLM 作为一种 primitive 过于底层,并不能自然地‘类型检查’为人们所理解的 AI。Dobby 这样的名称和人格使系统更容易理解。同时,你把六套家庭软件统一起来,也提出了另一个问题:人们真的需要今天这些相互割裂的软件吗?
00:13:00
Open at 00:13:00 从此处播放
English
Right? Um, because I I would argue like, well, you have the hardware but you’ve now thrown away the software or the UX layer of it. Um, do you think that’s what people want? Yeah, I think there’s this like there’s this sense that these apps that are on the app store for using these smart home devices, etc. Uh, these shouldn’t even exist kind of in a certain sense. Like shouldn’t it just be APIs and shouldn’t agents be just using it directly? And, um, wouldn’t it like I can do all kinds of home automation stuff that, uh, in any individual app will not be able to do, right? Um, and an LLM can actually drive the tools and call all the right tools and do uh, do pretty complicated things. Um, and so in a certain sense it does point to this like maybe there’s like an overproduction of lots of custom bespoke apps that shouldn’t exist because agents kind of like crumble them up and everything should be a lot more just
简体中文
硬件仍然存在,但你已经丢弃了各设备原有的软件与 UX 层。用户真正想要的是这种结果吗?——我认为,用于控制 smart-home 设备的许多 App Store 应用,在某种意义上本来就不应存在。设备更合理的形态应是开放 API,由智能体直接调用。单个厂商应用无法完成跨设备的复杂自动化,而 LLM 可以驱动多种工具、调用正确接口,并组合出相当复杂的行为。这说明行业可能过度生产了大量 bespoke app;智能体会把这些应用层压缩掉,底层只需暴露 API endpoints。
00:13:47
Open at 00:13:47 从此处播放
English
like exposed API endpoints and agents are the glue of the intelligence that actually like tool calls all the all the parts. Um, another example is like my treadmill. Uh, there’s an app for my treadmill and I wanted to like keep track of how often I do my cardio, uh, but like I don’t want to like log into web UI and go through a flow and etc. Like all this should just be like make APIs available and this is kind of, you know, going towards the agentic, um, sort of web or like agent first, uh, tools and all this kind of stuff. So I think the industry just has to reconfigure in so many ways that’s like the customer is not the human anymore.
简体中文
智能体成为连接各部分的智能胶水,统一进行 tool call。另一个例子是跑步机。它有自己的应用,我想记录自己进行有氧训练的频率,却不想登录网页、经过多步操作。更合理的设计是直接提供 API。这正指向 agentic web 或 agent-first tool:行业必须进行大规模重构,因为未来的直接客户不再只是人类。
00:14:18
Open at 00:14:18 从此处播放
English
It’s like agents who are acting on behalf of humans and this refactoring will be will probably be substantial in a certain sense. One way that people sometimes push back on this is like, do people Do you Do we expect people to write code some of these tools? Do we expect normal people to do this kind of stuff that I described? Mhm. But I think to some extent this is just, you know, technology as it exists today and right now there is some write coding and I’m actually watching it and I’m working with the system but I kind of feel like this kind of stuff that I just talked about this should be free like in a year or two or three.
简体中文
客户将越来越多地是代表人类行动的智能体,这次 refactoring 会非常深。一种常见质疑是:普通人是否需要为这些工具写代码?是否能完成我刚才描述的配置?在今天,确实仍然需要一些 vibe coding,我也会观察并协助系统。但我认为,一两年或三年以后,这类能力应当接近免费。
00:14:48
Open at 00:14:48 从此处播放
English
There’s no write coding involved. This is trivial. This is table stakes. This is like any AI, even the open source models, etc. can like do this. You should be able to translate it from a less technical humans intent very easily to this outcome. >> Yeah. Today it’s write coding and it’s involved and not many people are going to do it but >> And you still have to make some design decisions, right? We were talking about like we take frames for example. Yeah.
简体中文
那时不会再涉及人工写代码;这会成为 table stakes。任何 AI,甚至 open-source model,都应能把非技术用户的意图直接转换成目标结果。今天它仍然需要编程参与,因此只有少数人会做;而且用户仍需作出部分设计决策,例如选择应采集哪些 frame。
00:15:08
Open at 00:15:08 从此处播放
English
Yeah. But I kind of feel like this will just, uh, start to the barrier will just come down and it’s just ephemeral software on your behalf and some kind of like claw is handling all the details for you but you’re not involved. Claw has a Claw has a machine and it will figure it out and it’s just presenting you UIs and you’re like saying stuff, you know? Mhm.
简体中文
但门槛会不断下降。软件将成为为你临时生成的 ephemeral software;某个 claw 在后台处理全部细节,你不再参与具体实现。它拥有一台可执行操作的机器,自行解决问题,只向你呈现必要 UI,而你只需表达意图。
00:15:27
Open at 00:15:27 从此处播放
English
Why haven’t you, um, I guess like pushed the boundaries of what you can do personally with claws? Like is it, you know, you’re focusing on more important projects, auto research, etc. or, uh, you’re climbing the hill to mastery or something else, right? Yeah, I just feel like I’m so distracted by everything so I spend I [laughter] spend like a week on the claw stuff and I I have more to do almost, um, but I will say that, um, >> It’s like Jensen told us we’re all just
简体中文
为什么你没有继续扩展自己使用 claws 的边界?是因为正在专注于 AutoResearch 等更重要项目,还是仍处于学习 mastery 的阶段?——主要原因是所有方向都同时吸引我的注意力。我大约花了一周研究 claw,仍有很多想做的事;但正如 Jensen 所说,我们最终只是变得更加忙碌。
Chapter 5: Why AutoResearch
Chapter start 章节起点: 00:15:51
00:15:51
Open at 00:15:51 从此处播放
English
busier, unfortunately. >> Uh, I didn’t really take advantage of a lot of like email and calendar and all this other stuff and I didn’t really have access cuz I’m still a little bit like suspicious and it’s still very new and rough around the edges. So I didn’t want to give it like full access to my digital life yet and part of it is just the security, privacy and uh, just being very cautious in that in that realm.
简体中文
遗憾的是,确实更忙了。我没有让 Dobby 深入接管 email、calendar 等数字生活,也没有给它完整访问权限,因为这一技术仍然非常新,边缘粗糙,我仍保持怀疑。安全、隐私以及谨慎授权是重要原因。
00:16:11
Open at 00:16:11 从此处播放
English
And, um, so some of it is like held back by that I would say. Yeah, maybe that’s like the dominant dominant feature but some of it is also just I feel so distracted because I feel like I had a week of claw and then other stuff is happening and What was the, um, I mean you’ve talked about like being able to train or at least optimize a uh, a a model as a task you want to see agents do for a long time. Like what was the motivation behind auto research? Auto research, yeah. So I think like I had a tweet earlier where I kind of like said something along the lines of to get the most out of the tools that have become available now you have to remove yourself as the as the bottleneck. You can’t be there to prompt the next thing. You’re You need to take yourself outside. Um, you have to arrange things such that they’re completely autonomous. And the more you you know, how can you maximize your token throughput and not be in the loop?
简体中文
这可能是限制进一步使用的主导因素,另一个原因则是注意力不断被新事物打断:研究 claw 一周后,其他方向又迅速出现。——你长期希望智能体能够训练或至少优化模型。AutoResearch 的动机是什么?——我之前发过一条推文:要充分利用当前出现的工具,必须把自己从 bottleneck 的位置移走。你不能始终等在那里,为系统发出下一条 prompt;必须把人移出执行回路,把系统组织成可以完全自治的形态。目标是最大化 token throughput,同时不让人持续处于 in the loop。
00:16:56
Open at 00:16:56 从此处播放
English
This is the this is the goal. And so I kind of mentioned that the the name of the game now is to increase your leverage. Uh, I put in just very few tokens just once in a while and a huge amount of stuff happens on my behalf. And so auto research like I tweeted that and I think people liked it and whatnot but it they haven’t like maybe worked through like the implications of that and for me auto research is an example of like an implication of that. Where it’s like I don’t want to be like the researcher in loop like looking at results, etc. Like I’m I’m holding the system back. So the question is how do I refactor all the abstractions so that I’m not I have to arrange it once and hit go. The name of the game is how can you get more agents running for longer periods of time without your involvement doing stuff on your behalf? And auto research is just, yeah, here’s an objective, here’s a metric, here’s your boundaries of what
简体中文
当前竞争的核心是提高 leverage:人偶尔只投入很少 token,却让大量工作代表自己持续发生。很多人喜欢那条推文,但未必彻底推演了它的含义。AutoResearch 就是这一逻辑的具体结果。我不想作为 researcher in the loop,不想亲自查看每次实验结果,因为我反而会拖慢系统。真正的问题是:如何重构所有抽象,使人只需完成一次布置,然后按下启动键?如何让更多智能体在无人干预下运行更长时间?AutoResearch 的输入很简单:给出 objective、metric,以及允许与禁止的边界。
00:17:38
Open at 00:17:38 从此处播放
English
you can and cannot do. And go. And, uh, yeah, it worked. >> at its effectiveness. Yeah, I I didn’t expect, uh, it to work because so I have the project data chat, um, and fundamentally like I think a lot of people are very confused with my obsession for like training GPT-2 models and so on. But for me, uh, training GPT models and so on is just a little harness, a little playground for training LLMs. And fundamentally what I’m more interested in is like this idea of recursive self-improvement and to what extent you can actually have LLMs improving LLMs because I think all the frontier labs this is like the thing Mhm. uh, for obvious reasons and they’re all trying to recursively self-improve roughly speaking. And so for me this is kind of like, um, a little playpen of that. Um, and I guess I like tuned Nan Chat already quite a bit by hand in the good old fashion way that I’m used to.
简体中文
然后让它开始运行。结果确实有效,我自己也没有预料到。我的项目是 nanochat;很多人不理解我为什么一直训练 GPT-2 规模的模型。对我而言,训练小型 GPT 只是一个 LLM training harness 和实验场。我更关心的是 recursive self-improvement:LLM 在多大程度上能够改进 LLM。出于显而易见的原因,所有 frontier lab 都在尝试某种形式的递归自我改进。AutoResearch 是一个缩小版试验场。在此之前,我已经按照传统研究方式手工把 nanochat 调得相当充分。
00:18:21
Open at 00:18:21 从此处播放
English
Like I’m a researcher. I’ve done this for like, you know, two decades. I have some amount of like What is the opposite of hubris? Uh, yeah. [laughter] Earned confidence? Okay. I have like two decades of like, “Oh, I’ve trained this model like thousands of times. I’ve like, um, so I’ve done a bunch of experiments. I’ve done hyperparameter tuning. I’ve done all the things I’m very used to and I’ve done for two decades. Yeah. And I’ve gotten to a certain point and I thought it was like fairly well tuned and then I let auto research go for like overnight and it came back with like tunings that I didn’t see. Mhm. And yeah, I did forget like the weight decay on the value embeddings and my Adam betas were not sufficiently tuned and these things just jointly interact. So like once you tune one thing the other things have to potentially change too.
简体中文
我做研究接近二十年,训练同类模型成千上万次,积累了某种‘经过验证的信心’。我进行了大量实验和 hyperparameter tuning,以为仓库已经达到相当良好的配置。但让 AutoResearch 运行一夜后,它找到了我遗漏的调整:例如 value embedding 上的 weight decay,以及没有充分优化的 Adam betas。更重要的是,这些参数会联合交互;一个参数变化后,其他参数的最优值也可能随之改变。
00:18:59
Open at 00:18:59 从此处播放
English
You know, I shouldn’t be a bottleneck. I shouldn’t be running these hyperparameter optimizations. I shouldn’t be looking at the results. There’s objective criteria in this case. Uh, so you just let you just have to arrange it so that it can just go forever. So that’s a single sort of version of auto research of like a single loop trying to improve. And I was surprised that it, um, it found these things that I you know, the repo was already fairly well tuned and still found something.
简体中文
这说明我不应成为瓶颈,也不应亲自运行这些 hyperparameter optimization 或逐项查看结果。在这种任务中存在客观评价标准,因此只需把系统安排成能够无限持续运行。当前 AutoResearch 只是一个单一循环,持续尝试改进;即便仓库已经过较充分手工调优,它仍找到了有效提升,这一点让我意外。
00:19:19
Open at 00:19:19 从此处播放
English
And that’s just a single it’s a single loop. Like these frontier labs they have GPU clusters of tens of thousands of them. And so it’s very easy to imagine how you would basically get a lot of this automation on, um, smaller models. And fundamentally everything around like frontier level intelligence is about extrapolation and scaling loss. And so you basically do a ton of the exploration on the smaller models and then you try to, um, extrapolate out. So you’re saying our research efforts are going to get more efficient. Like we’re going to have better direction for when we scale as well if we can do this experimentation better.
简体中文
而这还只是一个 loop。前沿实验室拥有数以万计的 GPU 集群,很容易想象如何在小模型上大规模自动化此类研究。Frontier-level intelligence 很大程度上依赖 extrapolation 和 scaling law:先在较小模型上进行大量探索,再把规律外推到大规模训练。——也更好的自动实验不仅使研究本身更高效,还会让最终规模化时的方向选择更准确。
00:19:50
Open at 00:19:50 从此处播放
English
>> Yeah, I would say that like the most interesting project and probably what the frontier labs are working on is uh, Mhm. Yeah. you know, you experiment on the smaller models. You try to make it as autonomous as possible. Remove researchers >> [laughter] >> from the loop. They have way too much What is the What is the opposite of too much confidence? Yeah, yeah, they don’t know. They shouldn’t be touching any of this really. And so you have to like rewrite the whole thing because right now, I mean certainly they can contribute ideas. But okay, they shouldn’t actually be enacting these ideas. There is a queue of ideas and there’s maybe an automated scientist that comes up with ideas based on all the archive papers and GitHub repos and it funnels ideas in or researchers can contribute ideas, but it’s a single queue and there is workers that pull items and they try them out. And whatever works just gets sort of put on
简体中文
我认为最有价值、而且 frontier lab 很可能正在开展的项目,就是在小模型上尽量自治地实验,并把研究人员从执行回路移除。研究人员当然可以贡献 idea,但不应亲自实施每个想法。可以建立一个统一 idea queue:自动 scientist 从 arXiv 论文和 GitHub repository 中提出想法,研究人员也可以提交想法;随后大量 worker 从队列领取任务并执行。有效结果自动进入 feature branch。
00:20:32
Open at 00:20:32 从此处播放
English
the feature branch and maybe some people like monitor the feature branch and merge to the main branch sometimes. So yeah, just removing humans from all the processes and automating as much as possible and getting high token tokens per second throughputs and it does require rethinking of all the abstractions and everything has to be reshuffled. So yeah, I think it’s very exciting. If we take one more recursive step here, when is the model going to write a better program MD than you?
简体中文
人类只需偶尔监控 feature branch,并在合适时合并到 main branch。总体方向是从尽可能多的流程中移除人工,最大化自动化和 tokens-per-second throughput。这要求重新思考所有抽象、重新排列整个研究组织。——如果再递归一步,模型什么时候会写出比你更好的 `program.md`?
00:21:01
Open at 00:21:01 从此处播放
English
Yeah. Also program MD is like >> loop. Yeah, exactly. >> Yeah. So program MD is my crappy attempt at describing like how the auto researcher should work. Like oh, do this then do that and that and then try these kinds of ideas and then here’s maybe some ideas like look at architecture, look at optimizer, etc. But I just came up with with this in markdown, right?
简体中文
`program.md` 本身当然也处在这个 loop 中。它只是我用 Markdown 粗略描述 AutoResearcher 应如何工作的尝试:先做什么、再做什么、可以尝试哪些类型的 idea,例如检查 architecture 或 optimizer。它并不神秘,只是我写下的一组指令。
00:21:20
Open at 00:21:20 从此处播放
English
>> Mhm. And so yeah, exactly. You want some kind of an auto research loop maybe that looks for You can imagine that different program that MDs would would give you different progress. So you basically every research organization is described by program MD. A research organization is a set of markdown files that describe all the roles and how the whole thing connects.
简体中文
不同的 `program.md` 很可能带来不同研究进展。可以把每一个研究组织都描述为一组 Markdown 文件,其中定义所有 role、流程以及它们的连接方式。于是,整个 research organization 都可以被编码为 `program.md`。
00:21:44
Open at 00:21:44 从此处播放
English
And you can imagine having a better research organization. So maybe they do fewer stand-ups in the morning because they’re useless. And this is all just code, right? And so you can So one organization can have fewer stand-ups, one organization can have more. One organization can be very risk-taking, one organization can be less. As you can definitely imagine that you have multiple research orgs and then they all have code. And once you have code, then you can imagine tuning the code. So 100% there’s like the metal layer of it. Uh Did you see my text about my contest idea? My contest idea was like let people write different program MDs, right? And and so for same hardware, where do you get most improvement?
简体中文
不同组织可以有不同制度:有的减少无用晨会,有的增加同步;有的更愿意冒险,有的更加保守。这些差异都变成代码。既然多个 research org 都有可执行的代码,就可以进一步优化这些代码,形成明确的 meta layer。我曾提出一个竞赛设想:让不同人编写不同的 `program.md`,在相同硬件条件下比较谁能获得最大研究改进。
00:22:22
Open at 00:22:22 从此处播放
English
>> Oh, I see. And then you can take all that data and then give it to the model and say write a better program MD. >> Yes, yes. Yeah, exactly. >> We’re going to get something better. Like there’s no way we don’t, right? >> 100% look at where the improvements came from and like can I change the program MD such that more of these kinds of things would be done or like things that didn’t work except you can 100% imagine doing that. So I think this is a great idea, but it’s
简体中文
随后把全部实验数据交给模型,让它根据改进来源写出更好的 `program.md`。几乎没有理由认为它不会得到更好的版本。模型可以分析哪些组织策略带来有效提升、哪些尝试失败,再修改指令,使未来更频繁地产生高价值实验。这条递归路径完全可行。不过,它还只是下一层。
Chapter 6: Relevant skills in the AI era
Chapter start 章节起点: 00:22:45
00:22:45
Open at 00:22:45 从此处播放
English
like you know, I think like you can sort of go one step at a time where you sort of have one process and then second process and then the next process and these are all layers of an onion. Like the LLM sort of part is now taken for granted. The agent part is now taken for granted. Now the claw-like entities are taken for granted and now you can have multiple of them and now you can have instructions to them and now you can have optimization over the instructions and it’s just like a little too much, you know, but I mean this is why it gets to the psychosis is that this is like infinite and everything is scale issue and that’s why I feel like Yeah, that’s just coming back to This is why it’s so insane. Okay, well, if [laughter] we’re we’re just trying to like diagnose the current moment and what is a relevant skill right now, what do you like what do you think is the implication that this
简体中文
整个系统可以一层层向上构建。最初 LLM 成为默认 primitive;随后 agent 成为默认;接着 claw 这类持久实体成为默认;再往上是多个 claw、对它们的指令,以及对指令本身的优化。每一层都包裹下一层,像不断增加的洋葱层。这也是人会进入 AI psychosis 的原因:可能性似乎无限,所有问题都像是 scale issue 或 skill issue。——如果我们只是想诊断当前阶段,判断什么技能最相关,那么这种递归 loop 的现实含义是什么?
00:23:26
Open at 00:23:26 从此处播放
English
that this is the loop we should be trying to achieve in different areas and then it works, right? Like you know, remove create the metric or create the ability for agents to continue working on it without you. Do we still have performance engineering? Like what Yeah, I mean so there’s a few caveats that I would put on top of the LLM psychosis. So number one, this is extremely well suited to anything that has objective metrics that are easy to evaluate. So for example, like writing kernels for more efficient CUDA, you know, code for various parts of the model, etc. are a perfect fit because you have inefficient code and then you want efficient code that has the exact same behavior but it’s much faster.
简体中文
是否应在不同领域都尝试建立这样的 loop:先创造 metric,再让智能体在没有人的情况下持续工作?Performance engineering 是否仍然存在?——需要在这种 LLM psychosis 上加几个重要限制。第一,它特别适合具有客观且易评价指标的任务。例如,为模型不同组件编写更高效的 CUDA kernel 就是完美场景:现有代码行为正确但效率低,目标是保持完全相同行为,同时显著提升速度。
00:24:02
Open at 00:24:02 从此处播放
English
Perfect fit. So a lot of things like like are perfect fit for auto research, but many things will not be. And so they it’s just if you can’t evaluate then you can’t auto research it, right? So that’s like caveat number one. And then maybe caveat number two I would say is you know, we’re we’re kind of talking about the next steps and we kind of see what the next steps are, but fundamentally the the whole thing still doesn’t it still kind of like bursting at the seams a little bit and there’s cracks and it doesn’t fully work and if you kind of try to go too far ahead, the whole thing is actually net not useful if that makes sense.
简体中文
很多问题确实非常适合 AutoResearch,但也有许多不适合。若无法评价,就无法自动研究,这是第一项 caveat。第二,我们虽然能够看到下一步方向,但当前系统本身仍有明显裂缝,整体仿佛正从接缝处向外膨胀,并没有完全可靠。如果过早跨越太多层,最终系统可能反而没有实际效用。
00:24:31
Open at 00:24:31 从此处播放
English
Because these models like still are not, you know, they’ve improved a lot, but they’re still are like rough around the edges is maybe the way I would describe it. I simultaneously feel like I’m talking to an extremely brilliant PhD student who’s been like a systems programmer for their entire life and a 10-year-old. And it’s so weird because humans like there’s like I feel like they’re a lot more coupled like you have to you know, um Yes, you wouldn’t you wouldn’t encounter that combination.
简体中文
模型已经取得很大进步,但边缘仍然粗糙。我有时感觉自己同时在与两种角色交谈:一个终身从事 systems programming、极其聪明的 PhD student,以及一个十岁儿童。这个组合非常奇怪;在人类身上,这两类能力通常更加耦合,不太会以如此极端方式并存。
00:24:55
Open at 00:24:55 从此处播放
English
>> This jaggedness is really strange and humans have a lot less of that kind of jaggedness, although they definitely have some. >> [laughter] >> But humans have a lot more jaggedness. Uh sorry, the agents have a lot more jaggedness where sometimes like you know, I ask for functionality and it like comes back with something that’s just like totally wrong and then we get into loops that are totally wrong and then I’m just I get so frustrated with the agents all the time still because you feel the power of it, but you also there’s still like it does not say statistical things once in a while for me as well. I get very annoyed [clears throat] when I feel like the agent wasted a lot of compute on something it should have recognized was an obvious problem. Yeah.
简体中文
智能体的 jaggedness 远高于人类。它有时会对功能要求返回完全错误的实现,随后陷入错误循环。我仍经常对智能体感到挫败:你能清楚感受到它的强大,却也会偶尔看到极不合理的行为。当它在本应立即识别的问题上浪费大量 compute 时,我尤其恼火。
00:25:34
Open at 00:25:34 从此处播放
English
I think like some of the bigger things is like maybe what’s under underneath it if I could hypothesize is fundamentally these models are trained via reinforcement learning. So they’re actually struggling with the exact same thing we just talked about which is the labs can improve the models in anything that is verifiable or that [clears throat] has rewards. So did you write the program correctly and does it you do you the unit tests check out? Yes or no. But some of the things where they’re struggling is like for example, I think they have a tough time with like nuance of maybe what I what I had in mind or what I intended and when to ask clarifying questions.
简体中文
如果推测底层原因,关键仍可能是 reinforcement learning。实验室可以显著改善那些具有可验证 reward 的能力:程序是否正确,unit tests 是否通过,这些都能给出明确答案。但模型在更细腻的部分表现较弱,例如理解我真正想要的是什么、把握隐含意图,以及判断何时应提出 clarifying question。
00:26:03
Open at 00:26:03 从此处播放
English
Um or like what I Yeah, it’s just um anything that feels softer is like worse. And so you’re kind of like you’re either on rails and you’re part of the super intelligence circuits or you’re not on rails and you’re outside of the verifiable domains and suddenly everything kind of just like meanders. Like maybe another way to put it is if you go to if today if you go to like state-of-the-art model, ChatGPT and you ask it tell me a joke, um do you know what joke you’re going to get? There’s the joke. The joke? I do feel I I I can’t tell you like the you know, standard form of it, but I do feel like ChatGPT has like three jokes.
简体中文
任何更‘软’的任务通常都更差。要么你处在清晰轨道上,落入所谓 superintelligence circuits;要么你离开可验证领域,系统立刻开始游移。另一个表达方式是:今天你向最先进的 ChatGPT 说‘讲个笑话’,几乎可以预判它会给出什么。ChatGPT 似乎总共只有大约三个笑话。
00:26:34
Open at 00:26:34 从此处播放
English
>> Yeah, yeah. So the the joke that apparently all the LLMs like love the most is why do scientists not trust atoms? Okay. Because they make everything up. Okay. >> They make everything up. So this is still >> emerge? So this is the joke you would get like three or four years ago and this is the joke you still get today. Okay. >> So even though the models have improved tremendously and if you give them an agentic task, they will just go for hours and move mountains for you. And then you ask for like a joke and it has a stupid joke. It’s crappy joke from five years ago and it’s because it’s outside of the it’s outside of the RL.
简体中文
其中最受 LLM 喜爱的一个是:‘为什么科学家不信任原子?因为它们会 make everything up。’这在英语中同时表示‘构成一切’与‘编造一切’。三四年前模型就在讲这个笑话,今天仍然如此。模型可以在 agentic task 上连续工作数小时、完成极复杂任务;但让它讲笑话时,却仍返回五年前那个质量平庸的固定答案,因为幽默不在主要 RL 优化范围内。
00:27:09
Open at 00:27:09 从此处播放
English
It’s outside of the reinforcement learning. It’s outside of what’s being improved. It’s like and it’s part of the jaggedness of like shouldn’t you expect models as they get better to also have like better jokes or more diversity of them or it’s just it’s not being optimized and stuck. Do you think that that implies that we are not seeing like generalization in the sense of like broader intelligence of joke smartness being attached to code smartness? Yeah, I think there’s some decoupling where some things are verifiable and some things are not and some things are optimized for arbitrarily by the labs depending on like what data went in and some things are not and um and >> But I mean the the premise there’s a you know, premise from some research groups that if you’re smarter at code generation or in these verifiable fields, you should be better at everything. And like the the joke situation suggests that that’s
简体中文
它处于 reinforcement learning 和持续改进之外。这正体现锯齿性:按直觉,模型变强时笑话质量与多样性也应改善;但如果该维度没有被优化,就会停滞。这是否意味着,我们没有看到一种广义 generalization,即代码能力提升并不会自然带来幽默理解提升?——确实存在明显解耦。有些能力可验证,有些不可验证;实验室根据数据和目标选择性优化一些领域,而忽略另一些领域。
00:28:00
Open at 00:28:00 从此处播放
English
not happening at all. Okay. >> Yeah, I don’t think that’s happening. I think I think maybe we’re seeing like a little bit of that, but not like a satisfying amount. >> Yeah, that jaggedness exists in humans. You [laughter] can be very very good at math and still tell really bad jokes. >> Yeah, that’s true. Yeah, but it just it still means that we’re not getting like the story is that we’re getting a lot of the intelligence and capabilities in all the domains of society like for free as we get better and better models and that’s not like exactly fundamentally
简体中文
某些研究路线主张,只要模型在代码生成或其他可验证领域变得更聪明,就应当在所有方面同步提升;笑话案例显示,这种转移至少没有充分发生。我认为可能存在少量 generalization,但远未达到令人满意的程度。人类当然也有 jaggedness,一个数学家完全可能很不会讲笑话;但这仍说明,‘模型越强,社会所有领域的智能与能力都会免费获得’这一叙事并不完全成立。
Chapter 7: Model speciation
Chapter start 章节起点: 00:28:25
00:28:26
Open at 00:28:26 从此处播放
English
what’s going on and there’s some blind spots and some things are not being optimized for and this is all clustered up in these neural net opaque models, right? So you’re either on rails of what it was trained for and everything is like you’re going at speed of light or you’re not. And so it’s the jaggedness. So um So that’s why I think like even though the the progression is obvious what should happen, you can’t let it fully go there yet because it doesn’t fully work or it’s a scale issue and we just haven’t like figured out how to use it. So you know, it’s hard to tell. Can I ask a somewhat blasphemous question which is like if this jaggedness is persisting and it’s all rolled up in a at least monolithic interface, right?
简体中文
实际情况是:模型仍存在盲点,很多维度没有被优化,而所有能力都被压缩进不透明的神经网络中。如果任务处在训练过的轨道上,系统会像以光速前进;一旦离开轨道,表现就会急剧下降,这就是 jaggedness。因此,尽管下一步的发展方向似乎显而易见,我们还不能完全放手让系统自治:它仍未充分可靠。当然,也可能只是规模或使用技能不足,我们尚未掌握正确方法。——我想问一个略显‘亵渎’的问题:如果这种锯齿性持续存在,而对外接口仍由一个单一、整体化模型承载……
00:29:06
Open at 00:29:06 从此处播放
English
But you know, single model. Does that make sense or do you should should it be unbundled into things that are can be optimized and improved against different domains of intelligence? Like unbundling the models into multiple experts in different areas, etc. More directly. Yeah. Um Instead of just MOE that we have no exposure to because that can be like confusing as a user from the outside which is like why is it so good at this, but not at this other thing? Yeah, I think currently my impression is the labs are trying to have a single sort of like monoculture of a model that is arbitrarily intelligent in all these different domains and they just stuff it into the parameters. I do think that we will we I do think we should expect more speciation in the intelligences.
简体中文
那么,这种单模型结构是否合理?是否应该把它拆分为多个可分别针对不同智能领域优化的 expert,而不是只依赖用户无法观察的 MoE?从外部看,一个模型在某件事上极其强大、在另一件事上却明显薄弱,会让用户非常困惑。——我的印象是,当前各实验室仍在追求一种模型 monoculture:把各领域能力全部塞进同一组参数,希望它在所有方向上都达到任意高智能。但我认为未来应该期待更多 intelligence speciation。
00:29:48
Open at 00:29:48 从此处播放
English
Um like, you know, the animal kingdom is extremely diverse in the brains that exist and there’s lots of different niches of of nature and some animals have overdeveloped visual cortex or other part kind of parts and I think we we should be able to see more speciation and um you don’t need like this oracle that knows everything. You can speciate it and then you put it on a specific task and we should be seeing some of that because you should be able to have like much smaller models that still have the cognitive core like they’re still competent but then they specialize and then um and then they they can become more efficient in terms of latency or throughput on specific tasks that you really care about. Like if you’re a mathematician working in Lean, I saw for example there’s a few releases that really like target that as a domain. Um uh so there’s a probably going to be a few examples like that where the
简体中文
动物界的神经系统极其多样,生态位也非常丰富;不同动物会过度发展视觉皮层或其他脑区。AI 也应出现类似分化。我们未必需要一个无所不知的 oracle,可以让模型分化后专注具体任务。较小模型仍可保留通用 cognitive core,具备基本胜任能力,同时在特定领域深度专业化,从而在 latency 和 throughput 上更高效。例如,专门为 Lean 定理证明工作的数学模型已经出现了一些有针对性的发布。未来应当还有更多适合 unbundling 的领域。
00:30:31
Open at 00:30:31 从此处播放
English
unbundling kind of makes sense. One question I have is whether or not the capacity constraint on available compute infrastructure Mhm. drives more of this because efficiency Yeah. actually matters more. Yeah. Your if you financing aside, though financing’s involved in all of this. If you have access to full compute for anything you do like even one single model, right?
简体中文
一个问题是,可用计算基础设施的容量限制是否会推动这种分化,因为当 compute 稀缺时,效率就更重要。假如暂时不考虑融资因素,并且任何任务都能无限使用完整算力,那么单一巨型模型也许仍可成立。
00:30:56
Open at 00:30:56 从此处播放
English
But if you actually feel pressure where you’re like I can’t serve >> Mhm. um model of massive size for every use case. >> Mhm. Like do you think that leads to any speciation? Does that question make sense to you? The question makes sense and I guess like what I’m what I’m what I what I’m struggling with is I don’t think we’ve seen too much speciation just yet, right? No. Uh we’re seeing a monoculture of models. Yeah. So um And there’s like clearly pressure for like make a good code model, put it back in the main, merge again. Yeah.
简体中文
但现实中,你无法为每个 use case 都部署超大型语言模型。这样的资源压力是否会导致 speciation?——问题合理,只是我们目前还没有看到太多真正分化,行业仍以模型 monoculture 为主。确实存在一种趋势:先做一个优秀代码模型,再把能力合并回主模型。
00:31:23
Open at 00:31:23 从此处播放
English
>> Um even though there already is pressure on the models. Mhm. I guess perhaps I I feel like there’s a lot of very short-term supply crunch and like maybe that causes more speciation now. Yeah, I think fundamentally like the the the labs are serving a model and they don’t really know what the end user is going to be asking about. So maybe that’s like some part of it because they kind of have to multitask over all the possible things they could be asked. But I think if you’re coming to a business and maybe partnering on some specific problems you care about then maybe you would see that there. Um or there would be some very high-value applications that are like more niche. Um But but I think right now they’re kind of like going after the totality of what’s available. I don’t think that the science of manipulating the brains is like fully developed yet partly. What do you mean manipulating? So like so
简体中文
即使服务成本已经形成压力,这种合并模式仍占主导。短期供给紧张也许会促进更多专用模型。根本原因可能是,实验室面向未知终端用户提供模型,不知道用户会提出什么问题,所以必须对所有可能任务做 multitask。但当实验室与企业围绕具体高价值问题合作时,专业化更有可能出现。当前实验室仍在争取覆盖全部能力空间。另一个限制是,我们还没有成熟掌握如何操纵这些‘大脑’。
00:32:10
Open at 00:32:10 从此处播放
English
fine-tuning without losing capabilities as an example. And I we don’t have these primitives for actually like working with the intelligences in ways other than just context windows. Our context windows kind of just just work and it’s very cheap to manipulate etc. And this is how we’re getting some of the customization etc. Uh but I think if it was I think it’s a it’s a bit more of a developing science of how you like more deeply adjust the models, how you have continual learning maybe or how you
简体中文
例如,如何在 fine-tuning 时不损失原有能力。除 context window 外,我们缺少足够可靠的 primitive 来深度调整模型。上下文操作便宜、有效,因此目前多数定制依靠 context;但持续学习、局部能力增强以及直接修改 weights 的科学仍处于发展阶段。
Chapter 8: Building collaboration surfaces for humans and AI
Chapter start 章节起点: 00:32:30
00:32:32
Open at 00:32:32 从此处播放
English
um how you fine-tune in a certain area, how you get better in a certain area or like how you actually touch the weights not just the context windows. And so it’s a lot more tricky I would say to touch the weights than just the context windows uh because you’re actually fundamentally changing the full model and potentially its intelligence. And so um so maybe it’s just like not a fully developed science if that makes sense of speciation. And it also has to be like cheap enough Yeah. for that speciation to be worthwhile in these given >> contexts. Can I ask a question about like an extension to auto research that you described in terms of open ground?
简体中文
真正触碰 weights、使模型在某一领域长期变强,比修改 context window 困难得多,因为你是在改变整个模型及其潜在智能结构。因此,speciation 的方法学尚不成熟;而且专业化成本还必须足够低,才能在具体场景中产生经济价值。——你曾谈到把 AutoResearch 扩展到开放协作空间,可以进一步说明吗?
00:33:05
Open at 00:33:05 从此处播放
English
You say okay, well, you know, we have this thing. Um we need more collaboration surface around it essentially for people to contribute to research overall. Can you talk about that? >> Yeah, so we talked about auto research has a single thread of like I’m going to try stuff in a loop but fundamentally the parallelization of this is like the interesting component.
简体中文
既然已有一个自动研究系统,就需要更多 collaboration surface,让更多人参与总体研究。——目前 AutoResearch 是单线程 loop:不断尝试、评估、再尝试。真正有趣的部分是如何实现并行化。
00:33:24
Open at 00:33:24 从此处播放
English
And I guess I was trying to like play around with a few ideas but I don’t have anything that like clicks as simply as like I don’t have something I’m like super happy with just yet but it’s something I’m like working on the side when I’m not working on my claw. Um so I think like one issue is if you have a bunch of nodes of parallelization available to then it’s very easy to just have multiple auto researchers talking through a a common system or something like that.
简体中文
我尝试过几个方案,但还没有找到像单循环 AutoResearch 那样简洁、令我完全满意的设计。空闲时我仍在研究。若拥有许多可信并行节点,最简单的方法是运行多个 AutoResearcher,让它们通过一个共享系统交流。
00:33:47
Open at 00:33:47 从此处播放
English
What I was more interested in is how you can have an untrusted pool of workers out there on the internet. Mhm. So for example in auto research you’re just trying to find um the piece of code that trains a model to a very low validation loss. If anyone gives you a candidate commit, it’s very easy to verify that that commit is correct is good. Like they someone could claim from the internet that this piece of code will optimize much better and give you much better performance. You could just check. Yeah.
简体中文
我更感兴趣的是:如何利用互联网上一个 untrusted worker pool。以 AutoResearch 为例,目标是找到能把模型训练到更低 validation loss 的代码。任何人都可以从互联网提交 candidate commit;验证该提交是否真的更好相对容易。对方可以声称某段代码能显著改善优化和性能,而你只需复现实验即可检查。
00:34:13
Open at 00:34:13 从此处播放
English
But probably a lot of work goes into that checking. But fundamentally they could lie and etc. So you’re basically dealing with a similar kind of it’s almost actually like looks a little bit like my my designs that incorporate an untrusted pool of workers actually look a little bit more like a blockchain a little bit uh because instead of blocks you have commits and these commits can build on each other and they contain like changes to the code as you’re improving it. Um and uh the proof of work is basically doing tons of experimentation to find the commits that work.
简体中文
提交者当然可能撒谎,验证也会消耗一定资源。因此,这种包含不可信 worker 的设计在某些方面有点像 blockchain:区别是系统中的基本单元不是 block,而是 commit;commit 可以相互继承,记录模型代码的连续改进。对应的 proof of work,是执行大量实验并找到真正有效的 commit。
00:34:41
Open at 00:34:41 从此处播放
English
Um and that’s hard and then the reward is just being on the leaderboard right now. There’s no monetary reward whatsoever. Uh but I don’t want to push the analogy too far but it fundamentally has this issue where you a huge amount of search goes into it but it’s very cheap to verify that a candidate solution is indeed good because you can just train a single you know, someone had to try 10,000 ideas but you just have to check that the thing that they produced actually works because the 99,000 of them didn’t work, you know? Um and so basically long story short is like you have to come up with a system where an untrusted pool of workers can collaborate with a trusted pool of workers that do the verification.
简体中文
搜索过程很困难,当前奖励可能只是进入 leaderboard,而没有货币激励。这个类比不应推得过远,但核心结构相似:发现候选方案需要极其庞大的搜索成本,而验证一个候选方案是否有效却很便宜。提交者可能尝试了一万种想法,绝大多数失败;验证者只需重新训练最终提交,确认它确实工作。因此,需要设计一个系统,使不可信 worker pool 与负责验证的 trusted worker pool 协作。
00:35:18
Open at 00:35:18 从此处播放
English
And the whole thing is kind of like asynchronous and works and and so on and it’s it’s like safe from a security perspective because if anyone sends you arbitrary code and you’re going to run it, that is very sketchy and dodgy. So um but fundamentally it should be totally possible. So you’re familiar with projects like SETI@home and Folding@home. All of these problems have a similar kind of setup. So Folding@home you’re folding a protein and it’s very hard to find a configuration that is low energy. But if someone finds a configuration that they value to be low energy, that’s perfect.
简体中文
整个流程应异步、安全地运行。直接执行陌生人提交的 arbitrary code 显然存在严重安全风险,但原则上可以通过隔离与验证机制解决。SETI@home 和 Folding@home 就具有类似结构。以蛋白质折叠为例,找到低能量构象非常困难;但如果有人提交了一个声称低能量的构象,其能量值却容易验证。
00:35:45
Open at 00:35:45 从此处播放
English
You can just use it. You can easily verify it. So a lot of things have this property that you know, very expensive to come up with but very cheap to verify. And so in all those cases things like Folding@home or SETI@home or auto research at home will be good fits. And so um long story short a swarm of agents on the internet could collaborate to improve LLMs and could potentially even like run circles around frontier labs. Like who knows, you know?
简体中文
很多问题都具有‘产生答案昂贵、验证答案便宜’的性质,因此 Folding@home、SETI@home 或 ‘AutoResearch@home’ 很适合。由此可以设想,互联网上的 agent swarm 协作改进 LLM,甚至可能超过 frontier lab 的研究速度。
00:36:10
Open at 00:36:10 从此处播放
English
Um yeah, like maybe that’s even possible. Like frontier labs have a huge amount of trusted compute but the earth is much bigger and has huge amount of untrusted compute. But if you put systems in check systems in place that you know, deal with this then maybe it is possible that the swarm out there could could come up with with better with better solutions.
简体中文
前沿实验室拥有巨量 trusted compute,但地球范围内存在更庞大的 untrusted compute。如果建立充分的 check system 和安全机制,全球智能体群体确实可能找到更优解。
00:36:30
Open at 00:36:30 从此处播放
English
And people kind of like contribute cycles um to to a thing that they care about. And so sorry to so the last thought is uh lots of companies or whatnot they could maybe have like their own things that they care about and you if you have compute capacity you could contribute to different kind of auto research tracks. Like maybe you care about certain you know, like you care about like cancer or something like that of certain type. You don’t have to just donate money to an institution. You actually could like purchase compute and then you could join the auto research swarm for that project, you know? Uh so if everything is rebundled into auto researchers then compute becomes the thing that you’re contributing to the pool. Yeah. That’s very inspiring and it’s also interesting. Like I don’t I don’t know how far this goes but it is interesting that at least some audience of people you know, here in Silicon Valley or
简体中文
人们可以把自己的计算周期贡献给关心的问题。公司或个人可加入不同 AutoResearch track:例如关心某类癌症研究时,不一定只向机构捐款,也可以直接购买算力并加入该项目的自动研究 swarm。当大量问题被重构为 AutoResearch,compute 就成为人们投入公共池的主要资源。这个愿景很有启发性。至少在硅谷,以及中国零售门店排队购买设备的人群中,personal compute 又重新变得有吸引力。
00:37:13
Open at 00:37:13 从此处播放
English
lining up at you know, retail stores in China have discovered that like having access to personal compute is interesting again. >> Yeah. Right? So maybe they’re really motivated to do that for their claws and then they can contribute to auto research. >> almost like dollars the thing everyone cares about but is flop the thing that
简体中文
人们可能先为自己的 claws 购买算力,随后把闲置计算贡献给 AutoResearch。也许未来真正关键的不是美元,而是 FLOPs。
Chapter 9: Analysis of jobs-market data
Chapter start 章节起点: 00:37:28
00:37:30
Open at 00:37:30 从此处播放
English
actually everyone cares about in the future? Like is there going to be like a flipening almost of like what’s the thing that you care about? Like right now for example it’s really hard to get compute even if you have money. Yeah. So actually it almost seems like the flop is like dominant >> [laughter] >> in a certain sense. Um Yeah, so so maybe that’s kind of like that. Kind of like that. Like how much how many flops do you control instead of like what wealth you control? I don’t actually think that’s true but it’s kind of interesting to think about. The last thing you released was like a little bit of jobs data analysis. Is that right?
简体中文
未来人们最关心的资源是否会发生一次 ‘flippening’?今天即使有钱,也很难立即获得充足 compute;从某种意义上看,FLOPs 似乎比货币更稀缺。也许未来衡量能力的是你控制多少 FLOPs,而不只是拥有多少财富。当然,我不认为这会完全取代货币,但值得思考。——你最近还发布了一份就业数据分析,对吗?
00:37:59
Open at 00:37:59 从此处播放
English
What and might have touched a nerve even though you’re just like visualizing some public data. >> Yeah. Uh what was you know, what were you curious about? Yeah, I guess I was curious to um I mean everyone is like really it’s everyone is really thinking about the impacts of AI on the job market and what’s going to look like. So I was just interested to take a look like what does the job market look like? Where are the different roles um and how many people are in different professions? And I was like really just interested to like look through the individual cases and try to think myself about like you know, with these AIs and how they’re likely to evolve like are these going to be tools that people are using? Are these going to be displacing tools for these professions?
简体中文
你只是把公开数据做了可视化,却似乎触动了很多人的神经。你当时真正想了解什么?——所有人都在思考 AI 对 job market 的影响,因此我想先看清就业市场本身:有哪些职业、每类职业有多少人。然后逐一考察,结合 AI 可能的演进,判断它更可能成为从业者使用的工具,还是直接替代部分职业任务。
00:38:36
Open at 00:38:36 从此处播放
English
And like what are the current professions and how are they going to change? Are they going to grow or uh adjust to a large extent or like what could be new professions? So it’s really just like a way to fuel my own chain of thought about the industry I suppose. Mhm. Um and so yeah, the jobs data basically is just a Bureau of Labor Statistics. They actually have um percent outlook for each profession about how much it’s expected to grow over the next I think almost a decade. Uh yeah, I think it’s a decade but it was made in 2024. Mhm. We need a lot of health care workers. Yeah.
简体中文
我也想思考现有职业会怎样变化:增长、收缩、重组,还是出现全新职业。这个分析主要是为了推动我自己的 chain of thought。数据来自美国 Bureau of Labor Statistics,其中包含各职业未来约十年的预期增长率,预测基准大约在 2024 年。结果很明显:医疗保健领域需要大量新增劳动力。
00:39:05
Open at 00:39:05 从此处播放
English
So so they’ve already made those projections and I’m not sure actually 100% what the methodology was that they they put into their projections. Um I guess I was interested to color things by like if people think that what’s like primarily being developed now is this kind of like more digital AI that is kind of like almost like these ghosts or spirit entities that can like interact in the digital world and manipulate a lot of like digital information and they currently don’t really have a physical embodiment or presence. And the physical stuff is probably going to go slightly slower because you’re manipulating atoms. So flipping flipping bits and and the ability to copy-paste digital information is like makes everything a million times faster than accelerating matter, you know, so Um so energetically, I just think we’re going to see a huge amount of activity in the digital space, huge amount of
简体中文
BLS 已经作出这些预测,但我并不完全了解其方法。我更感兴趣的是按工作是否主要处理 digital information 来着色。当前发展的 AI 更像数字世界中的 ghost 或 spirit entity:它们能在数字环境中交互和操纵信息,却没有真正 physical embodiment。物理领域可能发展更慢,因为它必须操作 atoms。翻转 bits、复制粘贴数字信息,比加速和移动物质快几个数量级。因此,从能量和系统摩擦上看,数字空间将出现巨量活动。
00:39:48
Open at 00:39:48 从此处播放
English
rewriting, huge amount of activity, boiling soup. And I think the we’re going to see something that in the digital space goes at the speed of light compared to I think what’s going to happen in the physical world to some extent. If it would be the extrapolation. And so I think like >> [clears throat] >> there’s currently kind of like I think overhang where there can be like a lot of unhubbling almost potentially of like a lot of digital information processing that used to be done by computers and people. And now with AIs there’s like a third kind of manipulator of digital information. There’s going to be a lot of refactoring in those in those disciplines.
简体中文
数字领域会经历大规模重写和持续沸腾,其速度可能远高于物理世界。过去数字信息主要由传统计算机和人类共同处理;现在 AI 成为第三类数字信息操作者,形成巨大的 capability overhang。许多行业的工作流因此会被重新拆解和 refactor。
00:40:19
Open at 00:40:19 从此处播放
English
Um but the physical world is actually going to be like I think behind that by some amount of time. And so I think what’s really fascinating to me is like So that’s why I was highlighting the the professions that fundamentally manipulate digital information. This is work you could do from your home, etc. Uh because I feel like those will be like things will change. And it doesn’t mean that there’s going to be less of those jobs or more of those jobs because it does has to do with like demand elasticity and many other factors. But things will change in these professions because of these new tools and um because of this upgrade to the nervous system of the human superorganism >> [laughter]
简体中文
物理世界会在相当一段时间内落后。这也是我特别标记那些主要处理数字信息、通常可远程完成的职业的原因。这些职业一定会变化,但不意味着岗位数量必然减少或增加,因为结果还取决于 demand elasticity 等多种因素。可以把 AI 看作人类 superorganism 的 nervous system 升级;这种升级会改变所有数字信息职业。
00:40:51
Open at 00:40:51 从此处播放
English
>> if you want to think about it that way. Given the look you had at the data, do you have either any observations or um uh guidance for people facing the job market or thinking about what to study now or what skills to develop? I mean we can all go get like I’m very thankful that I have to like meet people for my job right now. >> Yeah. >> [laughter]
简体中文
基于这些数据,你对正在进入就业市场、选择专业或培养技能的人有什么观察和建议?我很庆幸自己的工作需要与人见面。
00:41:08
Open at 00:41:08 从此处播放
English
>> Yeah, more physical. Yeah. Could you do your work from home though? I could. I think there are relationship parts of it that are hard, but most of it I could. Yeah. I think it’s really hard to tell because again like the job market is extremely diverse. I think the answers will probably vary, but uh to a large extent like these tools are extremely new, extremely powerful. And so just being you know, just trying to keep up with it is like the first thing.
简体中文
这种工作更具物理性,不过大部分内容理论上仍可远程完成,关系建立的部分较难替代。总体上,job market 极其多样,不同职业答案会不同。但这些工具非常新、能力非常强,第一要务就是尽力跟上变化。
00:41:29
Open at 00:41:29 从此处播放
English
Um and um yeah, because I think a lot of people kind of like dismiss it or Or they’re afraid of it. Or they’re afraid of it, etc. As which is totally understandable, of course. Yeah, I think like um it’s fundamentally an empowering tool at the moment. Um and these jobs are bundles of tasks. And some of these tasks can go a lot faster. And so people should think of it as primarily a tool that it is right now.
简体中文
很多人会忽视它,或者因为恐惧而回避,这完全可以理解。但至少在当前阶段,它首先是一种赋权工具。职业是多个 task 的组合,其中一些任务可以被显著加速,因此现阶段应优先把 AI 理解为提高个人能力的工具。
00:41:49
Open at 00:41:49 从此处播放
English
Um and I think the long-term future of that is uncertain. Yeah, it’s kind of really hard to forecast, to be honest. And like I’m not professionally like doing that really. And I think this is a job of like economists to do properly. You are an engineer though. And like one thing I thought was interesting is that like the demand for engineering jobs is continuing to increase.
简体中文
长期结果非常不确定,也很难可靠预测。这更应由专业 economist 严谨研究。——但你是工程师。有一个有意思的现象是,工程岗位需求仍在增长。
00:42:08
Open at 00:42:08 从此处播放
English
>> Yeah. Um I I can’t tell if that’s like a temporary phenomenon. I’m not sure how I feel about it. Yeah, do you know? Yeah, that’s like the demand elasticity almost like uh software was scarce, right? And so the reason we don’t have more demand for software is just there’s its scarcity and it’s too expensive. >> So if the barrier comes down, then actually you have the Jevons paradox, which is like you know, you actually the demand for software actually goes up.
简体中文
我无法判断这是否只是短期现象。它可能与 demand elasticity 有关。过去软件是稀缺品,需求没有更高,很大程度上是因为软件太昂贵、供给不足。如果开发门槛下降,就可能出现 Jevons paradox:单位软件成本降低,反而使总需求上升。
00:42:28
Open at 00:42:28 从此处播放
English
It’s cheaper and there’s more More powerful, yeah. The the classical example of this always is the ATMs and the bank tellers uh because there was a lot of like fear that um ATMs and computers basically uh would displace tellers. But what happened is they made like the cost of operation of of a bank branch much cheaper. And so there are more bank branches, so there are more tellers. It’s like the canonical example people cite. Uh but basically it’s just Jevons paradox. Like something becomes cheaper, so there’s a lot of unlocked demand for it. Uh so I do think that that’s probably I do have like cautiously optimistic view of this in software engineering where I do think um it does seem to me like the demand for software will be extremely large. Um and it’s just become a lot cheaper. And um so I do think that for quite some time um it’s very hard to forecast, but it does seem to me like right now at least
简体中文
经典例子是 ATM 与银行柜员。人们曾担心 ATM 和计算机会替代柜员;实际结果是,自动化降低了银行网点运营成本,网点数量增加,柜员总量在一段时期内也随之增加。其核心就是 Jevons paradox:某种资源变得便宜后,大量潜在需求被释放。我对软件工程持谨慎乐观态度,因为软件需求可能极其庞大,而生产成本正在快速下降。至少在可预见的近中期,本地效应很可能是软件需求增加。
00:43:18
Open at 00:43:18 从此处播放
English
locally there’s going to be more demand for software. Um because software is amazing. It’s like you know, digital information processing. You’re not forced to use like arbitrary tools that were given to you. They’re imperfect in various ways. You’re not forced to subscribe to what exists. Code is now ephemeral and it can change and it can be modified.
简体中文
软件本质上是数字信息处理。人们不再必须接受现有工具的任意限制,也不必永远订阅一套不完全符合需求的产品。代码正变成 ephemeral、可即时修改和重构的资源。
00:43:34
Open at 00:43:34 从此处播放
English
Um and so I think there’s going to be a lot of activity in the digital space to like rewire everything in a certain sense. And I think it’s going to create a lot of demand for for this kind of stuff. I think long-term um yeah, obviously even with auto research like OpenAI or or you know, Anthropic or these other labs like they’re employing what like a thousand something researchers, right?
简体中文
因此,数字空间会出现大量重新布线式活动,并产生新的工程需求。但长期看,即使是 AutoResearch,也暴露出另一层问题:OpenAI、Anthropic 等实验室拥有上千名研究人员。
00:43:53
Open at 00:43:53 从此处播放
English
>> Mhm. These researchers are basically like glorified auto like you know. >> [laughter] >> They’re like automating themselves away like actively and this is like the thing they’re all trying to do. Yeah. I like I went around um Some of those researchers also fear that feel the psychosis, right? Because they can it’s working, right? And and so they’re like it’s over for me, too. I did spend a bunch of time going around OpenAI and I was like, you guys realize if we’re successful like we’re all out of job like like this is just going to we’re just building automation for Sam or something like that. Like I or the board or I’m not sure, but like uh they’re just building all this automation for yeah, the board or the CEO or something like that. And we’re all out of our job and maybe contributing on the side. And so yeah, it’s kind of like unnerving from that perspective. Is it okay if I ask you Noam’s question? Mhm. You know, you
简体中文
这些研究人员某种意义上正在积极自动化自己的岗位,这正是他们共同努力的方向。有些研究人员也感受到同样的 psychosis,因为系统确实开始工作,于是会想:‘我的岗位也要结束了。’我曾在 OpenAI 四处说:如果我们真的成功,所有人都会失业;我们只是为 Sam、董事会或 CEO 构建自动化系统,自己最后可能只在旁边贡献少量想法。从这个角度看,确实令人不安。——可以问你 Noam 的问题吗?
00:44:38
Open at 00:44:38 从此处播放
English
could be doing that, right? Auto researching with a lot of compute scale and a bunch of colleagues at one of the frontier [clears throat] labs. Like why not? Well, I was there for a while, right? Like and I did reenter. So to some extent I agree and I think that there are many ways to slice this question. It’s very loaded question a little bit. Um I will say that I feel very good about like what people can contribute and their impact outside of the frontier labs, obviously. Not in the industry, but also in like more like ecosystem level roles. Um so your role for example is more like ecosystem level. My role currently is also kind of more on ecosystem level. And I feel very good about like impact that people can have in those kinds of roles. I think conversely there’s there are definite problems in my mind for um uh for basically aligning yourself way too much with the frontier labs, too. So
简体中文
你完全可以在某个 frontier lab 中,调度大量 compute 并与众多同事共同开展 AutoResearch,为什么不这样做?——我曾长期在实验室,也曾重新加入过,因此某种程度上同意这个问题。不过它包含许多层面。首先,我相信人在 frontier lab 之外也能产生巨大影响,不仅可以在产业公司,也可以承担 ecosystem-level role。你现在的工作更接近生态系统角色,我目前也类似;这类角色可以产生非常高的杠杆。另一方面,与 frontier lab 绑定过深也存在明确问题。
00:45:20
Open at 00:45:20 从此处播放
English
fundamentally I mean you’re you have a huge amount of financial incentive to uh with these frontier labs. And by your own admission, the uh the AIs are going to like really change humanity and society in very dramatic ways. And here you are basically like building the technology and benefiting from it like it and being like very allied to it through financial means. Like this was the conundrum that was in at the heart of you know, how OpenAI was started in the beginning. Like this was the conundrum that we were trying to solve.
简体中文
你会受到巨大的财务激励,而你自己又承认 AI 将以非常剧烈的方式改变人类和社会。此时,你一边构建技术、一边从技术价值上升中获益,并通过经济利益与实验室高度结盟。这正是 OpenAI 最初创立时试图解决的核心困境之一。
00:45:45
Open at 00:45:45 从此处播放
English
Mhm. Um and so you know, that so it’s kind of um It’s still not resolved. >> is still not like fully resolved. So that’s number one. You’re you’re not a completely free agent and you can’t actually like be part of that conversation in a fully autonomous um free way. Like if you’re inside one of the frontier labs. Like there’s some things that you can’t say. Uh and conversely there are some things that the organization wants you to say. And you know, they’re not going to twist your arm, but you feel the pressure of like what you should be saying, you know, cuz like obviously >> [laughter]
简体中文
这个困境至今没有真正解决。进入 frontier lab 后,你不再是完全自由的 agent,无法以完全自主的方式参与公共讨论。有些话不能说,组织也会希望你表达某些立场。它不一定强迫你,但你会感受到应当怎样发言的压力。
00:46:15
Open at 00:46:15 从此处播放
English
>> otherwise it’s like really awkward conversations, uh strange side eyes, like what are you doing, you know, like so you can’t like really be an independent agent. And I I feel like a bit more a lot like aligned with humanity in a certain sense outside of the frontier lab because I don’t I’m not subject to those pressures almost, right? And I can say whatever I want or Yeah, I would say in the frontier labs like um you can have like impact there of course as well. So but there’s many researchers and maybe you’re one of them, maybe your ideas are really good, etc. Maybe there’s a lot of decision-making to do and you want to be in a position where you are in the room with those conversations when they come up. I do think that currently the stakes are like overall fairly low and so everything is kind of like nice. But ultimately in the end of the day like when the stakes are really high, etc. If
简体中文
否则就会出现尴尬谈话和异样目光,使人难以保持真正独立。离开 frontier lab 后,我感觉自己在某种意义上更直接地与 humanity 对齐,因为不再承受这些组织压力,可以自由表达。当然,在实验室内部也能产生重要影响;如果你的研究想法很好,并且希望参与关键决策,就需要进入讨论现场。目前总体 stakes 仍相对低,所以许多矛盾尚不尖锐;但当 stakes 真正升高时,普通员工究竟能多大程度影响组织方向,并不明确。
00:46:54
Open at 00:46:54 从此处播放
English
you’re an employee at an organization, I don’t actually know how much sway you’re going to have on your organization what it’s going to do. Like fundamentally at the end of the day um uh it’s uh you’re not like really in charge. Like you’re in the room and you’re contributing ideas, but you’re not like really in charge of that entity that you’re that you’re part of. So those are like some sources of misalignment, I think to some extent. I will say that like in one way I do agree a lot with that sentiment that um I do feel like in the like the labs for better or worse they’re opaque and a lot of work is there. And they’re kind of like at the edge of capability and what’s possible.
简体中文
你可以在会议室里提出观点,却并不真正掌控所在实体。这是潜在 misalignment 的来源。不过,我也非常认同相反的一面:frontier lab 无论好坏都高度不透明,真正前沿的工作集中在那里,它们最接近能力边界。
00:47:23
Open at 00:47:23 从此处播放
English
And they’re working on what’s coming down the line. And I think if you’re outside of that frontier lab, your your judgment fundamentally will start to drift because you’re not part of the you know, what’s coming down the line. And so I feel like my judgment will inevitably start to drift as well. And I won’t actually have an understanding of how these systems actually work under the hood. That’s an opaque system.
简体中文
如果长期处于实验室之外,个人 judgment 会逐渐漂移,因为无法看到下一阶段正在发生什么。我自己的判断也必然会偏离,而且无法真正理解这些系统 under the hood 的工作机制,因为核心系统是不透明的。
00:47:42
Open at 00:47:42 从此处播放
English
I won’t have a a good understanding of how it’s going to develop and etc. And so I do think that in that sense I agree and something I’m nervous about. I think it’s worth basically being in touch with what’s actually happening and actually being in a frontier lab. And if if some of the frontier labs would have me come for you know, some amount of time and do really good work for them and then maybe come and hang out.
简体中文
我也难以准确理解它将怎样继续发展。因此,在这一点上我同意 Noam,也对此感到紧张。与真实前沿保持接触、实际进入 frontier lab 工作,具有重要价值。如果某个实验室愿意让我在一段时间内加入、完成高质量工作,然后再离开继续独立活动……
00:48:01
Open at 00:48:01 从此处播放
English
>> looking for a job. This is super exciting. [laughter] Then I think that’s maybe a good setup because I kind of feel like it’s kind of um you know, maybe that’s like one way Mhm. uh to to actually be connected to what’s actually happening, but also not feel like you’re necessarily fully controlled by Yeah. by those entities. So I think honestly in my mind like Noam can probably get do extremely good work at at OAI, but also I think his most impactful work could very well be
简体中文
那也许是较好的安排:既能连接真实前沿,又不必被某个实体完全控制。Noam 在 OpenAI 很可能能做出极好的研究,但他最有影响力的工作也完全可能发生在……
Chapter 10: Open versus closed-source models
Chapter start 章节起点: 00:48:25
00:48:25
Open at 00:48:25 从此处播放
English
outside of OpenAI. Noam, that’s a call to be an independent researcher with auto [laughter] research. Yeah, there’s many things to do on the outside and it’s it’s a and I think ultimately I think the ideal solution maybe is like yeah, going back and forth or um yeah, and I think fundamentally you can have a really amazing impact in both places. So very complicated I don’t know. Like it’s a very loaded question a little bit, but I mean I joined the frontier lab and I’m outside. And then maybe in the future I’ll want to join again. And I think um uh that’s kind of like how I look at it.
简体中文
……发生在 OpenAI 之外。——Noam,这相当于邀请你成为独立研究者,用 AutoResearch 开展工作。实验室外部同样有许多重要事情可做。理想方案也许是在内部与外部之间往返;两种位置都能产生巨大影响。我自己曾加入 frontier lab,后来离开,将来也可能再次加入。这是一个非常复杂、负载很高的问题,我目前大致以这种方式理解。
00:48:54
Open at 00:48:54 从此处播放
English
One question related to what visibility to does the world or the AI ecosystem have into the frontier is like how how close open source is to the frontier. Mhm. Um and how sustainable that is. I I think Yeah. I think it is quite surprising. The entire sequence of events actually from like having a handful of Chinese models and global models and I think people are going to continue releasing here in the near term that are closer than much of the industry anticipated from a capability [clears throat] perspective.
简体中文
另一个与‘生态系统能看到多少前沿进展’有关的问题是:open source 距离 frontier 到底有多近,这种追赶是否可持续。最近一系列事件相当令人惊讶:从少数中国模型到全球各地的新模型,近期还会继续出现更多发布。从能力上看,它们比行业原先预期更接近前沿。
00:49:26
Open at 00:49:26 从此处播放
English
>> Yeah. Um I don’t know if you’re surprised by that, but you’re a long-term contributor to open source. Like what’s your prediction here? Yeah, so roughly speaking basically the the closed models are ahead, but like people are monitoring the number of months that sort of like open-source models are behind. Um And started with there’s nothing and then it went to 18 months. Now it’s >> Yeah, but then convergence, right? So then maybe they’re behind by like, what is the latest? Maybe like 8 months, 6 months, 8 months kind of thing right now. Yeah, I’m a huge fan of open-source, obviously. So for example, in operating systems, you have like closed source, like, you know, Windows and Mac OS, these are large software projects, kind of like what LLMs are going to become, and there’s Linux. Mhm.
简体中文
你长期参与 open source,对这种收敛有什么预测?——大体上,closed model 仍然领先,但人们一直在统计 open-source model 落后多少个月。最初几乎没有可比较的开源模型,后来差距可能达到十八个月;现在不断收敛,或许只落后六到八个月。我显然非常支持 open source。可以类比操作系统:Windows 和 macOS 是巨大的 closed-source 软件项目,而 Linux 提供了开放平台。
00:49:57
Open at 00:49:57 从此处播放
English
But Linux is very easy. Like, actually Linux is extremely successful project. It runs on the vast majority of computers. Like, last time I checked, was it like 60% or something like from Linux? Um and that’s because there is a need in the industry to have a common open platform that everyone feels uh sort of safe using. I would say like the industry has always felt a demand for that kind of a project to exist. Mhm.
简体中文
Linux 极其成功,运行在绝大多数服务器和大量计算设备上。行业一直需要一个共同、开放、各方能够相对放心使用的平台,因此会持续产生对这类项目的需求。
00:50:17
Open at 00:50:17 从此处播放
English
>> And I think the same is true now. And that’s why businesses actually want there’s demand for this kind of a um a thing to exist. The big difference is that everything is capital uh there’s a lot of capex that goes into this. >> Um so I think that’s where things like fall apart a little bit, make it a bit harder to to compete in certain senses. Uh I I do think that the current models are very good. The other thing that I think is like really interesting is that for the vast majority of like consumer use cases and things like that, even like turn open-source models are actually quite good, I would say. And I think like if you go forward like more uh more years, it does seem to me like a huge amount of like simple use cases are going to be well covered and actually even run locally. Mhm. Um but there’s going to be always like some demand for like frontier intelligence and that that can actually be extremely
简体中文
LLM 领域同样存在这种需求。主要区别是,训练前沿模型需要巨额 capital expenditure,这使开放项目更难在最前沿竞争。不过当前 open model 已经相当优秀;对绝大多数 consumer use case,即使今天的开源模型也足够好。几年后,大量简单任务很可能由本地模型覆盖。但社会始终会保留对 frontier intelligence 的需求,而且这部分价值可能仍占很大份额。
00:50:58
Open at 00:50:58 从此处播放
English
large uh piece of the pie. But it could be that the frontier the need for frontier intelligence is going to be like, you know, Nobel Prize kind of work. Mhm. >> let’s move Linux from C to Rust. It’s going to be like bigger projects, you know, like scoped in that kind of a way, and there’s going to be maybe more um and maybe that’s where a lot of the frontier closed intelligence is where going to are going to be interacting with. And open-source kind of like going to eat through a lot of the more basic use cases or something like that. You know, at some point what is frontier today is going to be, you know, probably later this year what’s frontier today in terms of what I’m using right now from the closed labs uh might be open-source and that’s going to be doing a lot of work. So I kind of expect that this dynamic will actually basically continue. Like we’ll have frontier labs that have closed um AIs that are kind of
简体中文
只是,未来需要 frontier intelligence 的任务可能更接近 Nobel Prize 级研究,或者把 Linux 从 C 大规模迁移到 Rust 这样的超大型项目。闭源前沿智能可能主要服务这些高难度任务,而 open source 会逐步吞噬基础 use case。今天闭源实验室提供的前沿能力,可能到今年晚些时候就会出现在 open-source model 中,并承担大量工作。因此,我预计这种动态会持续:闭源 frontier lab 提供类似 oracle 的最新能力,open source 落后若干个月追赶。
00:51:40
Open at 00:51:40 从此处播放
English
like these oracles, and then we’ll have open-source kind of like behind with some amount of months. And I kind of expect that to uh to continue. And I actually think that’s like a pretty pretty good setup uh overall. Um because I I’m a little bit hesitant of having um I don’t actually think it’s like structurally I think there’s some systemic risk attached to just having intelligence that are closed and that’s like that’s it. Mhm. And I think that that’s a, you know, centralization has a very poor track record in my view uh in in the past and has um >> You mean like in political or economic systems in in general.
简体中文
我认为这种结构总体相当合理。我对‘所有智能都封闭集中于少数实体’存在结构性担忧,因为 centralization 在历史上的记录很差。——你是指政治、经济等一般系统中的集中化。
00:52:11
Open at 00:52:11 从此处播放
English
>> [laughter] >> Exactly. I think there’s like a lot of like pretty >> an Eastern European. A lot of pretty bad precedents, so I want there to be a thing that is maybe not at the edge of capability because it’s new and unexplored, etc. But I want there to be a thing that’s behind and that uh is kind of like a common working space for intelligences that the entire industry has access to. Yeah, that seems to me like a pretty decent power balance for the industry. Yeah. I also think there’s just like there are many problems to solve, right? Like if you keep advancing intelligence from the frontier, we can do new things and there are a lot of like very big problems for humanity, right? And so like it seems that that will continue to be a very expensive game. And so I want to like root for labs that are doing that because there are problems we cannot solve without continuing to advance the models in a
简体中文
是的。作为东欧背景的人,我尤其警惕这种先例。我希望行业始终存在一个共同开放的 intelligence workspace。它不必处在能力最前沿——前沿本来就新且不稳定——但应只落后有限时间,并向整个产业开放。我认为这形成了较健康的 power balance。同时,人类仍有许多巨大问题需要解决,推动 frontier intelligence 的实验室也值得支持,因为若不继续以昂贵方式推进模型,我们可能无法解决那些问题。
00:52:51
Open at 00:52:51 从此处播放
English
very expensive way. And yet, as you point out, like if what we have today as frontier is open, that’s a lot of capability, right? And and so I I I think, you know, the power of that or the democratization of that seems like >> Yeah. very useful and also healthy. >> Yeah. I think basically by accident we’re actually like in an okay spot. >> An optimal. Yeah. [laughter] Yeah. Like by accident we we are it happened to be in a good spot in a certain sense. Mhm.
简体中文
另一方面,如果今天的 frontier 能力不久后就完全开放,那已经是极其强大的公共能力,其 democratization 同样有益且健康。某种程度上,我们似乎偶然落在了一个还不错、甚至接近最优的平衡点。
00:53:15
Open at 00:53:15 从此处播放
English
Um Well, and and to some degree the the longer this endures, like this dynamic, um the the the healthier of a spot like the ecosystem might be in, right? Because you have more and more area under the curve. >> Mhm. And I will say that even on the closed side, I I almost feel like it’s been like even further centralizing recently because I think a lot of the frontrunners are like not necessarily like the top tier. And so uh yeah, like in that sense I think it’s um it’s not super ideal. I would love there to be more more frontier labs because yeah, I’m like by default very suspicious of like um I want there to be more people in the room. I want I think like in machine learning ensembles always outperform any individual model. And so I want there to
简体中文
这种动态持续越久,生态系统积累的‘曲线下面积’越大,整体就越健康。不过在 closed side,近来似乎进一步集中:真正领先的团队数量并不多。我希望出现更多 frontier lab。我的默认立场是对少数人垄断判断权保持怀疑。机器学习中 ensemble 往往优于单个模型;同样,我希望有更多彼此独立、充分知情的人共同思考最困难的问题,并参与关键决策。
Chapter 11: Autonomous robotics
Chapter start 章节起点: 00:53:51
00:53:52
Open at 00:53:52 从此处播放
English
be ensembles of people thinking about all the hardest problems and I want there to be ensembles of people in the room when they um to be all well informed and to make those decisions, you know, so uh I don’t want it to be like a closed doors with two people or three people. I feel like that’s like not a good not a good future. I almost wish like there were more labs as long as they’re short and I I I do think that open-source has a has a has a place to play. I hope it sticks around and I basically I it’s currently slightly behind and it’s actually kind of like a good thing. Okay, you worked on the precursor to generalized robotics autonomy um in cars, right?
简体中文
我不希望未来由两三个人在闭门会议中决定一切。只要安全与治理条件合适,我宁愿看到更多实验室。同时 open source 必须继续存在。目前它略落后于前沿,反而可能是一个相对健康的位置。——你曾参与汽车领域的自动驾驶,它可以视为通用机器人自治的前身。
00:54:24
Open at 00:54:24 从此处播放
English
Uh a a lot has happened in the last couple months with robotics companies as well, like acceleration of really impressive generalization of environment, of tasks, like increasingly long horizon tasks, lots of money going into the space. Like, is it going to happen? Has anything in your view changed recently? Uh so like my view is kind of informed by what I saw in self-driving and I do feel like self-driving is the first robotics application. So probably what I saw is at the time, like 10 years ago, there were a large number of startups. And I kind of feel like um like most of them basically like didn’t long-term make it. Um and what I saw is that like a lot of capital expenditure had to go in and a lot of time. And so um I think it’s like I think robotics, because it’s so difficult, is so messy, and requires a huge amount of capital investment, and a lot of like conviction.
简体中文
过去几个月,机器人公司展示了更强的环境与任务 generalization、更长 horizon 的行为,也获得大量资本。你认为这次真的会实现吗?近期有什么变化?——我的判断受到自动驾驶经历影响。我认为 self-driving 是第一个大规模机器人应用。十年前有大量自动驾驶 startup,但多数最终没有持续下来。这个领域需要巨额 capital expenditure、极长时间和高度 conviction。
00:55:10
Open at 00:55:10 从此处播放
English
Um just it’s like a big problem and I think atoms are really hard. So I kind of feel like they will lag be it will lag behind what’s going to happen in digital space. And in digital space there’s going to be a huge amount of unhobbling, uh basically like things that weren’t super efficient becoming a lot more efficient by like a factor of a hundred.
简体中文
机器人问题极其复杂而混乱,操作 atoms 很困难,因此其发展会落后于数字空间。数字领域则存在巨大的 ‘unhobbling’:大量原本低效的流程可能提高一百倍。
00:55:25
Open at 00:55:25 从此处播放
English
>> Mhm. Because bits are so much easier. And so I think currently in terms of what’s going to change and like where the activity is, I kind of feel like digital space is going to like change a huge amount. And then the physical space will lag behind. And what I find very interesting is like this interface in between them as well. Because I think in this like if you we do have more agents acting on behalf of humans and more agents kind of like talking to each other and and doing tasks and participating in kind of economy of agents, etc. Um you’re going to run out of things that you’re going to do purely in the digital space. At some point you have to go to the universe and you have to ask it questions. Um you have to run an experiment and see what the universe tells you to get back to learn something. And so we currently have a huge amount of like digital work uh because there’s an overhang in how much
简体中文
bits 远比 atoms 容易处理,所以近期最大的变化会发生在数字空间,物理空间相对滞后。但二者之间的 interface 非常重要。随着更多智能体代表人行动、相互交流并参与 agent economy,纯数字世界中可完成的事情最终会逐渐耗尽。系统必须重新向现实宇宙提问:运行实验,让自然界返回结果。当前还有大量纯数字工作,是因为人类过去没有足够 thinking cycles 来处理已经数字化、已经上传的信息。
00:56:09
Open at 00:56:09 从此处播放
English
we collectively thought about what already is digital. So we just didn’t have enough thinking cycles among the humans to think about all the information that is already digital and already uploaded. Um and so we’re going to start running out of stuff that is actually like um already up uploaded. Uh so you’re going to at some point read all the papers and process them and have some ideas about what to try, but um yeah, we’re just going to uh I don’t actually know how much you can like get intelligence that’s like fully closed off and was just information that’s available in the you know. And so I think what’s going to happen is first there’s going to be a huge amount of unhobbling and I think there’s a huge amount of work there.
简体中文
但智能体最终会读完论文、处理已有数据,并提出需要现实验证的新想法。完全封闭在既有信息中的智能能发展到什么程度,我并不确定。第一阶段将是数字信息处理的大规模解锁,其中已经有海量工作。
00:56:40
Open at 00:56:40 从此处播放
English
Then actually it’s going to move to like the interfaces between physical and digital. So I and that’s like sensors of like seeing the world and actuators of like doing something to the world. >> Mhm. So I think a lot of interesting companies will actually come from that interface of like can we feed the superintelligence in a certain sense uh data and can we actually like take data out and manipulate the physical world um per its bidding if you want to like anthropomorphize the whole thing, right?
简体中文
随后重点会移向 physical-digital interface:sensors 用于观察世界,actuators 用于改变世界。许多有价值的公司会诞生在这一接口上:如何向 superintelligence 输入新的现实数据,以及如何按其计划把输出转化为物理动作——即使这种说法带有 anthropomorphism。
00:57:03
Open at 00:57:03 从此处播放
English
And then the the physical world actually I almost feel like the the total addressable market, etc. in terms of like the amount of work and so on is is massive, possibly even much larger maybe what can happen in digital space. So actually think it’s like a much bigger opportunity as well. But um I do feel like it’s a huge amount of work and and in my in my mind the atoms are just like a a million times harder.
简体中文
从总体工作量和 TAM 看,物理世界甚至可能比数字空间更大。不过它需要巨量工程投入;在我看来,atoms 的难度可能高出几个数量级。
00:57:24
Open at 00:57:24 从此处播放
English
So um so it will lag behind, but it’s also I think a little bit of a bigger market. So it’s kind of like uh yeah, I think the opportunity is kind of like follow that kind of trajectory. So right now is digital is like my main interest. Then interfaces will be like after that and then maybe like some of the physical things um like their time will come and they’ll be huge when they do come.
简体中文
因此,物理自动化会滞后,但长期市场也可能更大。大致轨迹是:当前首先集中于数字空间;随后是传感器与执行器接口;最后,许多纯物理领域的时代会到来,并在到来时形成巨大规模。
00:57:44
Open at 00:57:44 从此处播放
English
Well, it’s it’s it’s an interesting framework for it, too, because uh certain things, not the things I’m working on right now, but certain things are much easier even in the world of atoms. >> Mhm. Right? Like if you just think about like read and write to the physical world, like read, like sensors, cameras, like there’s a lot of existing hardware and you can imagine like enriching agent capabilities or capturing a lot of new data if you just clever about it and like you don’t necessarily have to invest a lot to like get something valuable.
简体中文
这个框架还有一个有用之处:即使在 atoms 世界,有些 read/write 操作也相对容易。read 侧已经存在大量 sensor 和 camera。通过巧妙组合现有硬件,就可以增强智能体能力或采集大量新数据,不一定需要巨额初始投入。
00:58:10
Open at 00:58:10 从此处播放
English
>> Yeah. Right. Yeah. So like examples of this that I saw for example are, you know, um a friend of mine, Liam, is running is a CEO of Periodic. I visited them last week. Yeah. So it was just on top of mind. Like they’re trying to do auto research for materials science. Mhm. Um and so in that case it’s like the sensors to the intelligence are actually like pretty expensive lab equipment. And the same is true in biology. I think a lot of people are very interested in engineering biology and, you know, the sensors will be more than just like video cameras.
简体中文
例如,我的朋友 Liam 是 Periodic 的 CEO,我上周刚参观过他们,因此印象很深。他们尝试在 materials science 中实现 AutoResearch。在这种场景中,智能系统的 sensors 是昂贵实验室设备;biology 也类似。工程生物学需要的传感器显然不只是普通摄像头。
00:58:35
Open at 00:58:35 从此处播放
English
Does that make sense? And then the other thing I was I saw for example is companies that are trying to have um like you basically pay people for training data. Yeah. Yeah. Yeah. Yeah. >> To feed the Yeah. >> programmatically. >> Yeah. To feed to feed the Borg. Uh um and so like these are all examples of like sensors in a certain sense. So they take many diverse shapes and forms if that makes sense. Mhm. Yeah, so I’m looking forward to the point where I can ask for a task in the physical world and I can put a price on it and just tell the agent like, you know, you figure out how to do it. Go get the data.
简体中文
另一类公司会直接付费让人类采集 training data,即以程序化方式‘喂养 Borg’。这些也都是广义 sensor,只是形态各不相同。我期待未来能够给物理世界中的任务标价,然后只对智能体说:自行决定怎样完成,去获取所需数据。
00:59:02
Open at 00:59:02 从此处播放
English
>> I’m actually kind of surprised we don’t have enough like information markets. Mhm. Like if for example if Polymarket or other betting markets or even stocks, etc. If they have so much autonomous activity and rising amount of activity, Mhm. like um why should like for example if Iran was just happening now, like how come there isn’t a process where like taking a photo or video from somewhere in Tehran should cost like 10 bucks? Like someone should be able to pay for that, you know, like and that’s an example of like feeding the intelligence. There’s not going to be a human looking at it, it’s going to be like agents who are trying to guess the betting games and stock markets and so on. Mhm. So I kind of feel like the agentic web is still like fairly new, but there’s no like mechanisms for this, but this is an example of what I I think might happen.
简体中文
目前缺少足够成熟的 information market,这令人意外。Polymarket、其他 betting market 和股票市场中的自治活动越来越多;假设某个重大事件正在伊朗发生,为什么不能有人悬赏十美元,要求从德黑兰某处拍一张照片或视频?最终查看这些数据的可能不是人,而是试图预测博彩市场和股票价格的智能体。这就是为 intelligence 提供现实输入。Agentic web 仍然很新,尚未建立对应市场机制,但未来可能会出现。
00:59:38
Open at 00:59:38 从此处播放
English
Uh there’s a good book that maybe is inspiring called Daemon. Mhm. You potentially read it. In Daemon, the intelligence um ends up like puppeteering almost a little bit like humanity in a certain sense, you know? And so, humans are kind of like it’s actuators, but humans are also like its sensors. Um and so, I think like collectively like society will kind of like reshape in a certain way in uh to to serve that kind of a that will kind of like end up happening collectively across the industry. Where yeah, there’s just a lot more automation and it has certain needs and kind of humans will be serving those needs of that of that machine, not necessarily like to each other.
简体中文
Daniel Suarez 的小说《Daemon》提供了一个有启发性的图景:智能系统在某种意义上操纵整个人类社会,人类既是它的 actuator,也是它的 sensor。现实中,社会可能逐步重塑,以服务不断增长的自动化系统需求。届时,人类有时并不是直接互相服务,而是在满足整个机器体系的输入与执行需求。
01:00:12
Open at 01:00:12 从此处播放
English
>> Well, we were um on this very specific point of uh like missing pieces of training data. We needed um we needed something like auto research, right? Like we we need the training cycle or the SFTP piece to be uh far more mechanized. Mhm. For for which part? >> In order to make the uh collection like to in order to take the human out of the loop to ask for a task that is just like improve my model quality with new data, right? Uh yes.
简体中文
回到缺失 training data 的问题:要形成闭环,我们需要类似 AutoResearch 的机制,使 training cycle 或 SFT 环节(自动字幕疑似识别为 SFTP)高度机械化。——具体指哪一部分?——目的是把人从回路中移除,让系统能够接受这样的高层任务:‘通过收集新数据来提高模型质量。’
01:00:40
Open at 01:00:40 从此处播放
English
Does that make sense to you? Like we um if you can’t have the model do the training runs by itself, then your ability to do this as a like closed loop task with uh by pricing data is um more challenged. Yes, yes, 100%. Yeah. But now you do. >> The thing is for LLM training, it
简体中文
如果模型不能自行运行训练实验,就很难把‘给数据定价—采集数据—重新训练—评价改进’做成完整 closed loop。现在这一点已经开始可行。对于 LLM training 来说,它尤其符合这种范式。
Chapter 12: MicroGPT and agentic education
Chapter start 章节起点: 01:00:59
01:00:59
Open at 01:00:59 从此处播放
English
actually is like very easily it like really fits the paradigm. Mhm. Um so, you’d actually expect >> metric. Yeah, like LLM training actually fits the paradigm really well, really easily. Like all the optimization of all the code and so, it runs faster. And then you also have like metrics that you can optimize against. I do think that if you had an autonomous loop over those metrics, there’s going to be a lot of like good herding going on where the system will like overfit to those metrics. And so, um but then you can use the system to devise more metrics and you just have a really good coverage.
简体中文
LLM training 很容易构造客观 metric,也可以自动优化训练代码以提高速度,因此天然适合 AutoResearch。当然,如果自治 loop 只围绕少量 metric 运行,系统会强烈 overfit 这些指标;但也可以让系统继续设计更多 metric,建立更全面的覆盖。总体而言,这是相当合适的应用。——结束前,我想谈谈你的一个小项目:microGPT。
01:01:26
Open at 01:01:26 从此处播放
English
So, it’s kind of hard to tell, but um in a certain sense it’s like a pretty pretty good fit. I want to talk about a little uh tiny side project you have before we end. Um tell me about the micro GPT arts. Oh, yeah. Okay, so micro GPT. So, I have this like running obsession of like maybe a decade or two of just like simplifying and boiling down the uh basically LLMs uh to like their bare essence. And I’ve had a number of projects along these lines.
简体中文
我大约十到二十年来一直执着于把神经网络和 LLM 简化到最基本的本质,因此做过一系列项目。
01:01:50
Open at 01:01:50 从此处播放
English
So, like nano GPT and um make more and uh micro GPT micro grad etc. So, I feel like micro GPT is now the state of the art of me trying to like just boil it down to just the essence. Because the thing is like training neural nets and LLMs specifically um is a huge amount of code, but all of that code is actually complexity from efficiency. It’s just because you need it to go fast. If you don’t need it to go fast and you just care about the algorithm, then that algorithm actually is uh 200 lines of Python, very simple to read. And this includes comments and everything. Um because you just have like uh your data set which is a text um and you need your neural network architecture which is like 50 lines. You need to do your forward pass and then you have to do your backward pass to calculate the gradients. And so, an auto grad engine uh to calculate the gradients like 100 lines. And then you need an optimizer
简体中文
包括 nanoGPT、makemore、micrograd,现在是 microGPT。对我而言,microGPT 是这条简化路线当前的极致。训练神经网络、尤其训练 LLM,通常包含大量代码,但其中绝大多数复杂性来自 efficiency:为了跑得快,需要各种工程优化。如果完全不要求速度,只关注算法本身,完整 GPT training algorithm 其实只需要约 200 行易读的纯 Python,并且包括注释。你需要文本 dataset;约五十行的 neural network architecture;forward pass;通过 autograd engine 计算 gradient 的 backward pass,而一个最小自动微分引擎约一百行;最后还需要 optimizer。
01:02:35
Open at 01:02:35 从此处播放
English
and Adam for example, uh which is a very state of the art optimizer is like again 10 lines, really. And so, putting everything together in the training loop is like yeah, 200 lines. And what’s interesting to me like normally before like maybe a year ago or more, if I had come up with micro GPT, I would be tempted to basically explain to people. Like I have a video like stepping through it or something like that. Uh and I actually tried to make that video a little bit. And I tried to make like a little guide to it and so on. But I kind of realized that this is is not really is not really adding too much because people cuz it’s already so simple that it’s 200 lines that anyone could ask their agent to explain it in various ways. And the agents like I’m not explaining to people anymore. I’m explaining it to agents. If you can explain it to agents, then agents can be the router and they can actually target
简体中文
Adam 这样的现代 optimizer 实际核心也只有约十行。把这些部分和 training loop 合在一起,大约就是两百行。若在一年前完成 microGPT,我可能会制作逐行讲解视频或编写教程。我也确实尝试过。但后来意识到,这种额外讲解的价值已经有限,因为代码本身足够简单,任何人都可以让自己的智能体以适合自己的方式解释。现在我不再主要向人解释,而是向智能体解释。只要智能体理解,智能体就能充当 router。
01:03:18
Open at 01:03:18 从此处播放
English
it to the human in their language uh with infinite uh you know, patience and uh just at their capability and so on. Right. If I don’t understand um this particular function, I can ask the agent to explain it to me like three different ways and I’m not going to get that from you. Exactly. And so, I kind of feel like, you know, what is education? Like it used to be guides, it used to be lectures, it used to be this thing, but now I feel like now more I’m explaining things to agents and maybe I’m coming up with skills uh where like um uh so, basically skill is just a way to instruct the agent how to teach the thing. So, maybe I could have a skill for micro GPT of the progression I imagine the agent should take you through if you’re interested in understanding the code base. And it’s just like hints to the model to like uh first start off with this and then with that. And so, I could just script the
简体中文
它可以根据学习者的语言、能力和节奏,用无限耐心进行个性化说明。如果我不理解某个函数,可以要求智能体用三种不同方式解释,而传统讲师不可能对每个学习者持续这样做。于是,教育的基本形态会变化。过去依赖 guide、lecture 和固定课程;现在作者可能更多是在为智能体编写 skill。Skill 本质上是一组关于‘如何教授某件事’的指令。例如,可以为 microGPT 编写一个 skill,规定理解代码库时应采用怎样的学习 progression:先介绍什么,再进入什么。
01:04:01
Open at 01:04:01 从此处播放
English
curriculum a little bit as a skill. Uh so, uh so, I I don’t feel like um yeah, I feel like there’s going to be less of like explaining things directly to people and it’s going to be more of just like does the agent get it? And if the agent gets it, they’ll do the explanation. And we’re not fully there yet because they I still can I still think I can probably explain things a little bit better than the agents, but I still feel like the models are improving so rapidly that um I feel like it’s a losing battle to some to some extent.
简体中文
这相当于用 skill 稍微脚本化 curriculum。未来,直接向人解释的比例会下降,关键问题变成:智能体是否真正理解该内容?如果它理解,就能承担讲解。当前还没有完全达到这一状态,我可能仍能在某些方面比智能体解释得更好;但模型进步太快,长期与它竞争讲解能力似乎是一场逐渐失去优势的比赛。
01:04:28
Open at 01:04:28 从此处播放
English
Um and so, I think education is going to be kind of like reshuffled by this quite substantially uh where it’s the end of like teaching each other things a little bit like if I have a um library for example of code or something like that. It used to be that you have documentation for other people who are going to use your library, but like you shouldn’t do that anymore. Like you should have instead of HTML documents for humans, you have markdown documents for agents. Cuz if agents get it, then they can just explain all the different parts of it. So, it’s this redirection through agents, you know?
简体中文
教育会因此被大幅重组,人与人直接传授知识的方式会减少。过去,如果你发布一个 code library,需要为人类用户编写 HTML documentation;未来更合理的做法可能是为智能体编写 Markdown 文档。只要智能体理解库的结构,它就能按不同用户需求解释每个部分。知识传播会先经过智能体这一中介层。
01:04:56
Open at 01:04:56 从此处播放
English
Um and that’s why. So, I think we’re going to see a lot more of that playing out. Well, we’ll see if the great teachers know like to develop intuition for how to explain things to agents differently. >> ultimately, so for example, micro GPT, like I asked I tried to get an agent to write micro GPT. So, I told it like try to boil down the simplest things. Like try to boil down my um neural network training to the simplest thing and it can’t do it. Like micro GPT is like my is it’s like my end of my obsession.
简体中文
未来会出现更多这种模式。优秀教师也许需要形成新的直觉:怎样向智能体解释,才能使智能体再有效地教授人类。以 microGPT 为例,我曾要求智能体自行把神经网络训练简化到最小,但它做不到。microGPT 是我长期 obsession 的终点。
01:05:23
Open at 01:05:23 从此处播放
English
It’s the 200 lines. I thought about this for a long time. I was obsessed about this for a long time. This is this is the solution. Trust me, it can’t get simpler. And this is this is my value add. Everything else like agent gets it. It just can’t come up with it, but it totally gets it and understands why it’s done in a certain way etc. Uh so, like my contribution is kind of like these
简体中文
这两百行是经过多年思考得到的解。我相信它已经无法进一步实质简化。智能体无法独立发现这种最终形式,但一旦看到,就完全能够理解为什么要这样设计。因此,我的 value add 是少数关键 insight;其余理解和教学工作,智能体都可以接管。
Chapter 13: Conclusion
Chapter start 章节起点: 01:05:40
01:05:40
Open at 01:05:40 从此处播放
English
few bits, but everything else in terms of like the education that goes on after that is like not my domain anymore. So, maybe yeah, it’s like education kind of changes in those ways where you kind of have to infuse the few bits that you feel strongly about the curriculum or the the best the better way of explaining it or something like that. The things that agents can’t do is your job now. The things that agents can do, they can probably do better than you or like very soon. And so, you should um be strategic about what you’re actually spending time on. Well, we appreciate the few bits.
简体中文
我的贡献可能只剩下这些少量关键 bits。后续教育过程不再必须由我亲自承担。未来教育者需要注入的是自己真正确信的少数原则:课程结构、最佳解释路径,以及智能体尚不能独立提出的洞见。‘智能体做不到的事情’成为你的工作;智能体已经能做的事情,它很可能比你做得更好,或者很快会如此。因此,应有策略地选择自己投入时间的部分。——我们非常感谢这些关键 bits。
01:06:10
Open at 01:06:10 从此处播放
English
Thank you, Andre. Okay. Find us on Twitter at No Priors Pod. >> [music] >> Subscribe to our YouTube channel if you want to see our faces. Follow the show on Apple Podcasts, Spotify, or wherever you listen. [music] That way you get a new episode every week. And sign up for emails or find transcripts for every episode at no-priors.com.
简体中文
谢谢你,Andrej。欢迎在 Twitter 关注 `No Priors Pod`。订阅 YouTube 频道可以观看视频版;也可以在 Apple Podcasts、Spotify 或其他播客平台关注节目,每周获取新一期内容。邮件订阅和每期 transcript 可在 no-priors.com 获取。
Sources 来源
-
Source video. Primary audiovisual source; the supplied SRT is used for the transcript. 一手视频来源;全文以用户上传 SRT 为准。 https://www.youtube.com/watch?v=kwSVtQ7dziU
-
Karpathy, AutoResearch repository. Official implementation and README. 官方实现与 README。 https://github.com/karpathy/autoresearch
-
Karpathy, AutoResearch program.md. Official agent-loop policy, constraints and logging protocol. 官方智能体循环策略、约束与日志协议。 https://github.com/karpathy/autoresearch/blob/master/program.md
-
Karpathy, microGPT. First-party educational description of the dependency-free implementation. 一手教育性说明。 https://karpathy.github.io/2026/02/12/microgpt/
-
U.S. Bureau of Labor Statistics. Official 2024–2034 occupational projections. 官方职业就业预测。 https://www.bls.gov/emp/tables/occupational-projections-and-characteristics.htm
-
METR, Task-Completion Time Horizons. External evaluation framework and methodological caveats for agent task horizons. 智能体任务时长评测框架及方法限制。 https://metr.org/time-horizons/
Evidence policy 证据规则
| Label | Meaning 含义 |
|---|---|
| Transcript | A claim or thesis stated in the uploaded captions; not independently validated merely by appearing in the interview. 上传字幕中的观点;不能因其出现在访谈中而视为已经独立证实。 |
| Official | Confirmed by an official repository, first-party page, or government source. 由官方仓库、一手页面或政府来源确认。 |
| Analysis | A reasoned synthesis or systems-design inference; explicitly not a disclosure of private implementation details. 基于公开材料的分析或系统设计推断,不代表任何未公开实现。 |
Generated from the supplied SRT on 2026-07-23. 根据用户提供的 SRT 生成。
Bilingual research edition 中英双语研究版