Controlling Reasoning Effort in LLMs · AI Field Notes
It has been almost two years since OpenAI released o1, a model that popularized the idea of LLM-based reasoning models. DeepSeek-R1 followed about four months later, together with details of a reinforcement learning with
It has been almost two years since OpenAI released o1, a model that popularized the idea of LLM-based reasoning models. DeepSeek-R1 followed about four months later, together with details of a reinforcement learning with verifiable rewards (RLVR) recipe to train such reasoning models.
中文译文自 OpenAI 发布 o1 已接近两年。该模型推动了基于 LLM 的推理模型这一概念的普及。约四个月后,DeepSeek-R1 发布,并披露了通过可验证奖励强化学习(reinforcement learning with verifiable rewards,RLVR)训练此类推理模型的方法。
Last week, OpenAI released the GPT-5.6 model family. It comes in three sizes, each with roughly five or six reasoning-effort settings.
中文译文上周,OpenAI 发布了 GPT-5.6 模型家族。该系列包含三种规模,每种规模均提供约五到六档推理强度设置。
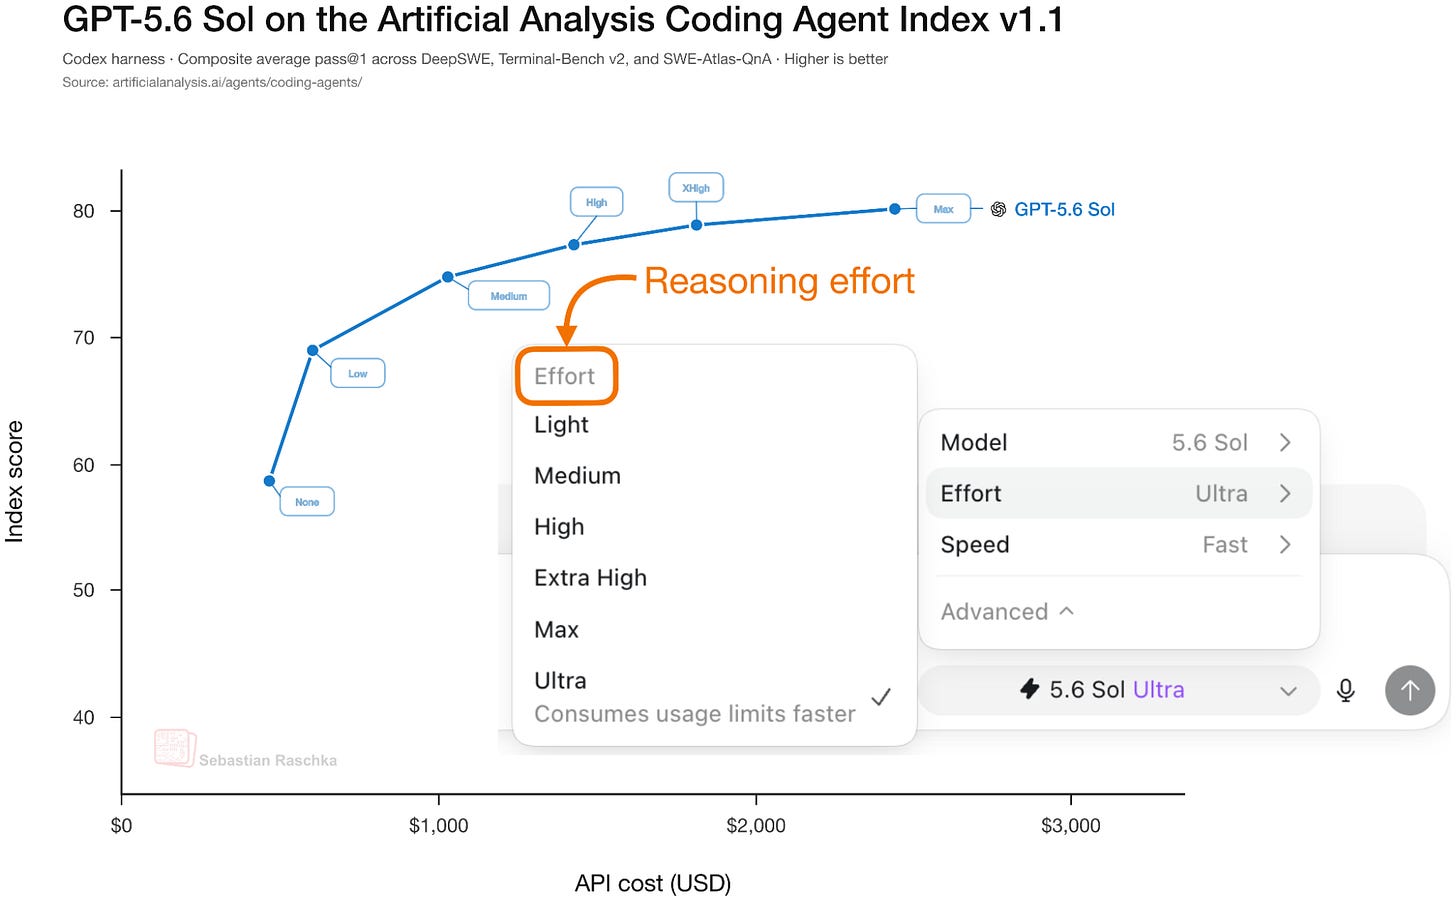
Figure 1: The GPT 5.6 Sol model with different reasoning effort settings. (Benchmark numbers for Ultra are currently not available but should be relatively similar to Max, since it uses a similar effort level but accelerates the work with four subagents.)
中文图注图 1:采用不同推理强度设置的 GPT-5.6 Sol 模型。(Ultra 档位目前尚无基准测试数据,但其表现应与 Max 较为接近,因为二者采用相近的推理强度;Ultra 主要通过四个子代理并行执行来加速处理。)
So yes, reasoning models are here to stay. They have become a standard part of modern model releases.
中文译文由此可见,推理模型不会只是短期现象;它们已经成为现代模型发布中的标准组成部分。
In the past, I covered the methodology of reasoning models (Understanding Reasoning LLMs) as well as relevant research papers (The State of Reinforcement Learning for LLM Reasoning and The State of LLM Reasoning Model Inference). And I even wrote a whole new 440-page book on how to develop reasoning models, Build A Reasoning Model (From Scratch).
中文译文此前,我介绍过推理模型的方法论(《Understanding Reasoning LLMs》),也梳理过相关研究论文(《The State of Reinforcement Learning for LLM Reasoning》和《The State of LLM Reasoning Model Inference》)。此外,我还撰写了一本 440 页的新书《Build A Reasoning Model (From Scratch)》,系统讲解如何开发推理模型。
Figure 2: My new Build A Reasoning Model (From Scratch) book. In color!
中文图注图 2:我的新书《Build A Reasoning Model (From Scratch)》。全彩印刷。
These resources have focused on turning a conventional LLM into a reasoning model. Now, in this article, I want to focus on and explain how to develop a reasoning model that has multiple effort modes, similar to what’s shown in the figure at the beginning of this article.
中文译文这些资料主要讨论如何将传统 LLM 转化为推理模型。本文则进一步聚焦于:如何开发一个支持多档推理强度的推理模型,其效果类似本文开头图示中的设置。
No worries, this article can be read as a standalone article. However, the aforementioned resources may be interesting and useful.
中文译文本文可以独立阅读;不过,上述资料仍可作为有价值的补充参考。 中文1. 推理模型的简要定义
When talking about pretty much any machine learning or AI technique or subfield, the one lesson is that we usually shouldn’t take technical terms “literally”. For example, an (artificial) neural network in machine learning and AI doesn’t literally work like a biological neural network like the human brain.
中文译文讨论几乎任何机器学习或人工智能技术与子领域时,都应避免按字面理解技术术语。例如,机器学习和 AI 中的(人工)神经网络,并不会真正按照人脑等生物神经网络的机制运行。
Similarly, when talking about “reasoning models”, we shouldn’t expect that these models literally reason like us humans. In the context of AI and LLM research, “reasoning model” means a model that outputs an intermediate reasoning trace, which is like an intermediate response that works through a question or task step by step.
中文译文同理,所谓“推理模型”并不意味着模型会像人类一样进行真实的认知推理。在 AI 与 LLM 研究语境中,推理模型通常指能够输出中间推理轨迹(reasoning trace)的模型;该轨迹相当于一个中间响应,用于逐步展开问题或任务的求解过程。
It’s probably easiest to explain this by showing an example.
中文译文通过一个示例最容易说明这一点。
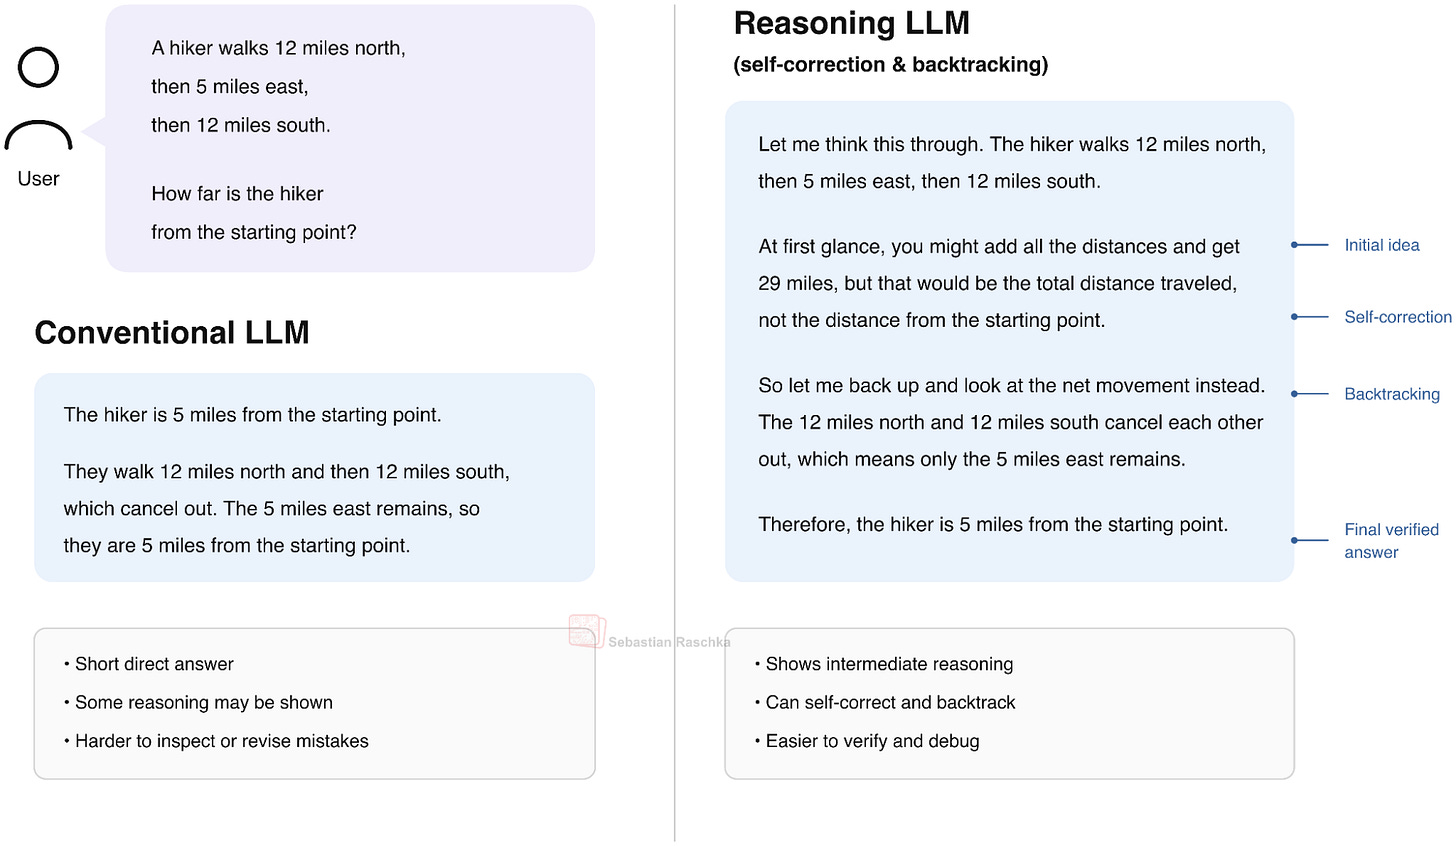
Figure 3: Illustration of a conventional LLM answer (left) and an answer by a reasoning model (right).
中文图注图 3:传统 LLM 的回答(左)与推理模型的回答(右)对比示意图。
2. A brief overview of training and inference scaling reasoning models
中文2. 推理模型的训练扩展与推理扩展概览
There are essentially two ways to improve (reasoning) task performance: training scaling and inference scaling.
中文译文提升(推理)任务性能主要有两条路径:训练扩展(training scaling)与推理扩展(inference scaling)。
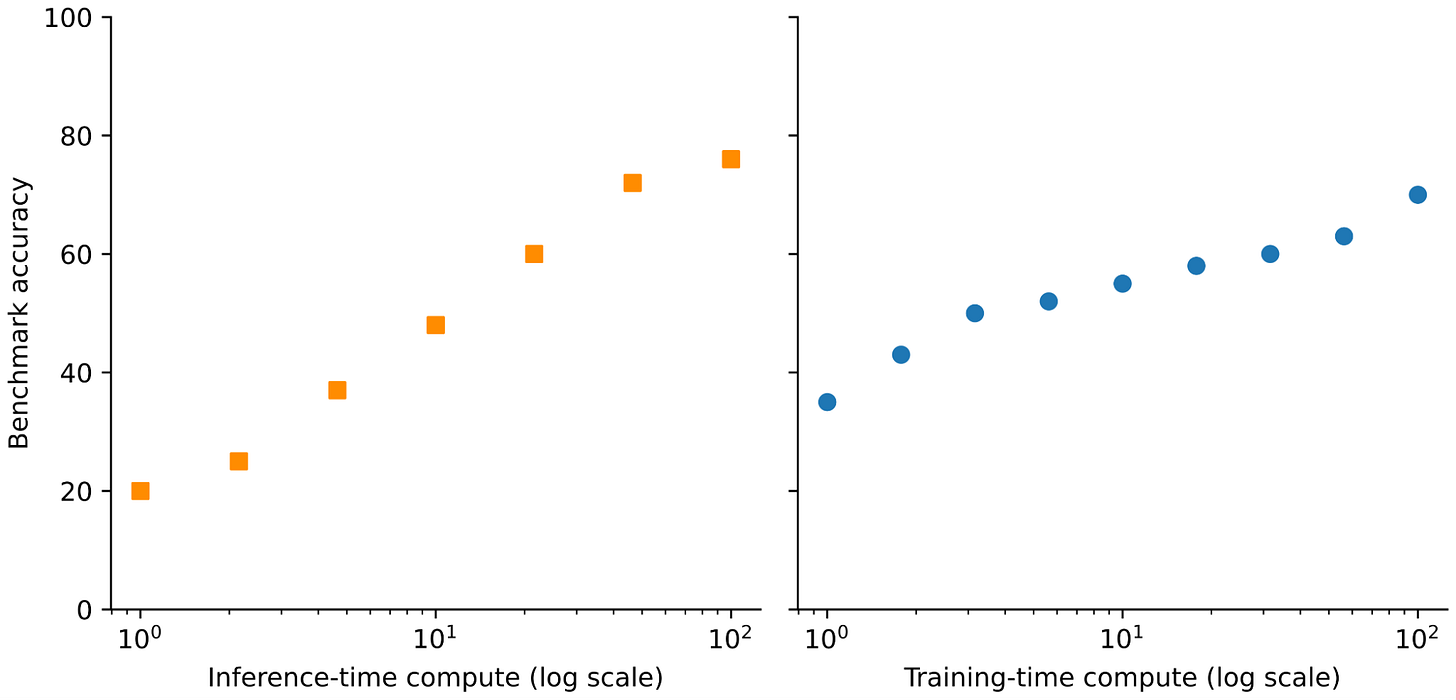
Figure 4: Training and inference-scaling are two ways to improve LLM and reasoning model problem-solving capabilities. Plot based on [Learning to reason with LLMs](https://openai.com/inde x/learning-to-reason-with-llms/)
中文图注图 4:训练扩展与推理扩展是提升 LLM 和推理模型问题求解能力的两种路径。图表依据《Learning to reason with LLMs》绘制。
Let’s briefly talk about training first.
中文译文下面先简要讨论训练。
2.1 Training reasoning models
中文2.1 推理模型的训练
In a nutshell, DeepSeek-R1 proposed training an LLM using reinforcement learning with verifiable rewards (RLVR) to turn it into a reasoning model. RLVR is a technique to provide a reward signal (0=incorrect and 1=correct) for verifiable data domains. These verifiable data domains here are math (we can use a symbolic math checker like SymPy or WolframAlpha to check results) and code (we can use a compiler or unit tests, or integrated platforms like LeetCode) to check for correctness.
中文译文简而言之,DeepSeek-R1 提出使用可验证奖励强化学习(RLVR)训练 LLM,使其转化为推理模型。RLVR 针对结果可验证的数据领域提供奖励信号(0 表示错误,1 表示正确)。这里的可验证领域主要包括数学与代码:数学结果可通过 SymPy、WolframAlpha 等符号计算工具核验;代码正确性则可借助编译器、单元测试,或 LeetCode 等集成平台进行检查。
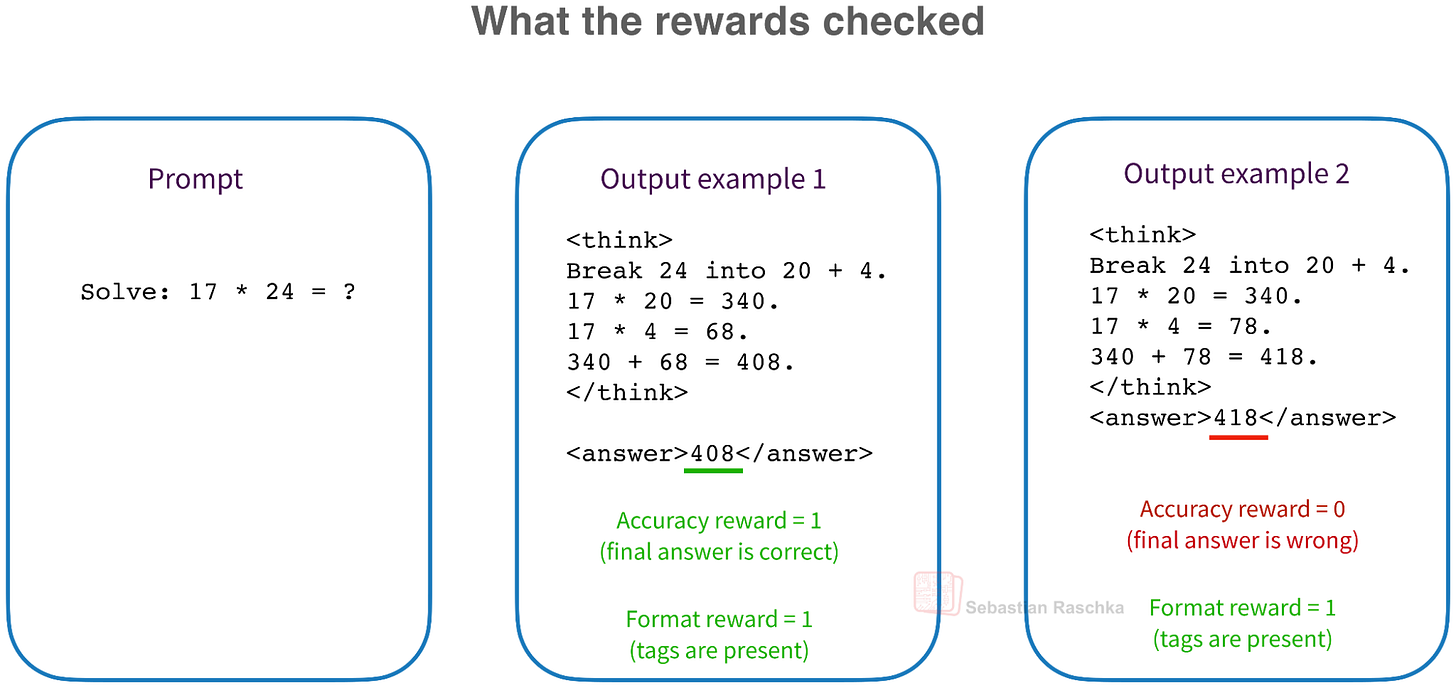
Figure 5: Illustration of accuracy and format rewards during RLVR training.
中文图注图 5:RLVR 训练中的正确性奖励与格式奖励示意图。
Notably, the reasoning trace itself was not used for training or updating the model. Although they tried to use this intermediate response information for training, the DeepSeek-R1 paper reported that it wasn’t helpful for the model training, so it was ultimately not used. (Whether and how to incorporate intermediate reasoning traces in the training signal via process reward models is an active area of research.)
中文译文值得注意的是,推理轨迹本身并未用于训练或更新模型。研究者虽然尝试过利用这部分中间响应信息,但 DeepSeek-R1 论文报告称其对训练没有帮助,因此最终未予采用。(如何通过过程奖励模型(process reward models)将中间推理轨迹纳入训练信号,仍是一个活跃研究方向。)
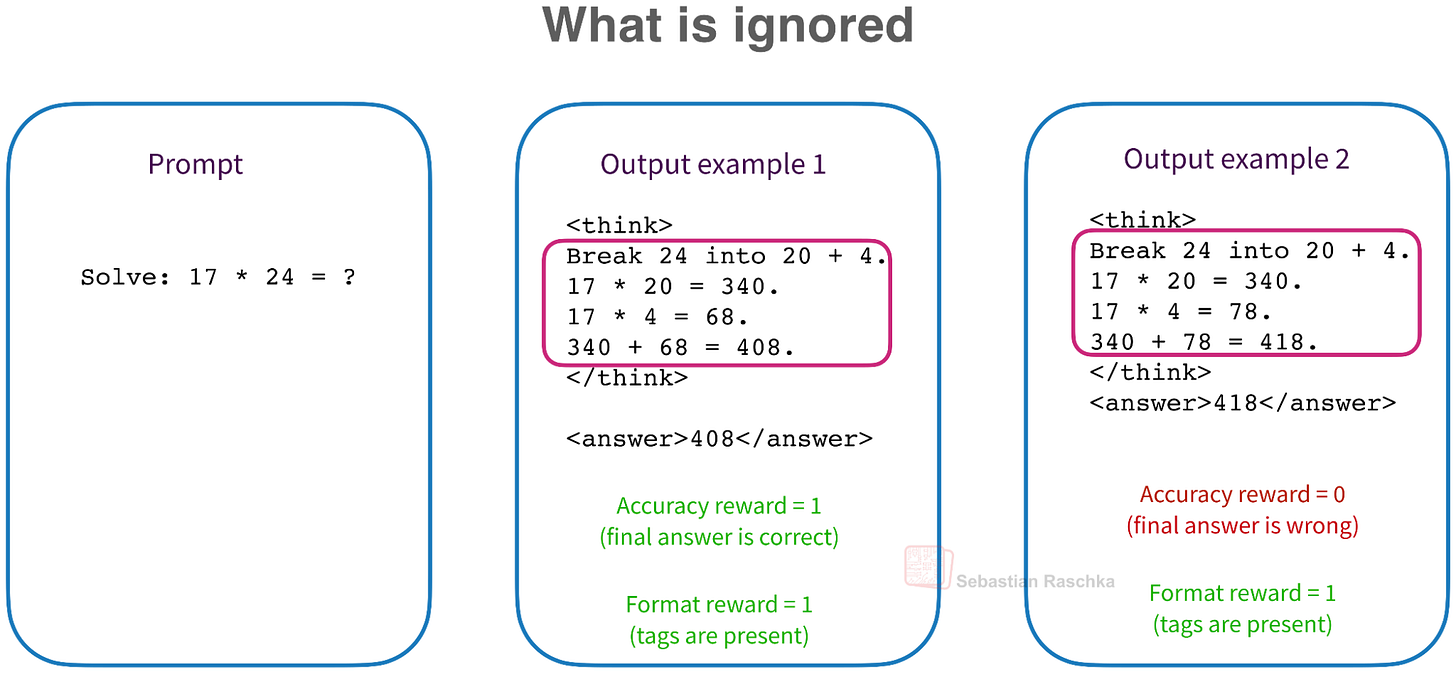
Figure 6: The intermediate reasoning trace is ignored during RLVR; only the final answer and response format determine the reward.
中文图注图 6:RLVR 忽略中间推理轨迹;奖励仅由最终答案及响应格式决定。
2.2 “Aha” moments
中文2.2 “Aha”时刻
Anyway, just training on the output rewards alone, as Figure 7 shows, turned out to be sufficient for the model to learn how to reason through a problem, meaning that it would learn to write intermediate explanations, backtrack, and self-correct itself. These moments when the model realizes that it made a mistake and self-corrects itself are called “Aha” moments.
中文译文如图 7 所示,仅基于输出奖励进行训练,已经足以使模型学会逐步求解问题,包括生成中间解释、回溯以及自我纠错。模型意识到先前推理存在错误并主动修正的情形,通常被称为“Aha”时刻。
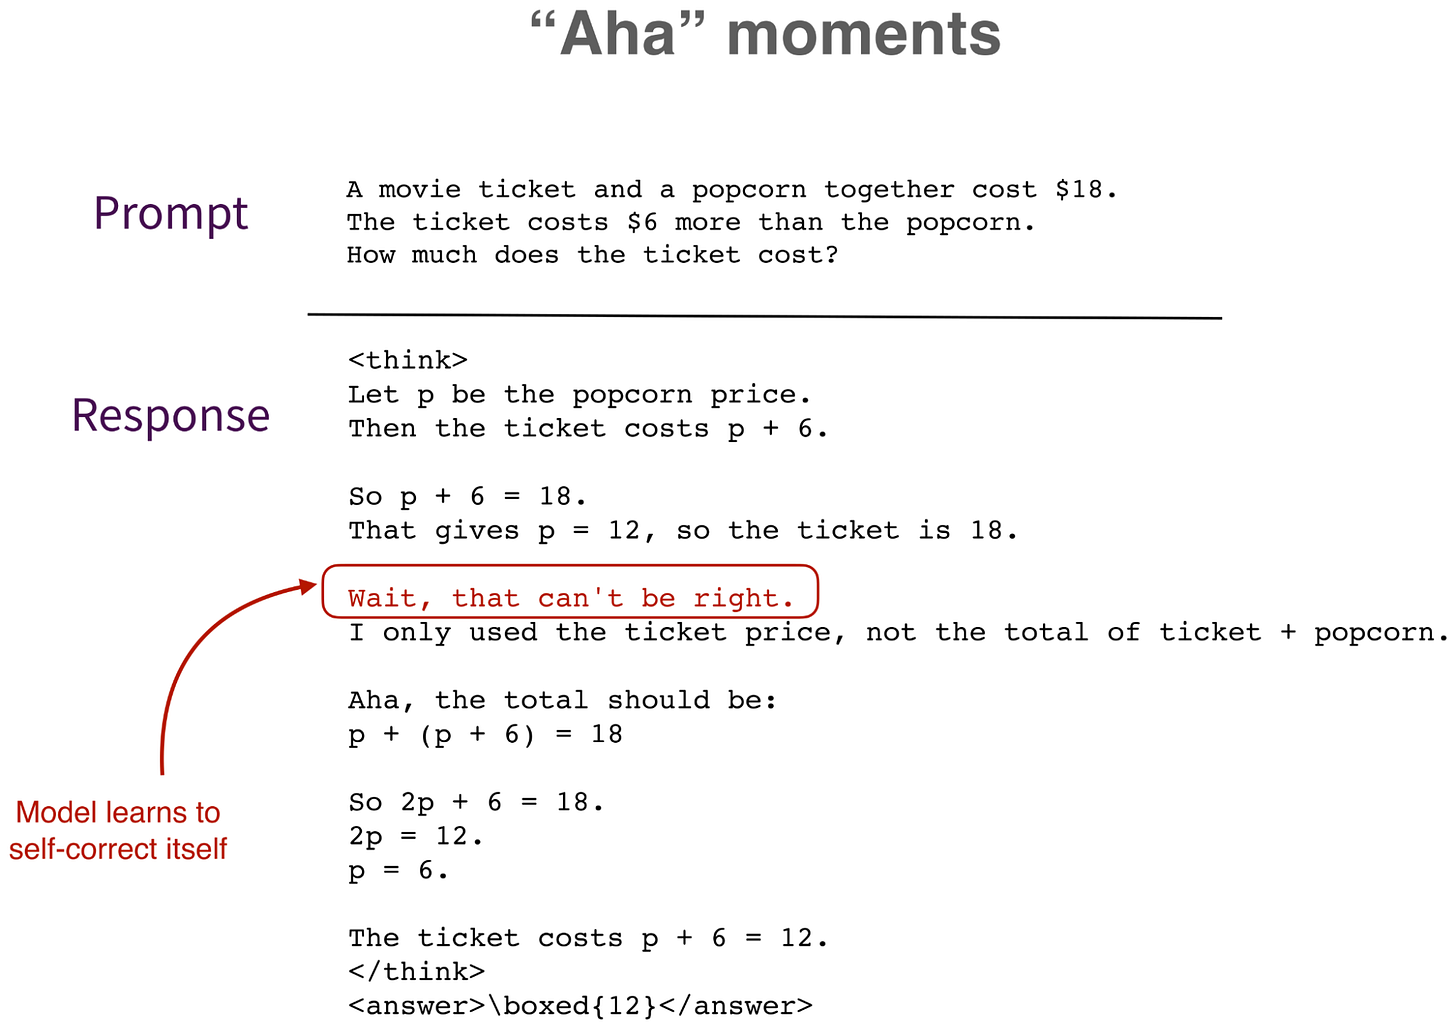
Figure 7: An example of an aha moment, where a reasoning model notices an error in its intermediate reasoning and corrects it before producing the final answer.
中文图注图 7:Aha 时刻示例。推理模型在生成最终答案前发现中间推理中的错误,并完成自我纠正。
By the way, while DeepSeek-R1 is inarguably the more popular paper, and the paper that created excitement around reinforcement learning with verifiable rewards and the development of reasoning models, there is another paper, Kimi K1.5, published on exactly the same day on arXiv (22 Jan 2025). Also, the term RLVR was already coined two months earlier in Tülu 3: Pushing Frontiers in Open Language Model Post-Training.
中文译文虽然 DeepSeek-R1 无疑是更广为人知、也更显著推动 RLVR 与推理模型研究热度的论文,但另有一篇 Kimi K1.5 论文与其在同一天(2025 年 1 月 22 日)发表于 arXiv。此外,“RLVR”这一术语早在两个月前的《Tülu 3: Pushing Frontiers in Open Language Model Post-Training》中已经提出。
One reason why the DeepSeek R1 is ultimately the more popular paper is that it demonstrated that reasoning behavior can be achieved with pure reinforcement learning (RL).
中文译文DeepSeek-R1 最终更具影响力的一个原因,是它证明了仅依靠强化学习(RL)也能够产生推理行为。
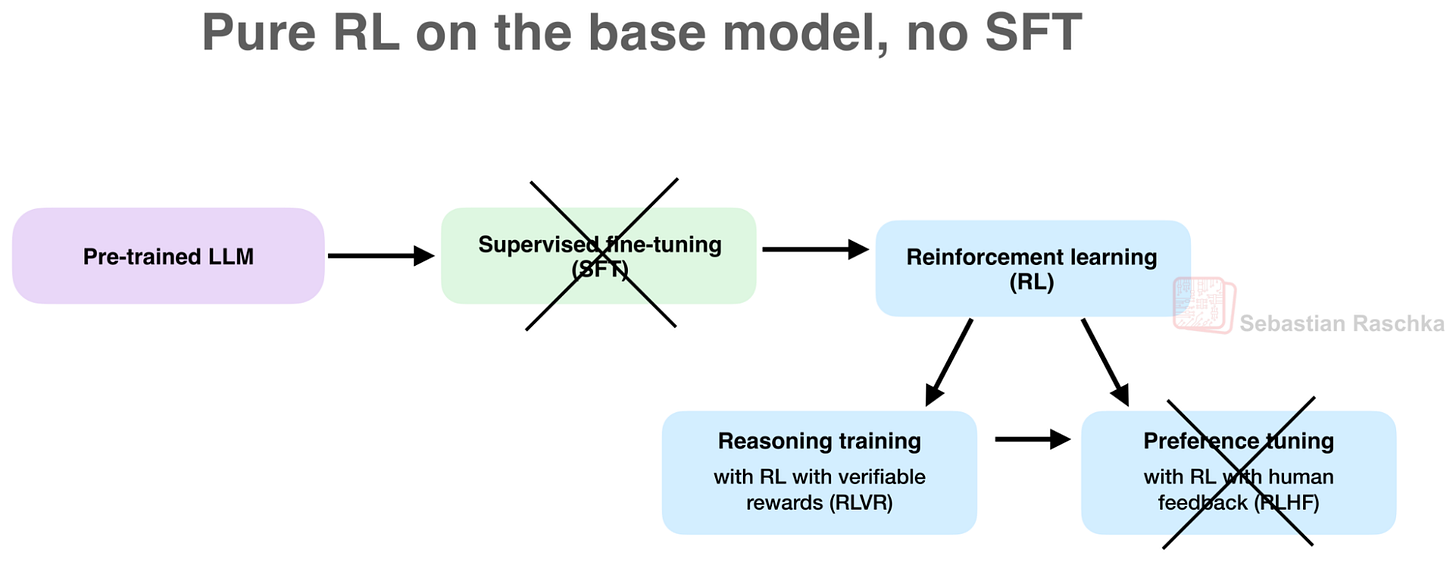
Figure 8: DeepSeek-R1-Zero applies RLVR directly to the pretrained base model without supervised fine-tuning.
中文图注图 8:DeepSeek-R1-Zero 不经过监督微调,直接在预训练基础模型上应用 RLVR。
For instance, Tülu 3 and Kimi K1.5 applied reinforcement learning on top of a supervised fine-tuned (SFT) model. The DeepSeek-R1 model was also trained from an SFT checkpoint of the DeepSeek-V3 base model, and it included a DeepSeek-R1-Zero variant trained with pure RLVR. R1 Zero is a weaker model than R1, but it showed that RLVR is sufficient for teaching the model to generate and use reasoning traces.
中文译文例如,Tülu 3 与 Kimi K1.5 都是在经过监督微调(SFT)的模型之上继续应用强化学习。DeepSeek-R1 同样从 DeepSeek-V3 基础模型的 SFT 检查点出发训练,同时还提供了一个仅使用 RLVR 的 DeepSeek-R1-Zero 变体。R1-Zero 的能力弱于完整的 R1,但它证明了 RLVR 本身足以教会模型生成并利用推理轨迹。
While R1-Zero was more of a proof-of-concept model, note that the full DeepSeek-R1 reasoning model training pipeline is usually multi-stage and a bit more complicated, as mentioned above.
中文译文R1-Zero 更接近概念验证模型。完整的 DeepSeek-R1 推理模型训练流程通常包含多个阶段,并且比上述简化描述更复杂。
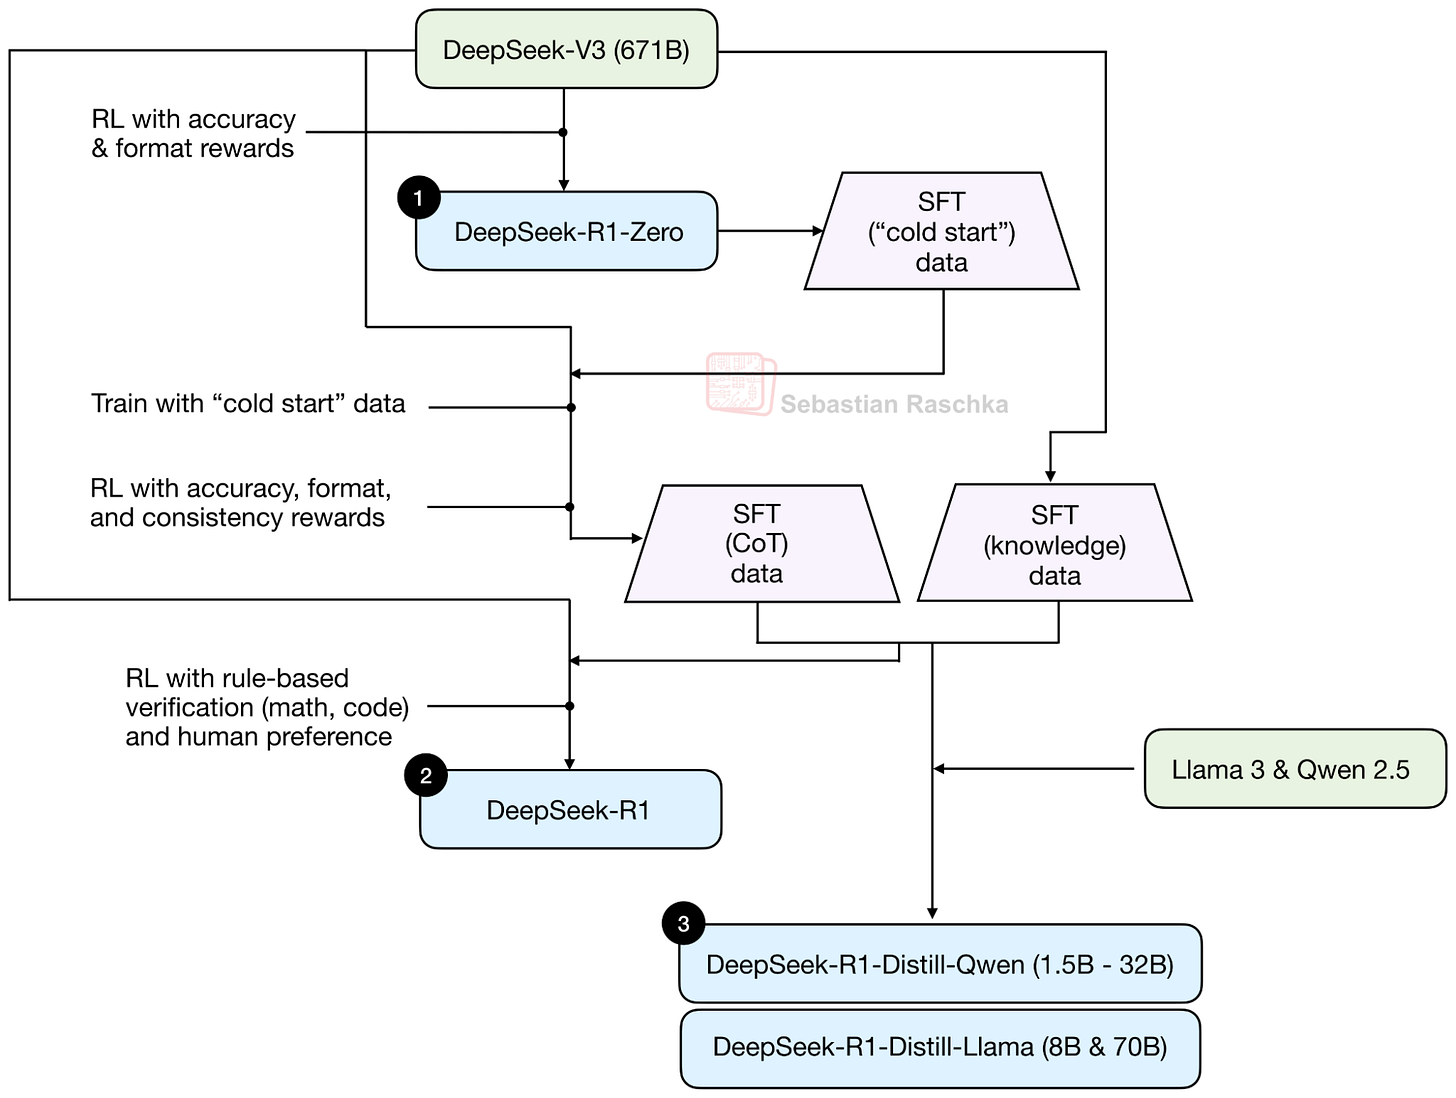
Figure 9: More detailed reasoning model training pipeline. This one depicts the various DeepSeek-R1 models. For more details, see my other article: Understanding Reasoning LLMs
中文图注图 9:更详细的推理模型训练流水线,展示了不同 DeepSeek-R1 模型的关系。更多细节参见我的另一篇文章《Understanding Reasoning LLMs》。
By the way, most of today’s LLMs are effectively reasoning models, meaning they have been trained in a similar fashion to DeepSeek-R1 using a form of RLVR.
中文译文目前的大多数 LLM 实际上都可以视为推理模型,即它们通常采用与 DeepSeek-R1 类似的方式,并通过某种形式的 RLVR 完成训练。
2.3 Inference scaling in a nutshell
中文2.3 推理扩展简述
Next to improving reasoning behavior through training, another lever for improving model performance is inference compute scaling. In short, this means that we are spending more compute after training the model, during usage, to get better answers.
中文译文除了通过训练改进推理行为之外,提升模型性能的另一项重要手段是推理阶段计算扩展(inference compute scaling)。其核心含义是:模型训练完成后,在实际使用期间投入更多计算,以换取更高质量的答案。
This is a whole topic by itself, and you could read through my The State of LLM Reasoning Model Inference for a more detailed rundown:
中文译文这一主题本身足以单独展开。更完整的讨论可参阅我的文章《The State of LLM Reasoning Model Inference》:
中文译文《The State of Reinforcement Learning for LLM Reasoning》,Sebastian Raschka, PhD,2025 年 4 月 19 日。阅读全文。
I will try to summarize what’s most essential to mention as background info below.
中文译文下面仅概括理解本文所需的核心背景。
First, training a model with RLVR is already implicitly leading to a form of inference scaling, since reasoning models usually output more tokens during inference compared to conventional LLMs, and that means we are spending more compute during inference.
中文译文第一,使用 RLVR 训练模型,本身已经隐式引入了一种推理扩展。原因在于,与传统 LLM 相比,推理模型在推理阶段通常会输出更多 token,这意味着推理时消耗了更多计算资源。
Second, we can further adjust this output length via reasoning effort levels, but more on that later.
中文译文第二,还可以通过推理强度等级进一步调节输出长度,后文将详细讨论。
Third, there are many additional inference scaling techniques. A popular one is self-consistency, which is often implemented as a form of majority voting where the model is queried multiple times, and the final answer is selected via majority vote.
中文译文第三,还存在许多额外的推理扩展技术。其中较常见的是自洽性(self-consistency):通常让模型对同一问题生成多次结果,再通过多数投票选择最终答案。
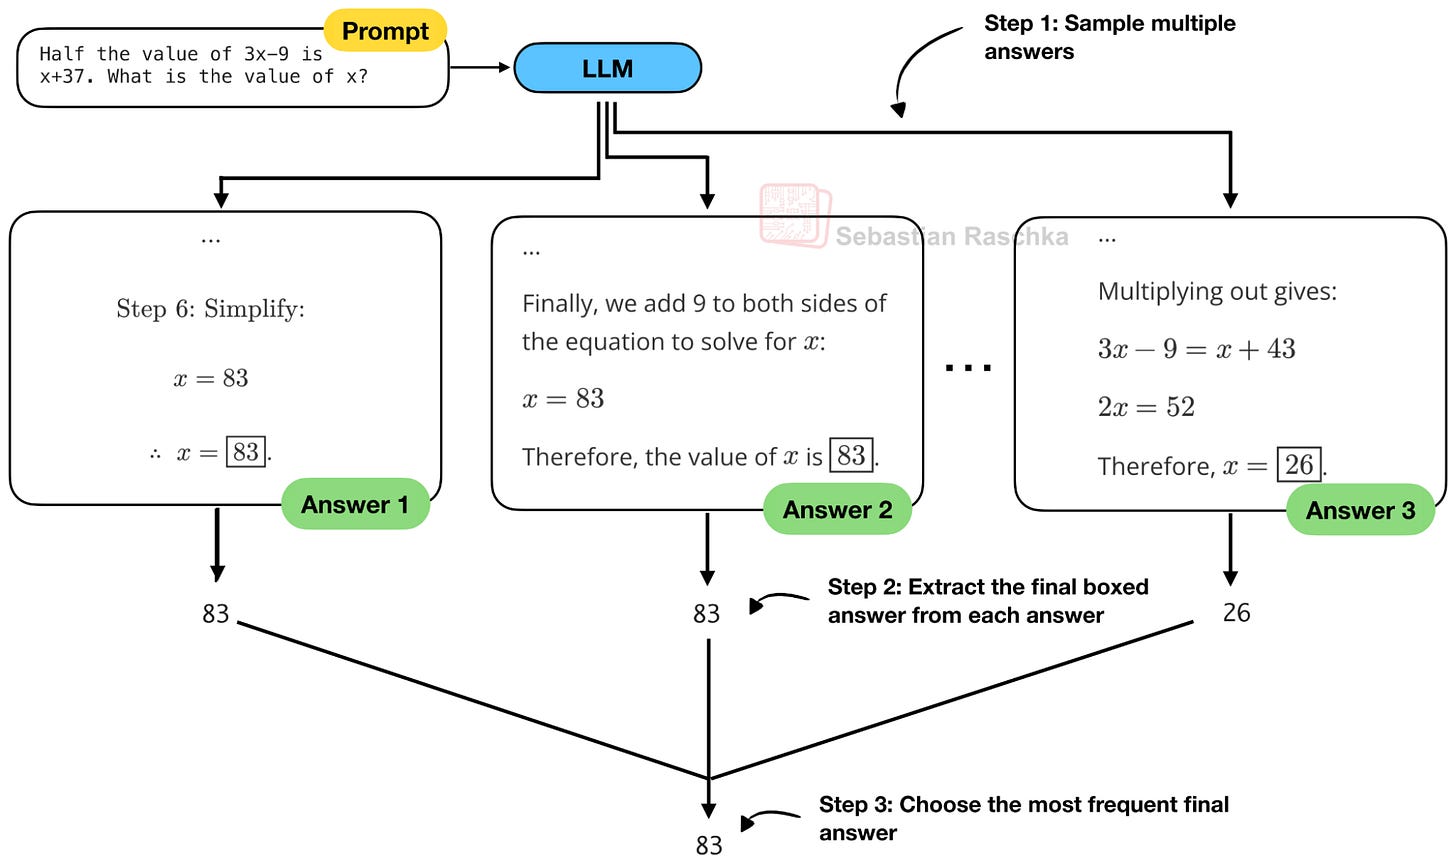
Figure 10: An example of self-consistency, a popular inference scaling technique.
中文图注图 10:自洽性(self-consistency)示例。这是一种常见的推理扩展技术。
This can be applied to conventional LLMs as well as reasoning models. Also, this method can be used on demand and in addition to reasoning training. A good example of that is DeepSeekMath-V2, where the researchers applied extreme inference-scaling on top of a reasoning model (specialized for math) to achieve state-of-the-art performance on challenging math olympiad-type problems.
中文译文这种方法既适用于传统 LLM,也适用于推理模型;并且可以按需启用,与推理训练叠加使用。DeepSeekMath-V2 是一个典型案例:研究者在专门面向数学任务的推理模型之上应用了大规模推理扩展,从而在高难度数学奥林匹克类问题上取得当时的领先性能。
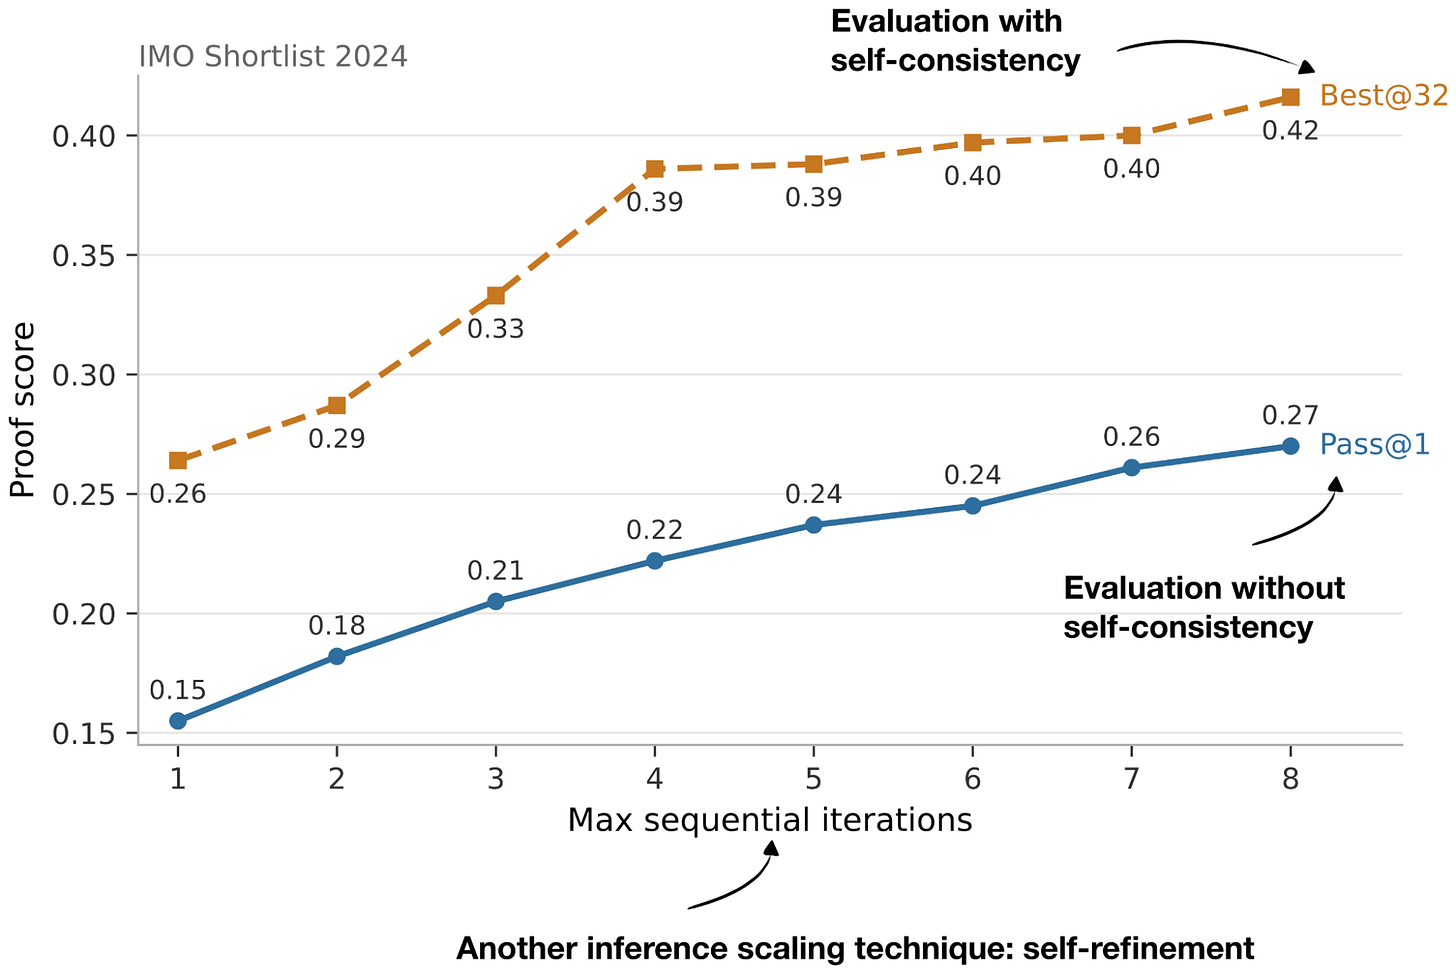
Figure 11: Two types of inference scaling (self-consistency and self-refinement) used together to improve math performance. Figure adapted from DeepSeekMath-V2: Towards Self-Verifiable Mathematical Reasoning
中文图注图 11:将两种推理扩展方法——自洽性(self-consistency)与自我改进(self-refinement)——联合使用,以提升数学任务性能。该图改编自《DeepSeekMath-V2: Towards Self-Verifiable Mathematical Reasoning》。
But again, I will refer to my other article, The State of LLM Reasoning Model Inference for an overview of other techniques:
中文译文其他推理扩展技术的概览,仍可参阅《The State of LLM Reasoning Model Inference》:
The State of LLM Reasoning Model Inference Sebastian Raschka, PhD · 2025年3月8日 Read full story
中文译文《The State of LLM Reasoning Model Inference》,Sebastian Raschka, PhD,2025 年 3 月 8 日。阅读全文。
3. Think tokens
中文3. Think token
You may have seen the <think></think> tokens in the earlier “Aha moments” figure. I also included the corresponding figure below so you don’t have to scroll all the way up.
中文译文你可能已经在前面的“Aha 时刻”图中看到过 `
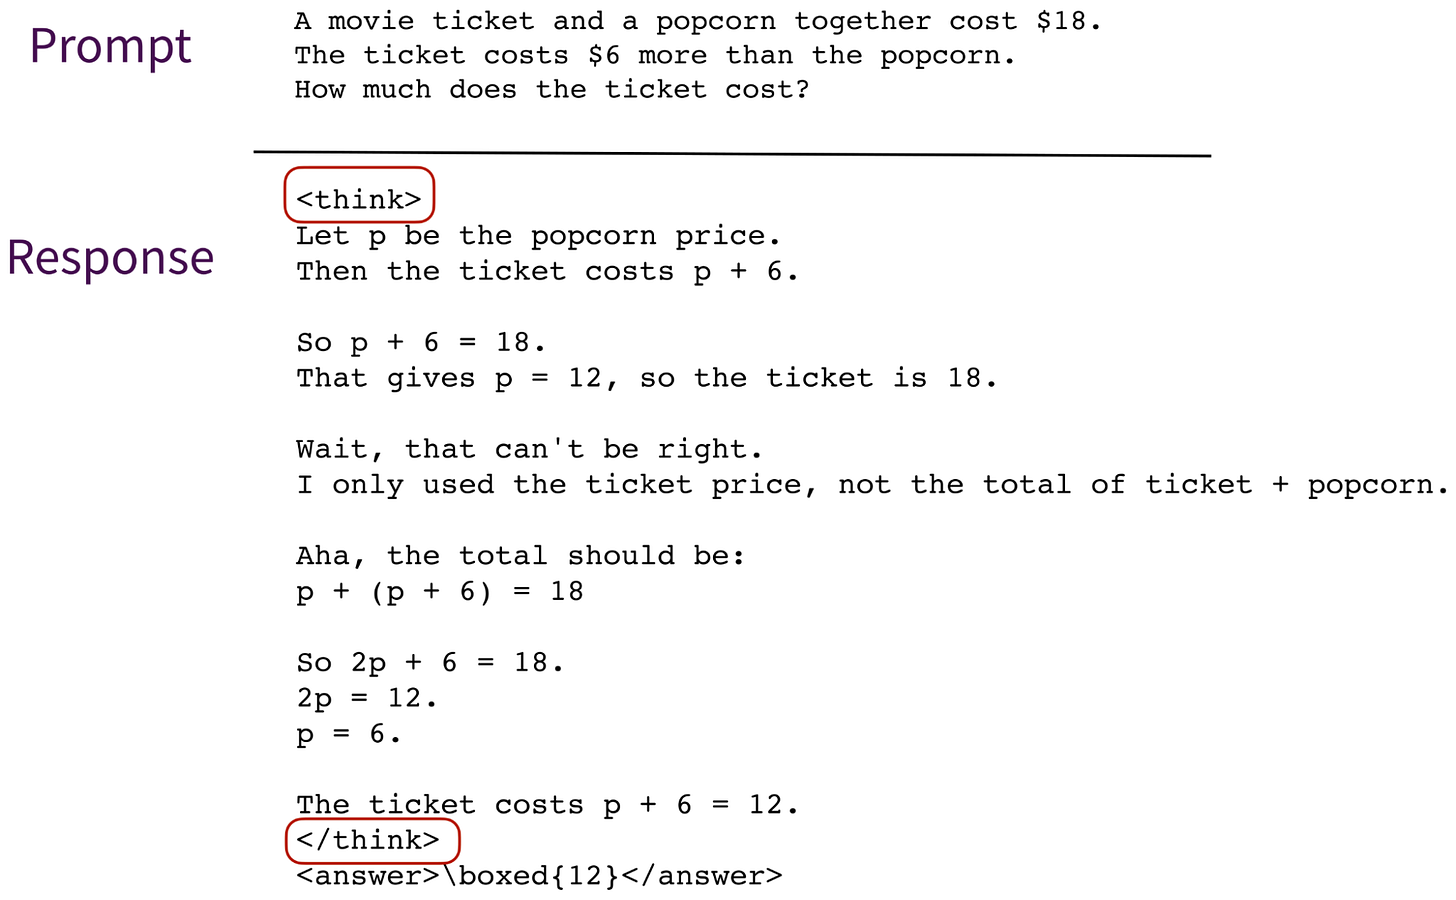
Figure 12: Common formatting tokens in reasoning models.
中文图注图 12:推理模型中常见的格式化 token。
These <think> and </think> tags are cosmetic with respect to reasoning ability. They do not make the model reason, and they are not required to achieve good reasoning performance. One could train the same model without these delimiters and likely reach similar benchmark performance.
中文译文就推理能力而言,`
The purpose of these <think> tags or tokens is mainly to mark where the reasoning trace begins and ends so that the training pipeline or user interface can separate it from the final answer and optionally hide it from the user. (UIs like ChatGPT or Codex usually do this.)
中文译文这些标签或 token 的主要作用,是标记推理轨迹的起止位置,使训练流水线或用户界面能够将其与最终答案分离,并在需要时对用户隐藏。ChatGPT、Codex 等界面通常会采用这种处理方式。
The point here is that the <think> tokens are not giving the model the ability to “think” or reason or reason better. One could train the same models without such <think> tokens and reach similar benchmark performance.
中文译文关键在于,`
There is also nothing special about the literal strings <think> and </think>. Another pair of delimiters could serve the same purpose.
中文译文字面字符串 `
By the way, the way this is implemented is typically by adding a formatting reward during the RLVR stage. So instead of just rewarding the model based on answer correctness, one would provide additional reward for the use of
中文译文这种机制通常通过在 RLVR 阶段加入格式奖励来实现。也除了依据答案正确性给予奖励外,还会对模型正确使用 `
In DeepSeek-R1, for example, the overall reward was calculated as
中文译文例如,在 DeepSeek-R1 中,总奖励计算为:
R_total = R_accuracy + R_format
中文译文`R_total = R_accuracy + R_format`
where the format reward was a simple rule-based check that encouraged the model to place its reasoning inside:
中文译文其中,格式奖励通过一个简单的基于规则的检查实现,鼓励模型将推理内容放置在以下结构中:
<think>
中文译文`
reasoning trace
中文译文推理轨迹
</think>.
中文译文``。
4. Reasoning mode on and off switches
中文4. 推理模式的开启与关闭
The first generation of reasoning models was dedicated reasoning models. With that, I mean that there was a DeepSeek-V3 base model and a separate DeepSeek-R1 reasoning model.
中文译文第一代推理模型通常是专用模型。也DeepSeek-V3 是基础模型,而 DeepSeek-R1 则是独立的推理模型。
No matter what the prompt is, R1 generally outputs very verbose responses using lots of tokens, even for simple prompts. It also lacks a built-in option to turn off the reasoning mode.
中文译文无论提示词内容如何,R1 通常都会生成非常冗长的响应并消耗大量 token,即使面对简单问题也是如此;同时,它也没有内置的推理模式关闭选项。
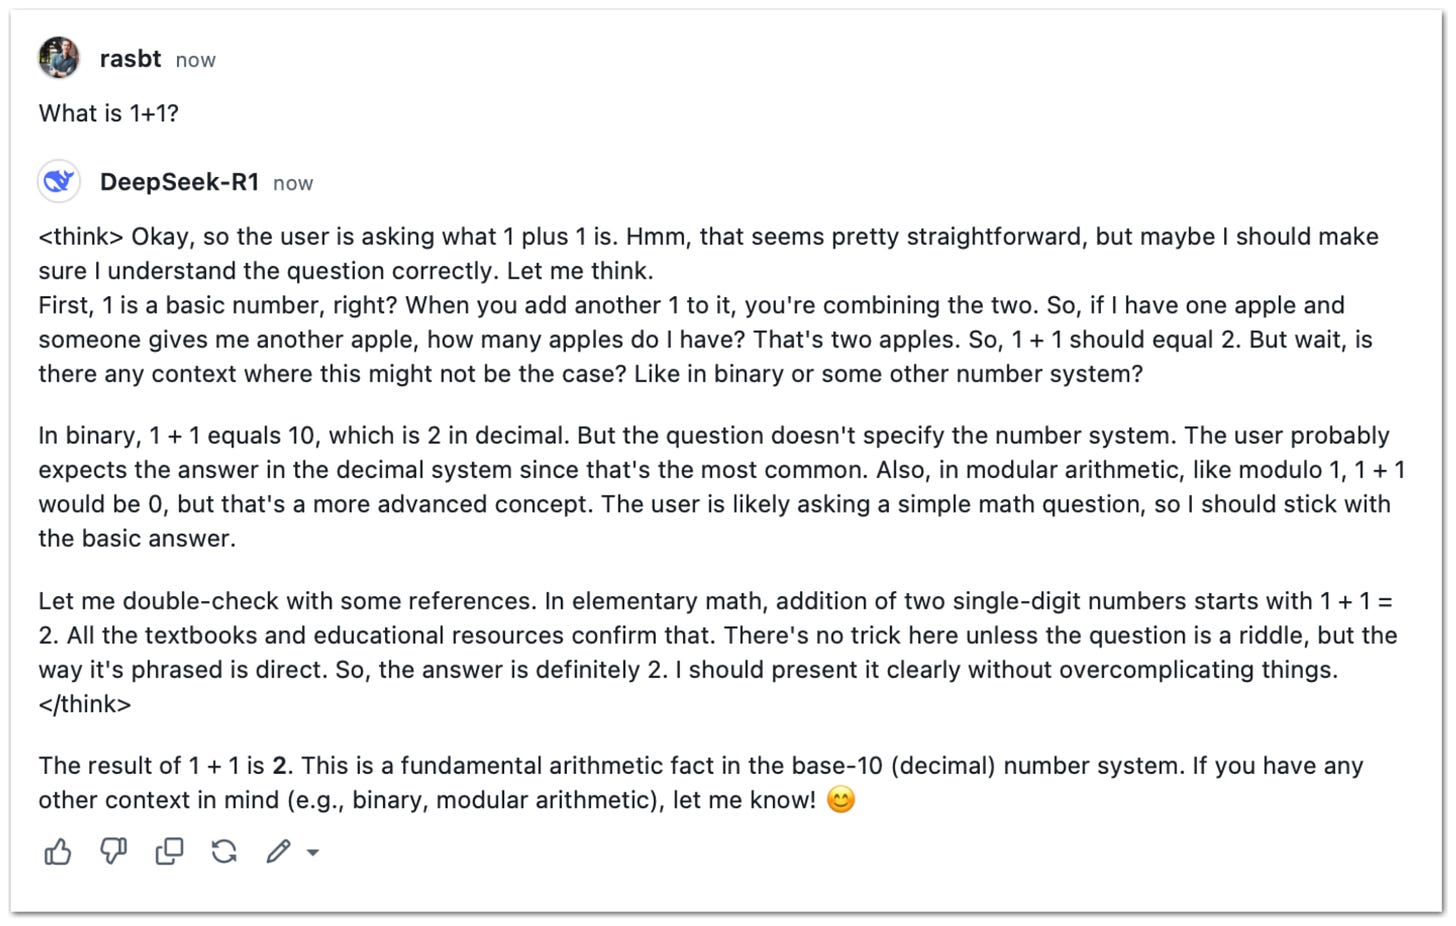
Figure 13: Reasoning models are very verbose, even for the simplest prompts.
中文图注图 13:即使面对最简单的提示词,推理模型也往往十分冗长。
Later models, like Qwen3 and others, experimented with hybrid approaches, where the same model can behave like a regular instruction fine-tuned model or a reasoning model on demand.
中文译文后续模型(如 Qwen3 等)开始探索混合方案,使同一个模型可以按需表现为普通指令微调模型,或切换为推理模型。
Note: Some model developers call this “thinking mode,” while others call it “reasoning mode.” Both terms refer to the same behavior.
中文译文注:部分模型开发者称其为“thinking mode”,另一些则称为“reasoning mode”;二者指的是同一种行为。
In Qwen3, this is handled via the tokenizer using enable_thinking=True or enable_thinking=False. Under the hood, setting enable_thinking=False essentially adds an empty <think></think> section to the beginning of the assistant response to turn off Qwen3’s reasoning (”thinking”) mode.
中文译文在 Qwen3 中,该开关通过 tokenizer 的 `enable_thinking=True` 或 `enable_thinking=False` 控制。其底层机制是:当设为 `False` 时,在 assistant 响应开头预填一个空的 `
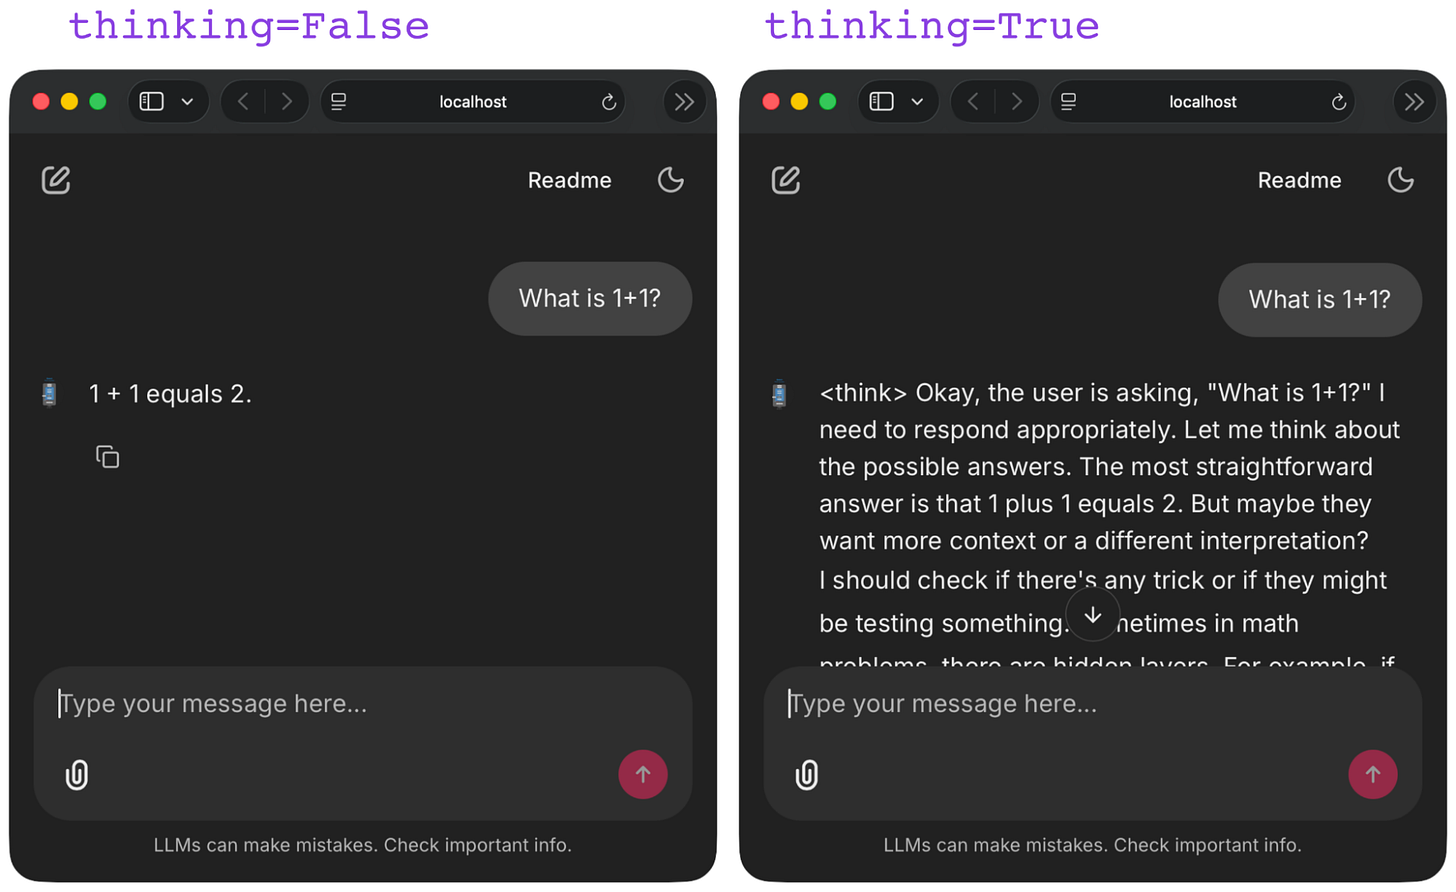
Figure 14: Response of Qwen3 0.6B reasoning model with thinking=False and thinking=True. (The empty <think></think> tags are hidden in the interface on the left as they are part of the modified input prompt, not the generated answer.)
中文图注图 14:Qwen3 0.6B 推理模型在 `thinking=False` 与 `thinking=True` 下的响应。(左侧界面隐藏了空的 `
How is this implemented during training, such that the model supports this toggle during inference time, as shown in the figure above?
中文译文那么,训练过程中如何实现这种机制,使模型在推理阶段支持上述切换?
In short, as explained in the Qwen3 technical report, this on/off behavior is introduced primarily through supervised fine-tuning (SFT) and then reinforced during general RL in their largest flagship models.
中文译文按照 Qwen3 技术报告的说明,这种开关行为主要通过监督微调(SFT)引入,并在其最大旗舰模型的通用 RL 阶段进一步强化。
For instance, after the initial reasoning model is trained via long-chain-of-thought SFT and reasoning RL, they add a “Thinking Mode Fusion” stage. During this additional SFT stage, the model sees both thinking and non-thinking examples:
中文译文具体而言,在通过长链式思维 SFT 与推理 RL 完成初始推理模型训练后,Qwen3 增加了一个“Thinking Mode Fusion”阶段。在该额外 SFT 阶段,模型同时接触思考模式与非思考模式样本:
-
/think: <think>{reasoning}</think>{answer} -
/no_think: <think></think>{answer}
中文译文`/think`:`
`/no_think`:`
Thinking is the default behavior, so /think can also be omitted. The subsequent general RL stage further reinforces this mode and format following.
中文译文思考模式是默认行为,因此 `/think` 也可以省略。随后的通用 RL 阶段会进一步强化模型对模式指令与格式的遵循。
These /think and /no_think flags are a “soft” switch. However, the enable_thinking=False setting mentioned earlier, which force-adds the empty <think></think> in the False case, acts then as a “hard” switch.
中文译文`/think` 与 `/no_think` 属于“软”开关;而前述 `enable_thinking=False` 会在 `False` 情况下强制加入空的 `
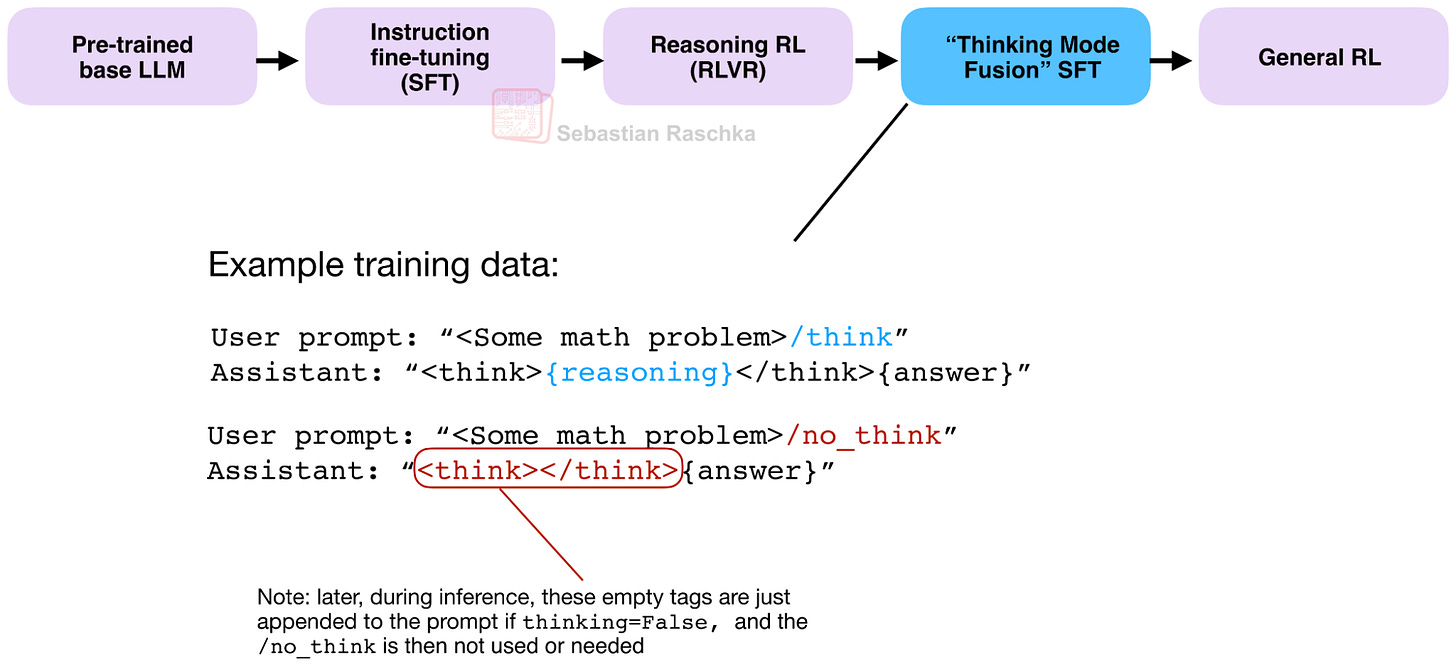
Figure 15: “Thinking Mode Fusion” in Qwen3’s training pipeline to enable the reasoning mode on and off switch.
中文图注图 15:Qwen3 训练流水线中的“Thinking Mode Fusion”,用于实现推理模式开关。
In other words, the tokenizer does not add /no_think to the query. It directly fills in the empty <think></think> section at the beginning of the assistant response. The model only sees the resulting tokens and continues directly with the answer.
中文译文换言之,tokenizer 并不是把 `/no_think` 加到用户查询中,而是直接在 assistant 响应开头填入空的 `
Anyway, this on-and-off toggle is essentially a simplified version of the reasoning effort levels in GPT-5.6 and others, which I cover in the next section.
中文译文这种开关机制本质上是 GPT-5.6 等模型多档推理强度设置的简化版本,下一节将进一步说明。
5. How “reasoning effort” settings work
中文5. “推理强度”设置如何工作
In this section, I want to provide a brief overview of how the different reasoning effort toggles may be implemented, which have been introduced in models like GPT 5 and are present in pretty much any flagship model today.
中文译文本节简要介绍不同推理强度开关可能的实现方式。这类设置最早出现在 GPT-5 等模型中,如今几乎已成为各类旗舰模型的标准功能。
Concretely, at the beginning of this article, I showed a figure from the Codex GPT 5.6 interface that lets users select multiple reasoning “effort” settings.
中文译文本文开头展示了 Codex GPT-5.6 界面,其中用户可以选择多档推理“强度”。
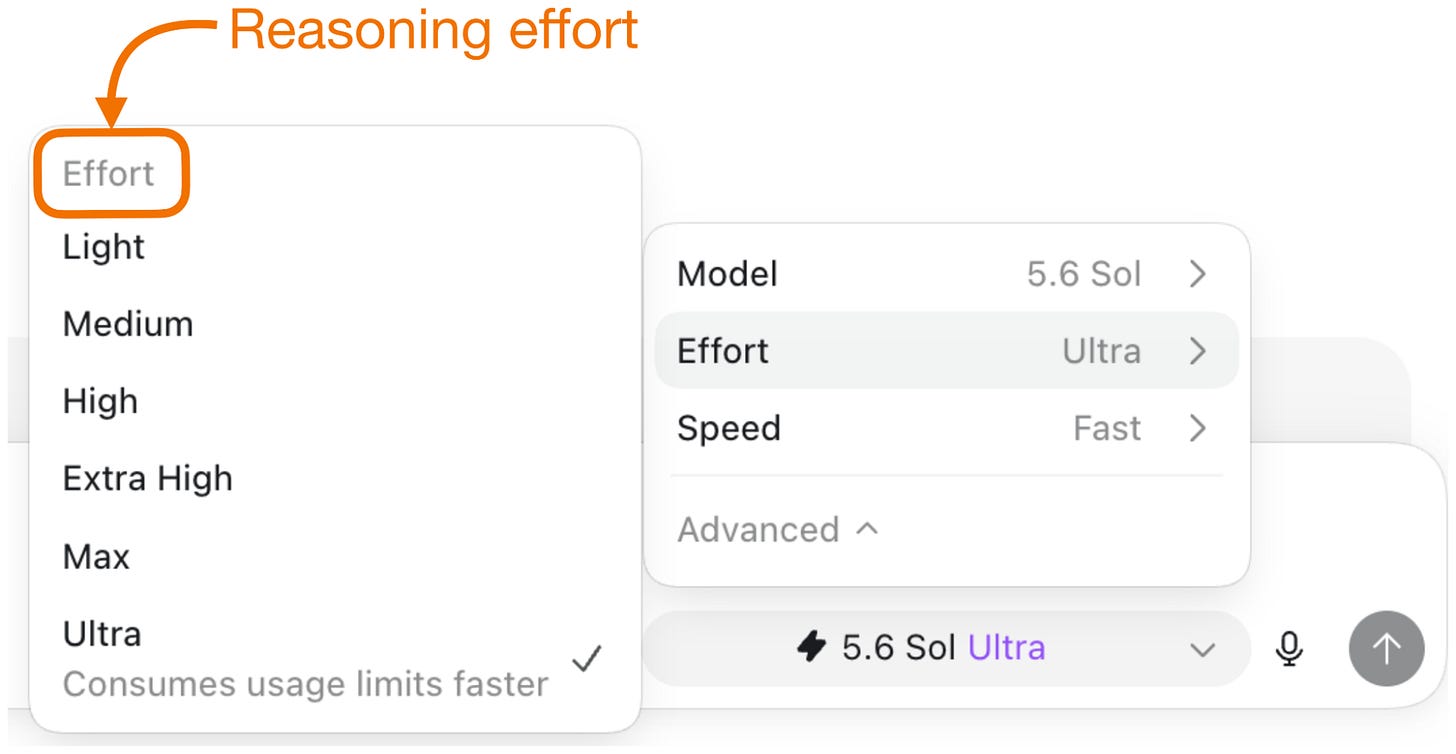
Figure 16: GPT-5.6 exposes six reasoning effort settings, ranging from Light to Ultra.
中文图注图 16:GPT-5.6 提供六档推理强度设置,从 Light 到 Ultra。
The following subsection will illustrate how these settings may be implemented. Then, in the next section, I will go over some of the more interesting research papers related to this topic.
中文译文下一小节将说明这些设置可能如何实现;随后一节则讨论与该主题相关的若干较有代表性的研究工作。
5.1 Reasoning effort and response length and quality
中文5.1 推理强度与响应长度、质量的关系
Unfortunately, the implementation details of their effort settings are not shared by OpenAI, but there is some evidence out there that can be used for educated guesses.
中文译文OpenAI 并未公开其推理强度设置的实现细节,但现有信息仍足以支持一些有依据的推断。
For instance, via their open-source gpt-oss models from last year (I wrote about them in From GPT-2 to gpt-oss: Analyzing the Architectural Advances), we know that OpenAI allows us to toggle the reasoning effort setting via the system prompt (”Reasoning effort: low/medium/high”) that is prepended to each prompt.
中文译文例如,根据 OpenAI 去年发布的开源 gpt-oss 模型(我在《From GPT-2 to gpt-oss: Analyzing the Architectural Advances》中做过分析),其推理强度通过系统提示控制:在每个提示词前加入“Reasoning effort: low/medium/high”。
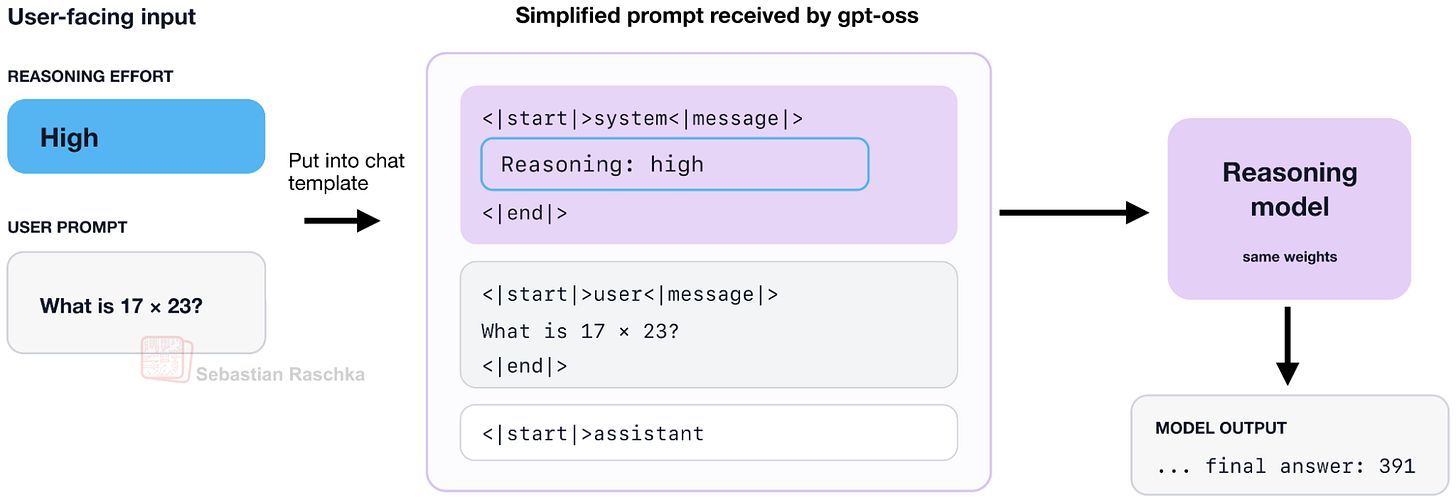
Figure 17: The gpt-oss chat template inserts the selected reasoning effort into the system message before sending the prompt to the same model.
中文图注图 17:gpt-oss 的 chat template 会把所选推理强度写入 system message,再将提示词发送给同一个模型。
As expected, the reasoning effort directly affects the response length and accuracy, as shown below.
中文译文正如预期,推理强度会直接影响响应长度与准确率,如下图所示。
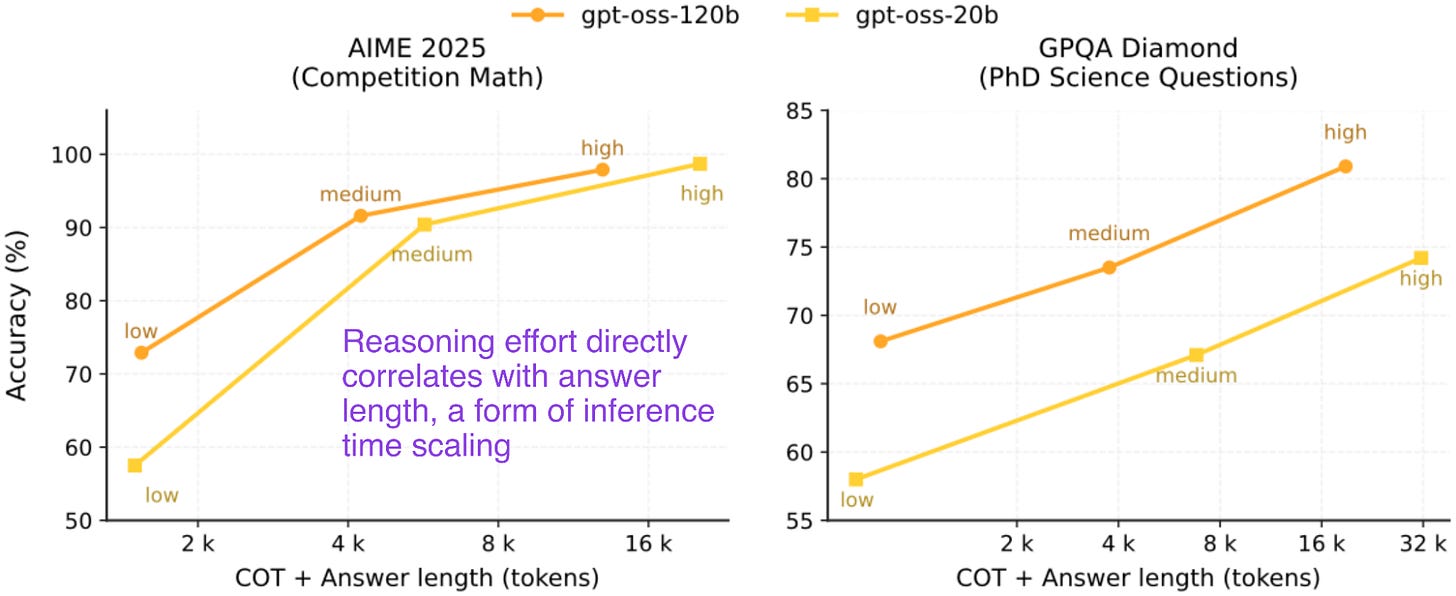
Figure 18: Response length and quality of gpt-oss models under different reasoning efforts (annotated figure from the model card)
中文图注图 18:gpt-oss 模型在不同推理强度下的响应长度与质量。(标注图源自 model card。)
Presumably, their GPT 5 models, including the recent GPT 5.6 models, use a similar approach.
中文译文可以合理推测,包括最新 GPT-5.6 在内的 GPT-5 系列采用了类似方法。
By the way, note how different effort settings scale the response length in the figure above. The effort level seems directly correlated to token usage, which in turn seems correlated to accuracy. It might be possible to come up with effort settings beyond the “high” one, but I assume performance would saturate at some point. This saturation can be seen more clearly for the GPT 5.6 Sol model, which also shows that increasing reasoning budgets can become uneconomical at some point.
中文译文请注意上图中不同强度设置对响应长度的影响。推理强度似乎与 token 使用量直接相关,而 token 使用量又与准确率相关。理论上可以设置高于“high”的档位,但性能最终应会趋于饱和。GPT-5.6 Sol 的结果更清楚地体现了这一点:继续提高推理预算,在某个阶段之后可能不再具备经济性。
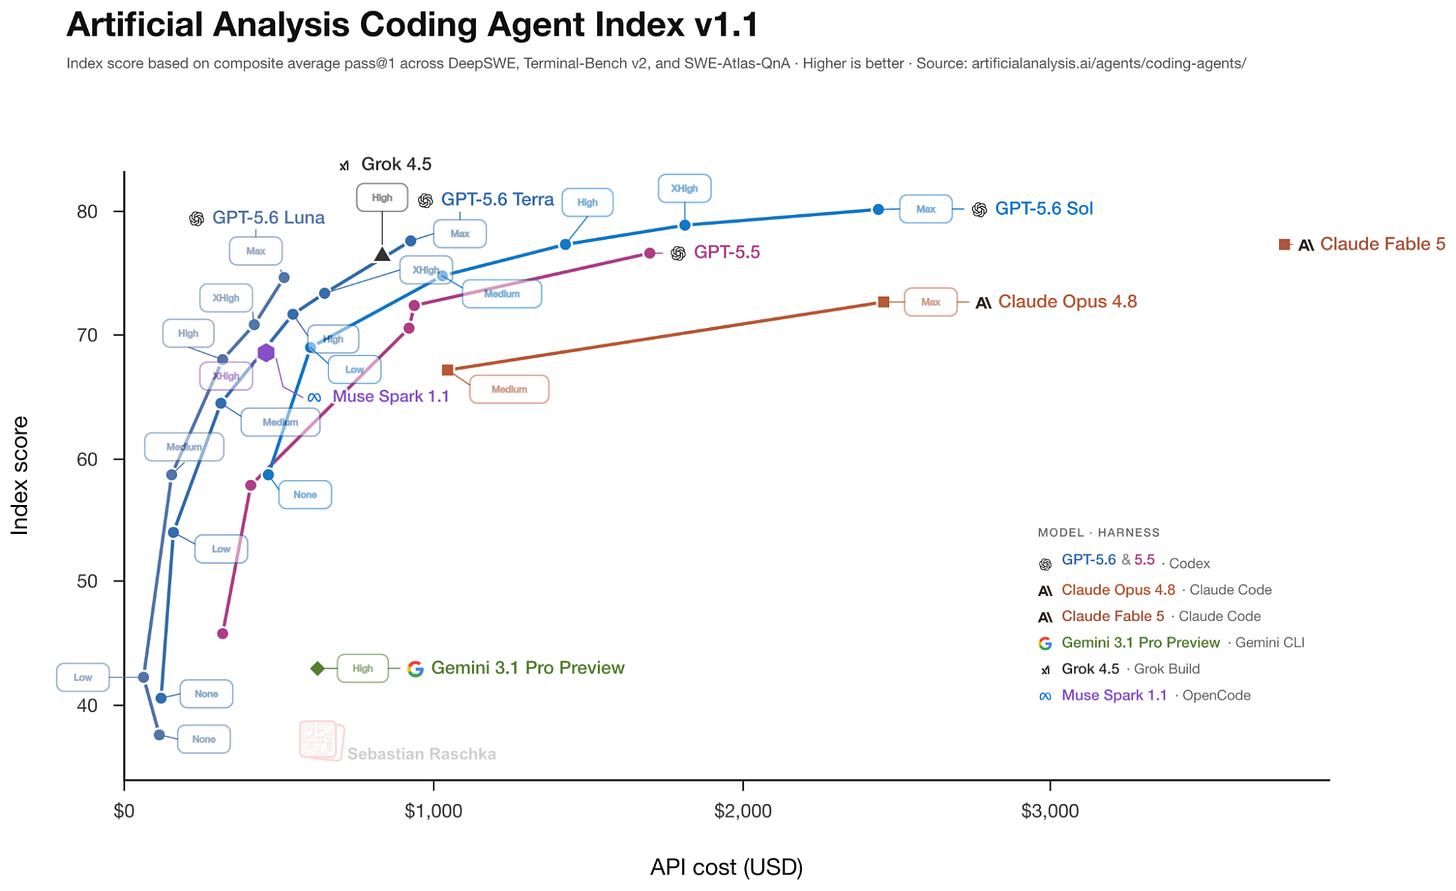
Figure 19: Reasoning effort increases both API cost and coding-agent performance, with diminishing returns at the highest GPT-5.6 settings. Figure based on the Artificial Analysis Coding Agent Index v1.1.
中文图注图 19:提高推理强度会同时增加 API 成本与编码代理性能,但在 GPT-5.6 的最高档位出现明显的边际收益递减。图表依据 Artificial Analysis Coding Agent Index v1.1 绘制。
Another good, very recent data point that shows the relationship between reasoning effor t, token usage, and benchmark performance is this week’s new open-weight Inkling release by Thinking Machine Labs.
中文译文另一个非常近期、也能清楚展示推理强度、token 使用量与基准性能关系的数据点,是 Thinking Machines Lab 本周发布的开放权重模型 Inkling。
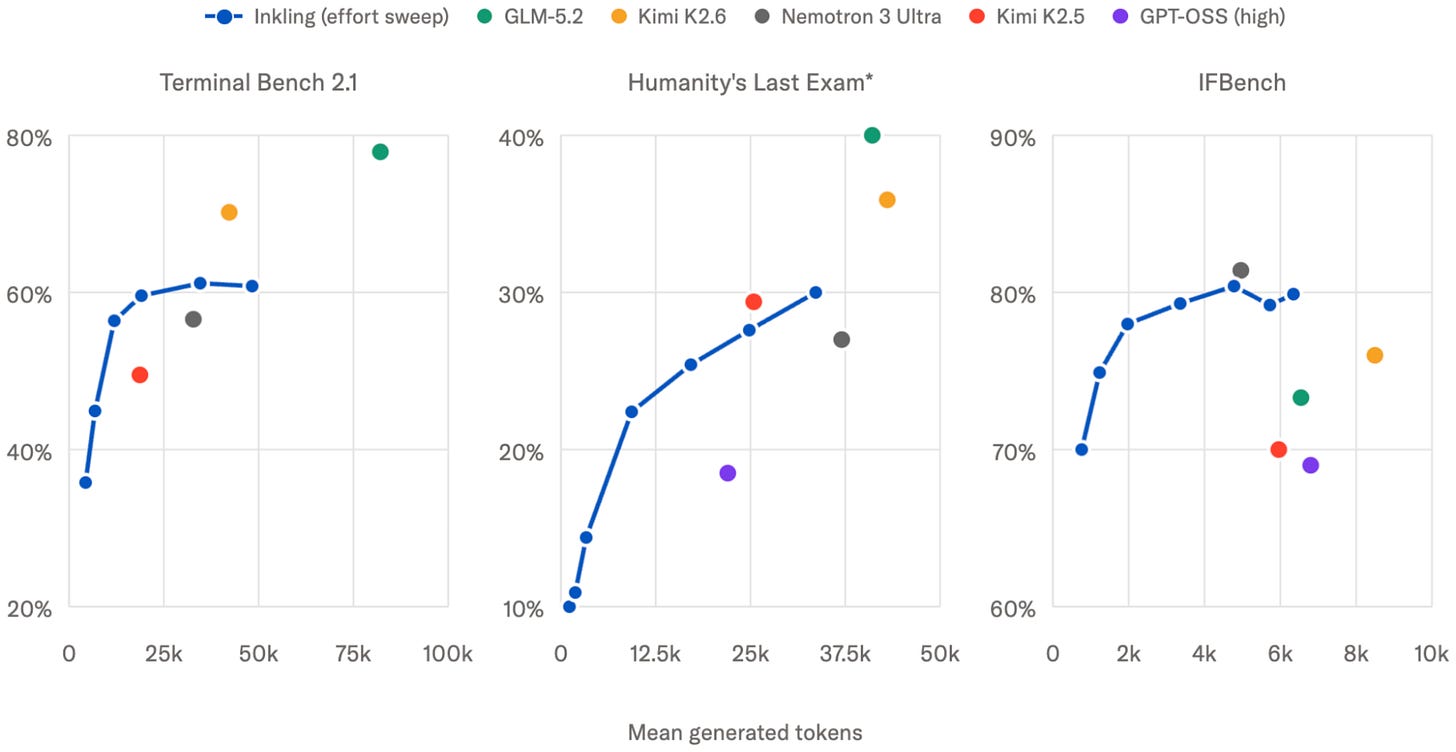
Figure 20: Increasing the Inkling effort level generally increases generated tokens and benchmark performance, with diminishing or uneven gains at higher effort. Figure from the Inkling announcement blog.
中文图注图 20:提高 Inkling 的推理强度通常会增加生成 token 数并提升基准性能,但在较高强度下,收益开始递减或表现不均衡。图源自 Inkling 发布博客。
As discussed in this section, during inference, the reasoning effort level can simply be controlled via a system prompt. (The ChatGPT UI presumably simply maps the menu choice to a system prompt.) However, this would not work for an arbitrary model and requires certain modifications to the training pipeline, which will be discussed next.
中文译文如本节所述,在推理阶段,推理强度可以仅通过 system prompt 控制;ChatGPT 界面很可能只是把菜单选项映射为相应的系统提示。但这种机制并不适用于任意模型,它要求训练流水线本身做出相应修改,下一节将讨论这一点。
5.2 Possible effort level implementations
中文5.2 推理强度等级的可能实现方式
While the training details are not public, neither for GPT 5.6 nor the open-source gpt-oss models, typically, the reasoning effort label is included in prompts during post-training.
中文译文无论 GPT-5.6 还是开源 gpt-oss,具体训练细节都未公开;但通常会在后训练(post-training)阶段把推理强度标签加入提示词。
There are typically two ways to implement this.
中文译文这类机制通常有两种实现路径。
First, we can implement it as part of the RLVR process and apply a different length penalty when different system prompts are used. For example, a high length penalty when “Reasoning effort: low” and a mild or no penalty when “Reasoning effort: high”.
中文译文第一,可以把它纳入 RLVR 过程,并在不同 system prompt 下采用不同的长度惩罚。例如,当提示为“Reasoning effort: low”时施加较强长度惩罚;当提示为“Reasoning effort: high”时,则使用较弱惩罚或不施加惩罚。
Second, we can fine-tune the model after RLVR to follow different effort instructions via supervised fine-tuning (SFT).
中文译文第二,可以在 RLVR 之后通过监督微调(SFT),使模型学会遵循不同的推理强度指令。
For instance, after the core RLVR stage and during SFT, the prompts in the training dataset are paired with target responses that exhibit the desired amount of reasoning. (The targets may be written by humans, generated by another model, or generated and then filtered.)
中文译文例如,在核心 RLVR 阶段完成后的 SFT 过程中,训练数据集中的提示词会与体现目标推理量的响应配对。(这些目标响应可以由人工撰写、由另一模型生成,或先生成后筛选。)
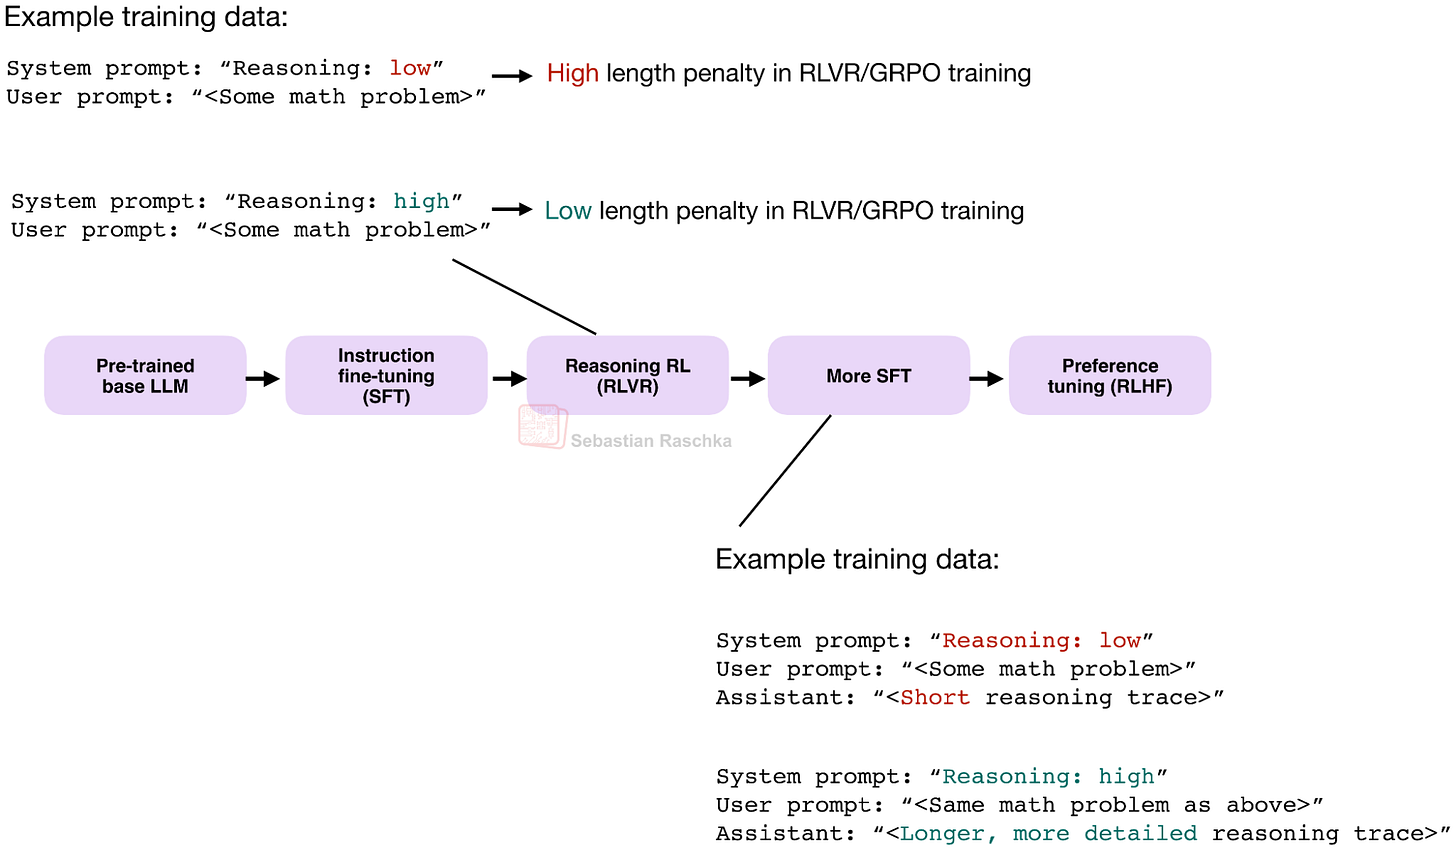
Figure 21: Illustration of effort-conditioned RLVR and SFT. (This is a possible implementation, not a confirmed description of OpenAI’s training pipeline.)
中文图注图 21:按推理强度条件化的 RLVR 与 SFT 示意图。(这只是可能的实现方式,并非对 OpenAI 训练流水线的确认性描述。)
During this SFT stage, the model learns the association between the effort label and the target reasoning length directly from the training examples. An RL-based implementation would instead place the effort labels and budget-aware reward inside the RLVR stage. The two approaches could also be combined, which I suspect was done for both gpt-oss and GPT 5.6 (note that effort settings in GPT 5.6 are likely just changing the system prompt for a given user query).
中文译文在这一 SFT 阶段,模型直接从训练样本中学习推理强度标签与目标推理长度之间的对应关系。基于 RL 的实现则会把强度标签与预算感知奖励放入 RLVR 阶段。两种方法也可以结合使用;我推测 gpt-oss 与 GPT-5.6 都采用了混合方案。需要注意的是,对于同一个用户查询,GPT-5.6 的不同强度设置很可能只是改变了 system prompt。
5.3 Inkling case study
中文5.3 Inkling 案例研究
The just-released Inkling technical report gives a small but somewhat concrete example of effort-level training.
中文译文刚刚发布的 Inkling 技术报告提供了一个规模不大、但相对具体的推理强度训练案例。
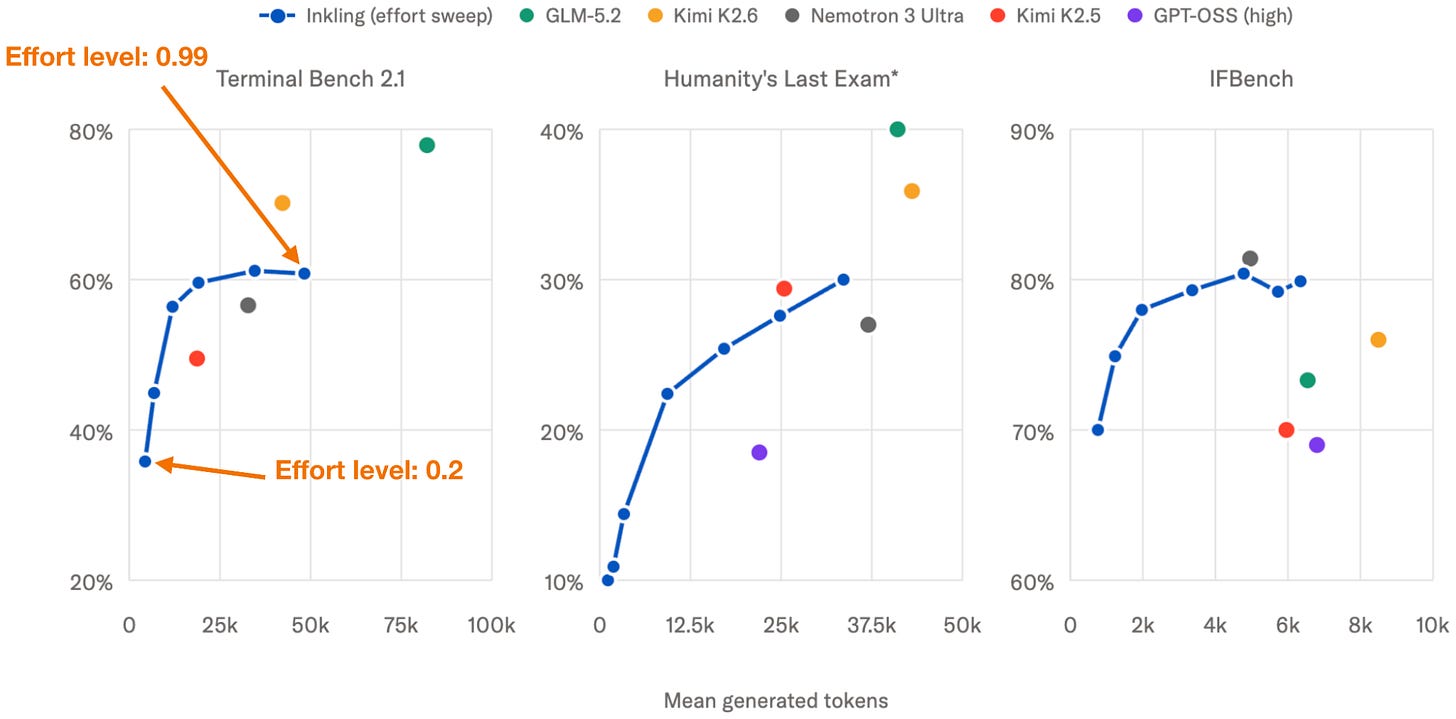
Figure 22: Inkling sweeps a continuous effort value between 0.2 and 0.99; higher effort generally produces longer responses and higher benchmark scores.
中文图注图 22:Inkling 在 0.2 到 0.99 之间扫描连续的推理强度值;更高强度通常会产生更长响应和更高基准得分。
During large-scale RL, they did two things for each sample:
中文译文在大规模 RL 期间,他们针对每个样本执行了两项操作:
-
Specified the desired effort level in the system message.
-
Adjusted the cost assigned to each generated token.
中文译文1. 在 system message 中指定目标推理强度。
2. 调整每个生成 token 对应的成本。
Conceptually, the reward likely looked something like this:
中文译文从概念上看,其奖励函数可能近似如下:
R(e) = Rtask − λ(e)Ntokens
中文译文`R(e) = R_task - λ(e) N_tokens`
Here, e is the requested effort level and λ(e) controls the token penalty.
中文译文其中,`e` 表示请求的推理强度,`λ(e)` 控制 token 惩罚系数。
-
Low effort uses a larger per-token cost, encouraging shorter reasoning traces.
-
High effort uses a smaller per-token cost, allowing the model to spend more tokens.
中文译文低强度采用更高的逐 token 成本,从而鼓励较短的推理轨迹。
高强度采用更低的逐 token 成本,使模型可以使用更多 token。
Then, at inference time, Inkling receives a system message such as Thinking effort level: 0.8, and adjusts its token usage accordingly. The difference between Inkling and models such as gpt-oss and GPT-5.6 is that the effort label i s a continuous number between 0 and 1 instead of ordinal labels such as low, medium, and high.
中文译文在推理阶段,Inkling 会接收类似 `Thinking effort level: 0.8` 的 system message,并相应调整 token 使用量。Inkling 与 gpt-oss、GPT-5.6 等模型的区别在于:它使用 0 到 1 之间的连续数值作为强度标签,而不是 low、medium、high 这样的序数档位。
This places Inkling’s effort-level conditioning primarily in the Reasoning RL stage, not only in the later SFT stage.
中文译文因此,Inkling 的推理强度条件化主要发生在 Reasoning RL 阶段,而不只是后续 SFT 阶段。
They do not disclose the exact reward formula, token-cost coefficients, or whether effort conditioning was also included in SFT, though.
中文译文不过,报告没有披露精确的奖励公式、token 成本系数,也未说明 SFT 中是否同样包含推理强度条件化。
5.4 A short note about inference scaling versus training scaling
中文5.4 推理扩展与训练扩展的简要说明
Before moving on to the reasoning effort papers, I want to briefly connect this section back to the earlier “2.3 Inference scaling in a nutshell” section.
中文译文在进入推理强度相关论文之前,先把本节内容与前文“2.3 推理扩展简述”重新联系起来。
Earlier, I separated scaling into training compute scaling and inference-time scaling. The GPT-5.6 interface provides a nice way to illustrate the difference, as shown below.
中文译文前文将扩展方式区分为训练计算扩展与推理阶段扩展。GPT-5.6 的界面恰好可以直观展示二者的差异,如下图所示。
On the left, selecting Luna, Terra, or Sol changes the model itself. As a rough analogy, this corresponds to training compute scaling. These are separate trained models. At a fixed training recipe and dataset size, a larger model requires more training compute. It also generally requires more compute per generated token.
中文译文左侧选择 Luna、Terra 或 Sol,会改变模型本身。粗略而言,这对应训练计算扩展:它们是分别训练得到的不同模型。在训练配方与数据集规模固定时,更大的模型需要更多训练计算,通常每生成一个 token 也需要更多计算。
On the right, we keep the model fixed and only change the reasoning effort. This is inference-time scaling. The model weights stay the same, but the model is allowed to spend fewer or more tokens working on the answer.
中文译文右侧则保持模型不变,只调整推理强度。这属于推理阶段扩展。模型权重保持不变,但允许模型使用更少或更多 token 来完成答案。
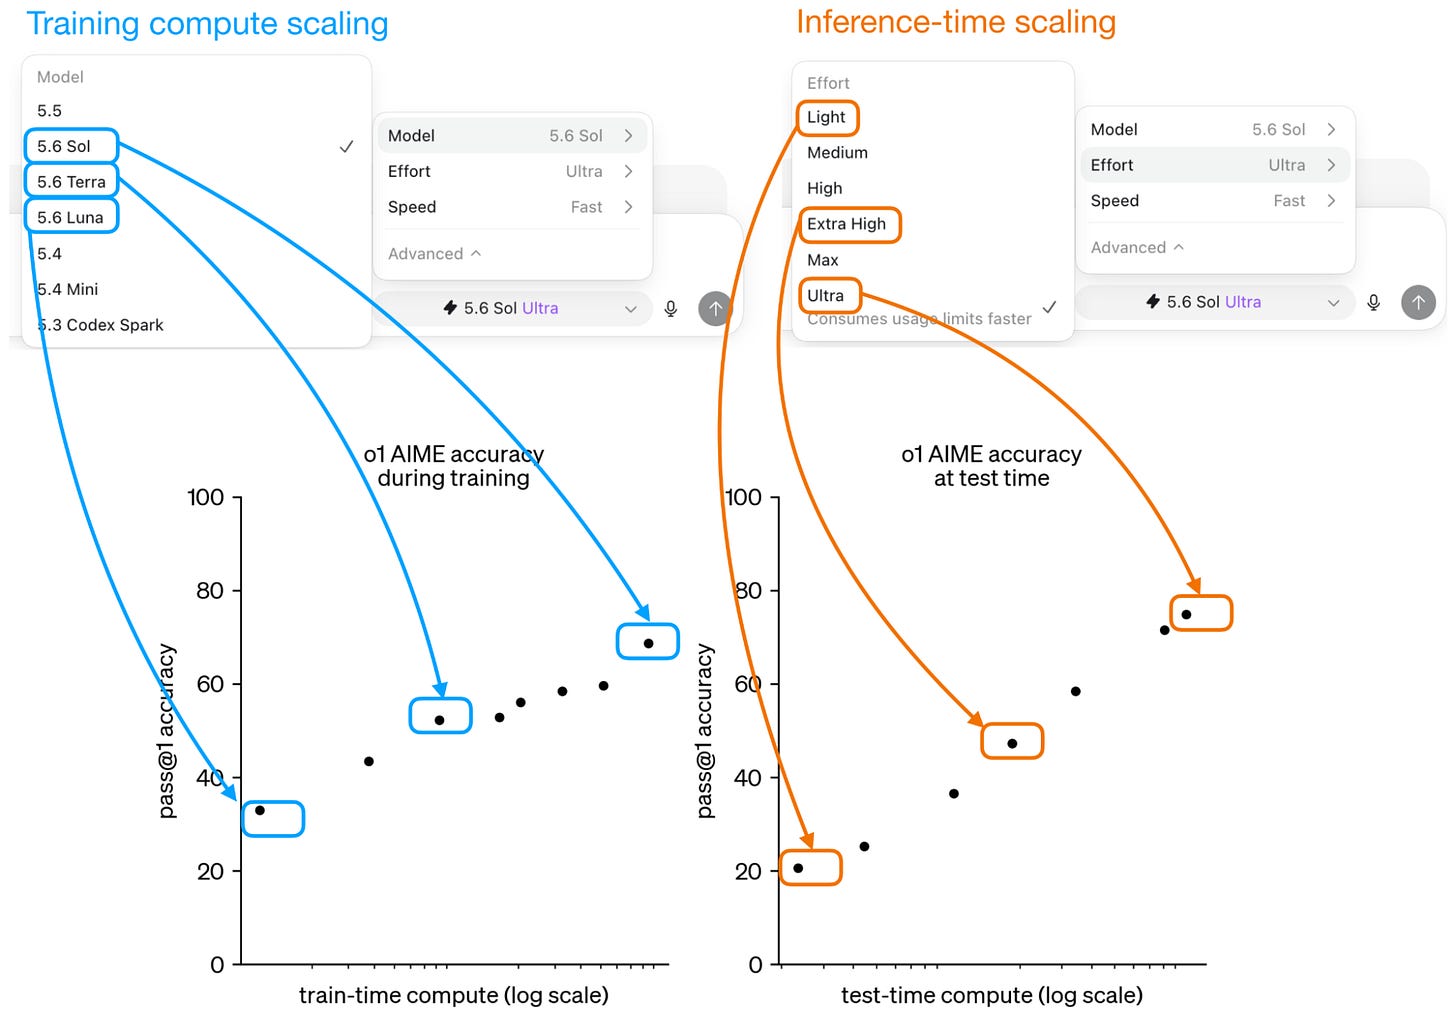
Figure 23: The model selection and reasoning effort menus correspond to two different scaling axes. Selecting Luna, Terra, or Sol changes the model, whereas changing the reasoning effort adjusts the inference-time compute for a fixed model.
中文图注图 23:模型选择与推理强度菜单对应两条不同的扩展轴。选择 Luna、Terra 或 Sol 会更换模型;调整推理强度,则会改变固定模型在推理阶段投入的计算量。
One small terminology caveat is that selecting a different model from the menu is not training scaling at that moment. The training has already happened. It is better to think of the model menu as selecting among models that were produced at different training scales.
中文译文需要补充一个术语上的限定:在菜单中切换模型的当下,并不是正在执行训练扩展,因为训练已经完成。更准确的理解是,模型菜单允许用户在由不同训练规模产生的模型之间进行选择。
The Artificial Analysis results below show how these two axes interact in practice.
中文译文下面的 Artificial Analysis 结果展示了这两个扩展维度在实践中的交互。
Each blue curve corresponds to one model, Luna, Terra, or Sol. Moving along a curve by increasing the reasoning effort is inference scaling. Moving from one model curve to another corresponds to model scaling, which I use here as a practical proxy for training scaling.
中文译文每条蓝色曲线对应一个模型:Luna、Terra 或 Sol。沿同一条曲线提高推理强度,属于推理扩展;从一条模型曲线切换到另一条,则对应模型扩展。本文将后者作为训练扩展的实践代理指标。
As expected, both approaches can improve the benchmark score, but they also increase the cost. More interestingly, the curves overlap. For instance, a smaller model at a higher reasoning effort can sometimes reach a similar score as a larger model at a lower reasoning effort.
中文译文符合预期的是,两种方法都能提高基准得分,但也都会增加成本。更值得注意的是,各条曲线存在重叠:较小模型配合更高推理强度,有时可以达到与较大型语言模型配合较低推理强度相近的得分。
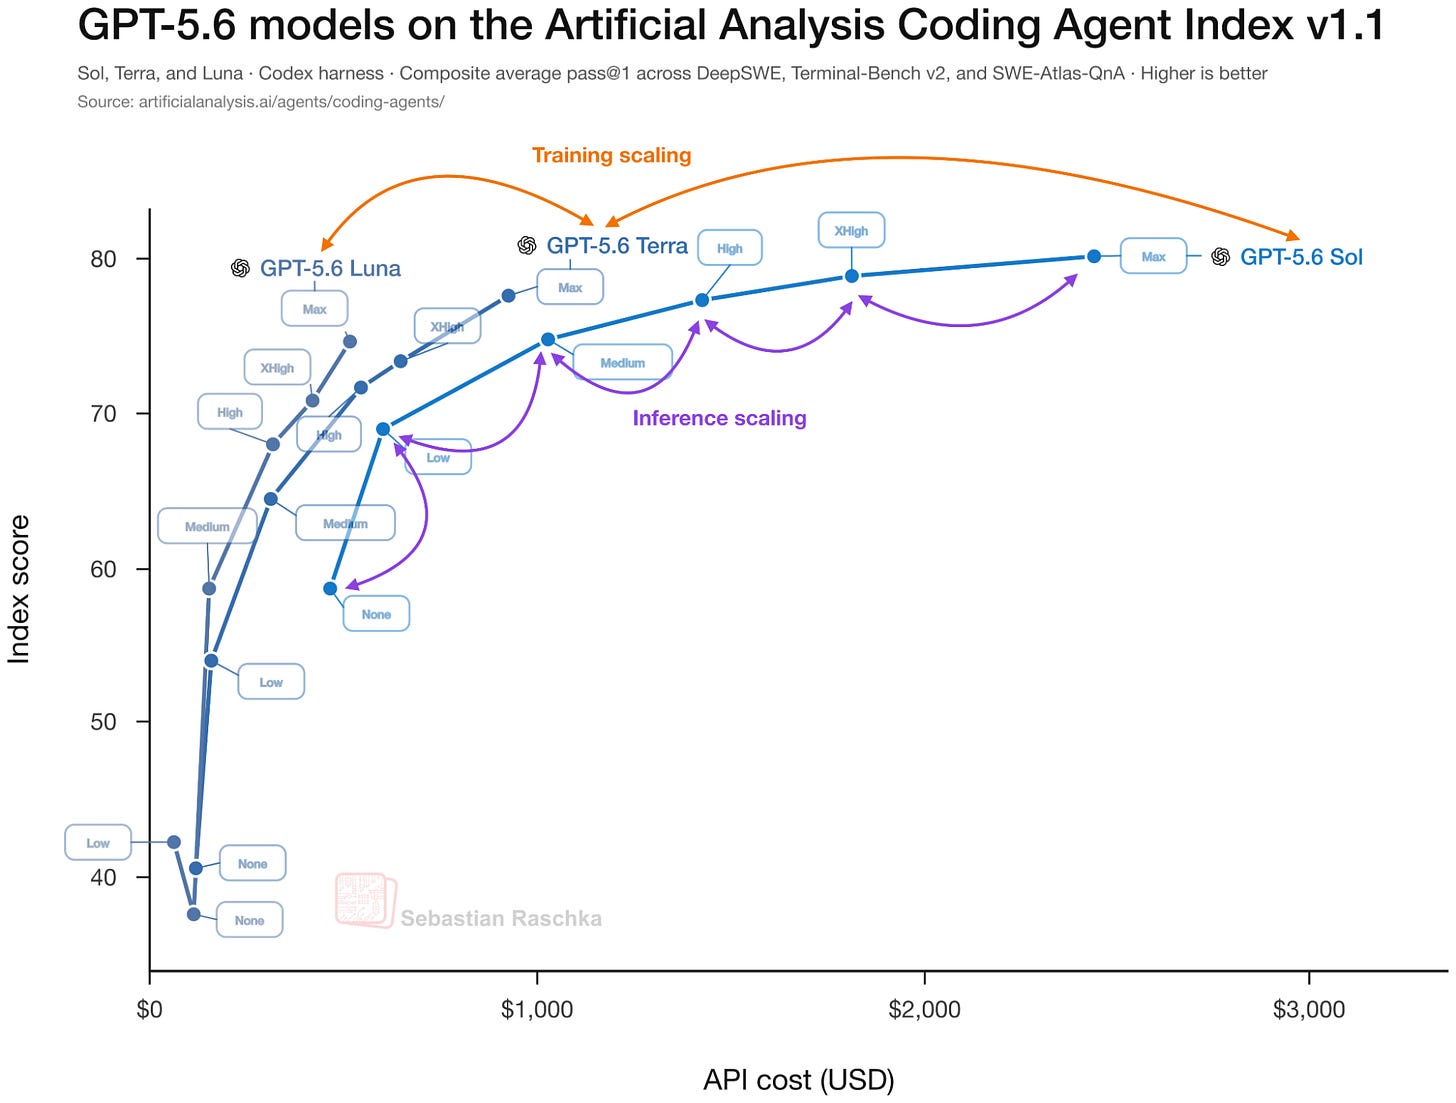
Figure 24: Training scaling and inference scaling for the GPT-5.6 model family on the Artificial Analysis Coding Agent Index. Moving along each model curve corresponds to increasing the reasoning effort. Moving across the Luna, Terra, and Sol curves corresponds to selecting a different model.
中文图注图 24:GPT-5.6 模型家族在 Artificial Analysis Coding Agent Index 上的训练扩展与推理扩展。沿每条模型曲线移动表示提高推理强度;在 Luna、Terra、Sol 三条曲线之间切换,则表示选择不同模型。
By the way, the x-axis in this figure shows API cost rather than raw compute. The API cost is a useful practical measure, but it also depends on the provider’s pricing and the number of generated tokens. Also, the exact shape of these curves is benchmark-specific.
中文译文该图横轴表示 API 成本,而非原始计算量。API 成本具有较强实践意义,但同时取决于服务商定价和生成 token 数;此外,曲线的具体形状也会随基准测试而变化。
So, the model size and reasoning effort form two separate knobs. We can use a larger model, increase the reasoning effort, or combine both. Which combination is best depends on the desired accuracy, cost, and latency.
中文译文因此,模型规模与推理强度是两个相互独立的控制变量。可以选择更大型语言模型、提高推理强度,或同时采用两者;最佳组合取决于目标准确率、成本与延迟。
So far, the article should give you a pretty solid understanding of how reasoning effort modes work and how they are implemented. This is a fine point to wrap the article if you are short on time. Otherwise, if you want to look into some of the nitty-gritty details of some of the recent open-weight models, please read on!
中文译文至此,本文已经足以建立对推理强度模式及其实现方式的较完整理解。时间有限的读者可以在此结束;希望进一步了解近期开放权重模型实现细节的读者,可继续阅读后续内容。
6. Bonus: Different ways to implement reasoning efforts (in flagship open-weight LLMs)
中文6. 补充:旗舰开放权重 LLM 实现推理强度的不同方式
[This section is fine to skip unless you are interested in some additional details]
中文译文[除非对更多实现细节感兴趣,否则可以跳过本节。]
Section 5 described two possible ways to train reasoning-effort controls, namely effort-condit ioned supervised fine-tuning and reinforcement learning with different token costs. Originally, I wanted to cover research articles on alternative ways to implement reasoning budgets. However, reading through most of these articles, they seemed more like proofs-of-concept that may or may not work well in practice.
中文译文第 5 节介绍了训练推理强度控制的两种可能方式:按强度条件化的监督微调,以及采用不同 token 成本的强化学习。我原本计划介绍一些实现推理预算的替代研究方案,但通读相关论文后发现,其中许多更接近概念验证,实际效果未必稳定。
So, instead of covering those, I decided to pivot a bit and cover those recipes used by state-of-the-art and notable open-weight (flagship) LLMs. For these models, there is at least evidence that the methods work in practice.
中文译文因此,本文改为考察当前先进且具有代表性的旗舰开放权重 LLM 所采用的训练配方。至少已有实际结果表明,这些方法能够有效运行。
This leaves six examples. DeepSeek V4, Nemotron 3 Ultra, Kimi K2.5, GLM-5, Qwen3, and Inkling. They have different levels of detail in their reporting, but each contributes a useful variation. (I exclude models whose reports only show an effort setting in the user interface without explaining how that behavior was trained.)
中文译文最终纳入六个案例:DeepSeek V4、Nemotron 3 Ultra、Kimi K2.5、GLM-5、Qwen3 与 Inkling。各报告披露细节的程度不同,但每个案例都提供了一种有价值的变体。(仅在用户界面展示强度设置、却未说明该行为如何训练得到的模型,不纳入讨论。)
6.1 DeepSeek V4 trains separate effort specialists
中文6.1 DeepSeek V4 训练独立的推理强度专家
Let’s start with the DeepSeek V4 technical report, which describes the use of three modes:
中文译文先看 DeepSeek V4 技术报告。该报告描述了三种模式:
-
Non-think produces a direct response without a reasoning trace.
-
Think High is the classic approach where the model places the reasoning trace between
and tags. This is similar to what was discussed in the DeepSeek R1 section (section 2) at the beginning of this article. -
Think Max is the same as above but adds a special system instruction. (More on that below.)
中文译文**Non-think**:直接生成响应,不输出推理轨迹。
**Think High**:经典推理方式,模型将推理轨迹置于 `
**Think Max**:基本形式与 Think High 相同,但额外加入一条特殊 system instruction,后文会进一步说明。
The additional system prompt instruction for Think Max starts with “Reasoning Effort: Absolute maximum with no shortcuts permitted.”
中文译文Think Max 的附加 system prompt 以“Reasoning Effort: Absolute maximum with no shortcuts permitted.”开头。
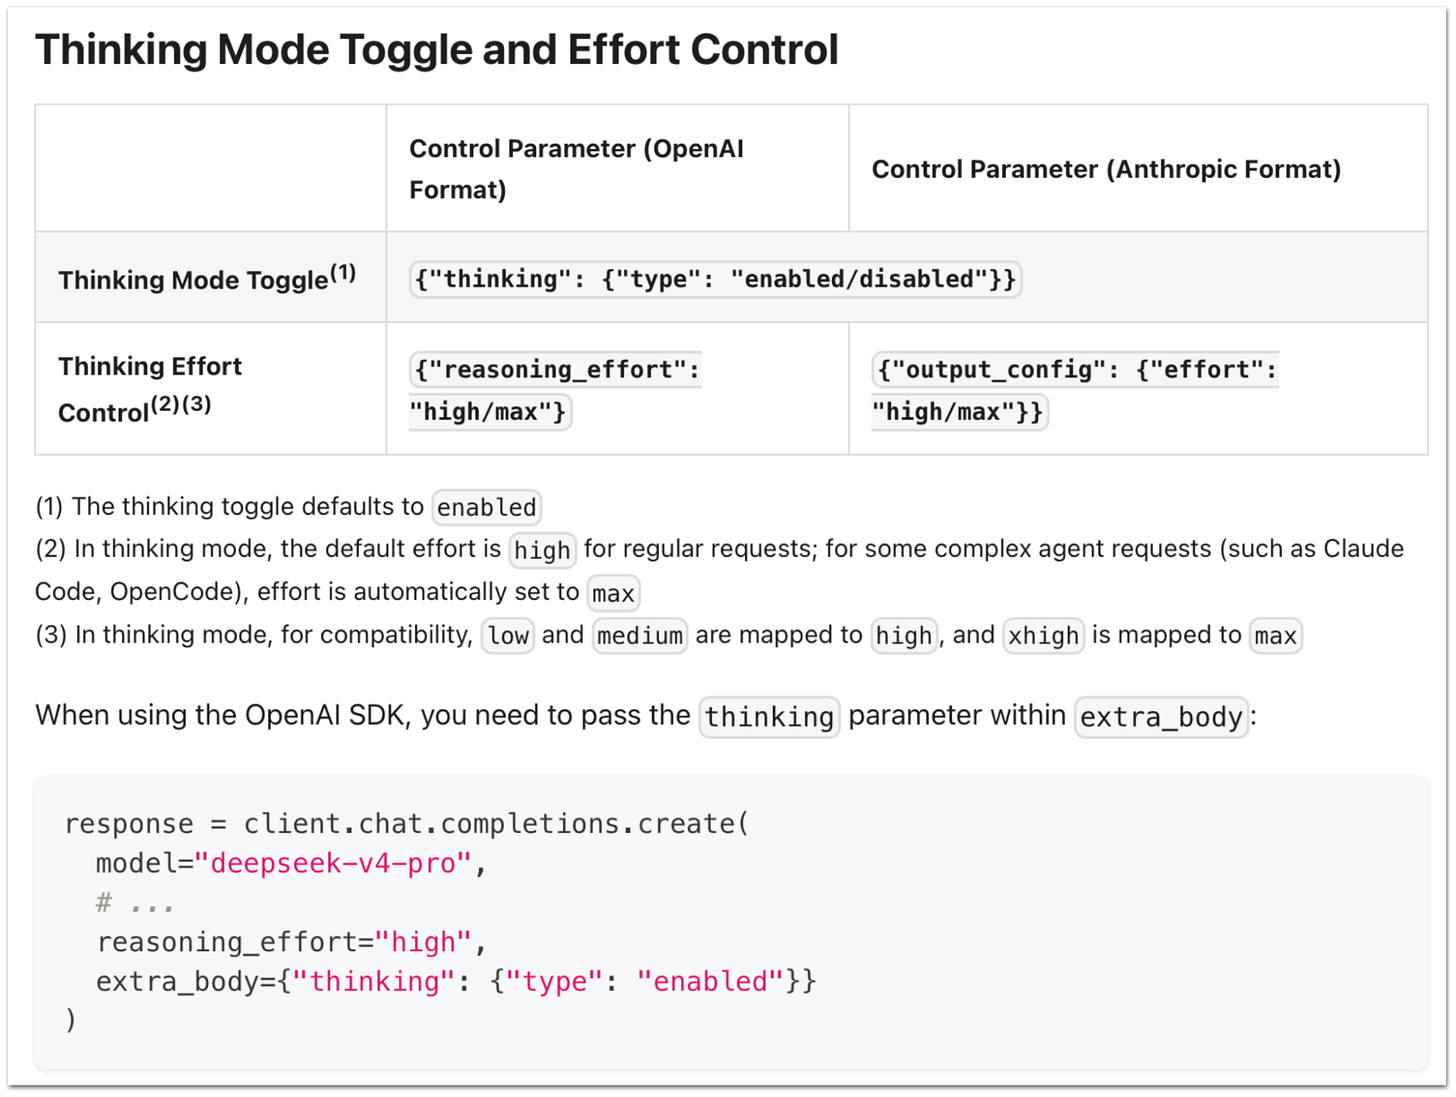
Figure 25: Reasoning effort control overview from the DeepSeek V4 documentation
中文图注图 25:DeepSeek V4 文档中的推理强度控制概览。
At first, this sounds like a simple prompt engineering trick, but this prompt is actually backed by a different training setup. That is, each mode uses its own context window and length penalty (unfortunately, the exact length penalty implementation is not detailed in this report). Think Max receives a longer context window and a smaller length penalty than Think High, which gives it more room to continue reasoning.
中文译文初看之下,这似乎只是提示工程技巧;但该提示实际上对应不同的训练配置。每种模式都有独立的上下文窗口和长度惩罚(遗憾的是,报告没有说明长度惩罚的具体实现)。Think Max 的上下文窗口更长、长度惩罚更小,因此能够进行更长时间的推理。
So, the system instruction selects a behavior that was created during post-training. Adding the same instruction to an arbitrary model would not have the same effect.
中文译文因此,system instruction 选择的是在后训练阶段形成的特定行为。把同一条指令加入任意模型,并不会产生相同效果。
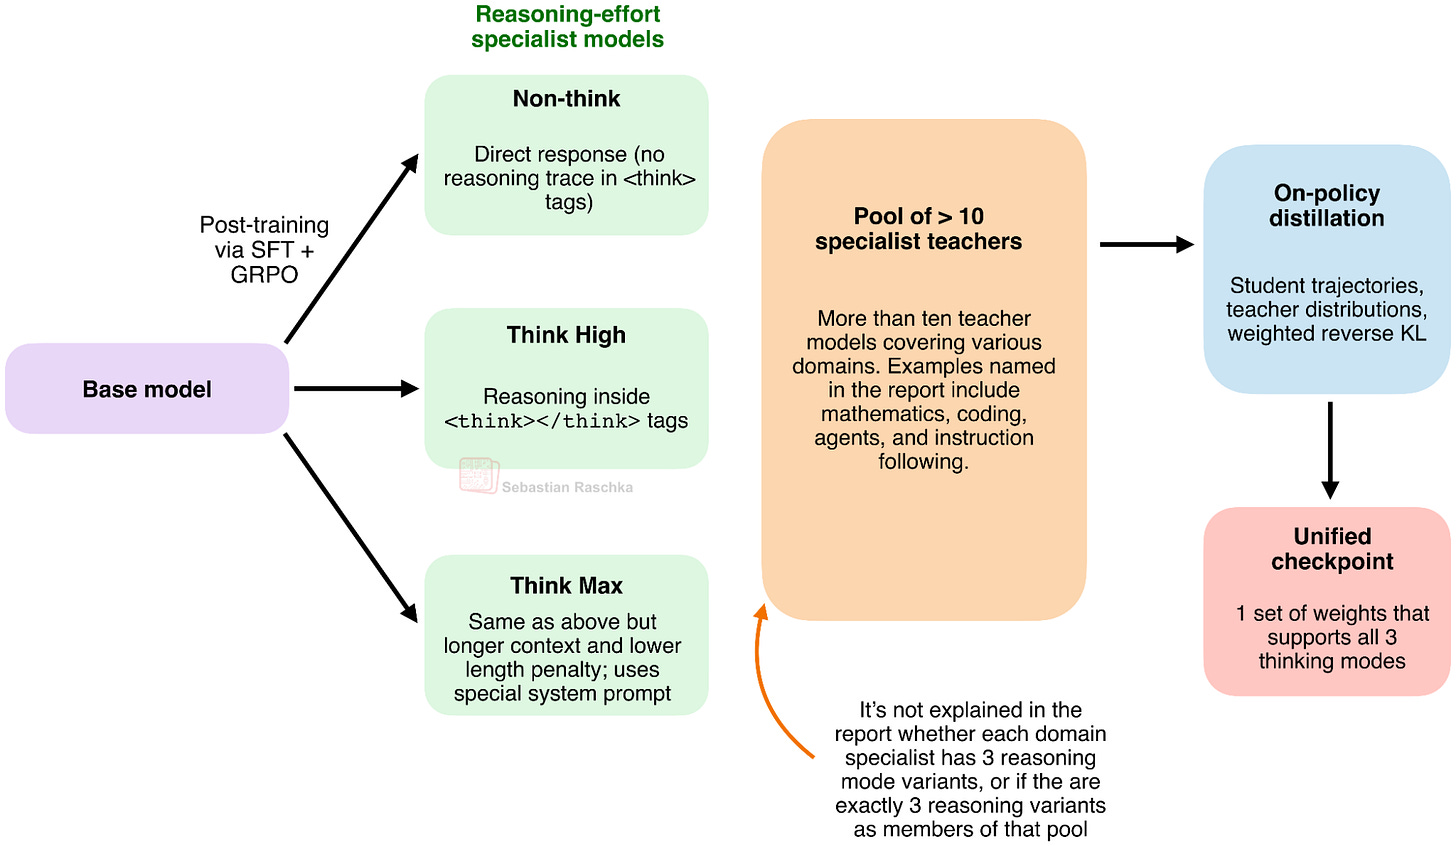
Figure 26: DeepSeek V4 describes the three effort modes and the larger teacher pool in separate parts of the report. The teacher pool contains more than ten domain specialists. The report does not disclose how these teachers map to Non-think, Think High, and Think Max.
中文图注图 26:DeepSeek V4 报告在不同位置分别描述了三种推理强度模式与更大的教师模型池。教师池包含十余个领域专家,但报告未披露这些教师如何映射到 Non-think、Think High 与 Think Max。
Unfortunately, the public, and otherwise very detailed DeepSeek V4 report does not connect the descriptions of the reasoning mode and domain specialists in enough detail to reconstruct the exact teacher assignment.
中文译文遗憾的是,DeepSeek V4 的公开报告虽然整体非常详尽,但没有充分关联推理模式与领域专家的描述,因此无法重建精确的教师分配方案。
However, the report states that the final model, which supports different reasoning effort levels, was created via on-policy distillation from said teachers.
中文译文不过,报告明确指出,最终支持多档推理强度的模型,是通过对上述教师实施 on-policy distillation 得到的。
To summarize, DeepSeek V4 develops the three reasoning specialists during post-training. Starting from the base model, it applies supervised fine-tuning followed by RLVR via GRPO. The RL configuration differs for each mode. In particular, each specialist uses its own context window and length penalty, while Think Max additionally receives a special system instruction.
中文译文概括而言,DeepSeek V4 在后训练阶段开发三类推理专家。从基础模型出发,先进行监督微调,再使用 GRPO 执行 RLVR。不同模式采用不同的 RL 配置:每个专家都有自己的上下文窗口与长度惩罚,而 Think Max 还会接收一条特殊 system instruction。
Then, including domain specialists, the different reasoning mode specialists are distilled into a single checkpoint that supports all three effort modes.
中文译文随后,包括领域专家在内的不同推理模式专家被蒸馏到单一检查点中,使最终模型能够支持全部三档推理强度。
6.2 Nemotron 3 Ultra combines learned modes with hard budgets
中文6.2 Nemotron 3 Ultra 将学习得到的模式与硬预算结合
The Nemotron 3 Ultra technical report describes three settings called reasoning-off, regular, and medium-effort, analogous to DeepSeek V4 in the previous section. Medium-effort is the cheaper reasoning mode compared with regular. NVIDIA introduces this mode during SFT using examples generated by GPT-OSS-120B in its medium-effort mode, and then further optimizes it during RLVR. About 2.5% of the RLVR prompts use medium-effort (this corresponds to length-based adjustments applied to their rewards).
中文译文Nemotron 3 Ultra 技术报告描述了 reasoning-off、regular 与 medium-effort 三种设置,与上一节的 DeepSeek V4 类似。medium-effort 相比 regular 是成本更低的推理模式。NVIDIA 在 SFT 阶段使用 GPT-OSS-120B 的 medium-effort 模式生成样本,以引入该行为;随后再通过 RLVR 进一步优化。约 2.5% 的 RLVR 提示词采用 medium-effort,这对应于对奖励施加基于长度的调整。
6.2.1 Using Nemotron reasoning budgets during inference
中文6.2.1 推理阶段如何使用 Nemotron 的推理预算
At inference time, all three modes are selected through the chat template.
中文译文在推理阶段,三种模式均通过 chat template 进行选择。
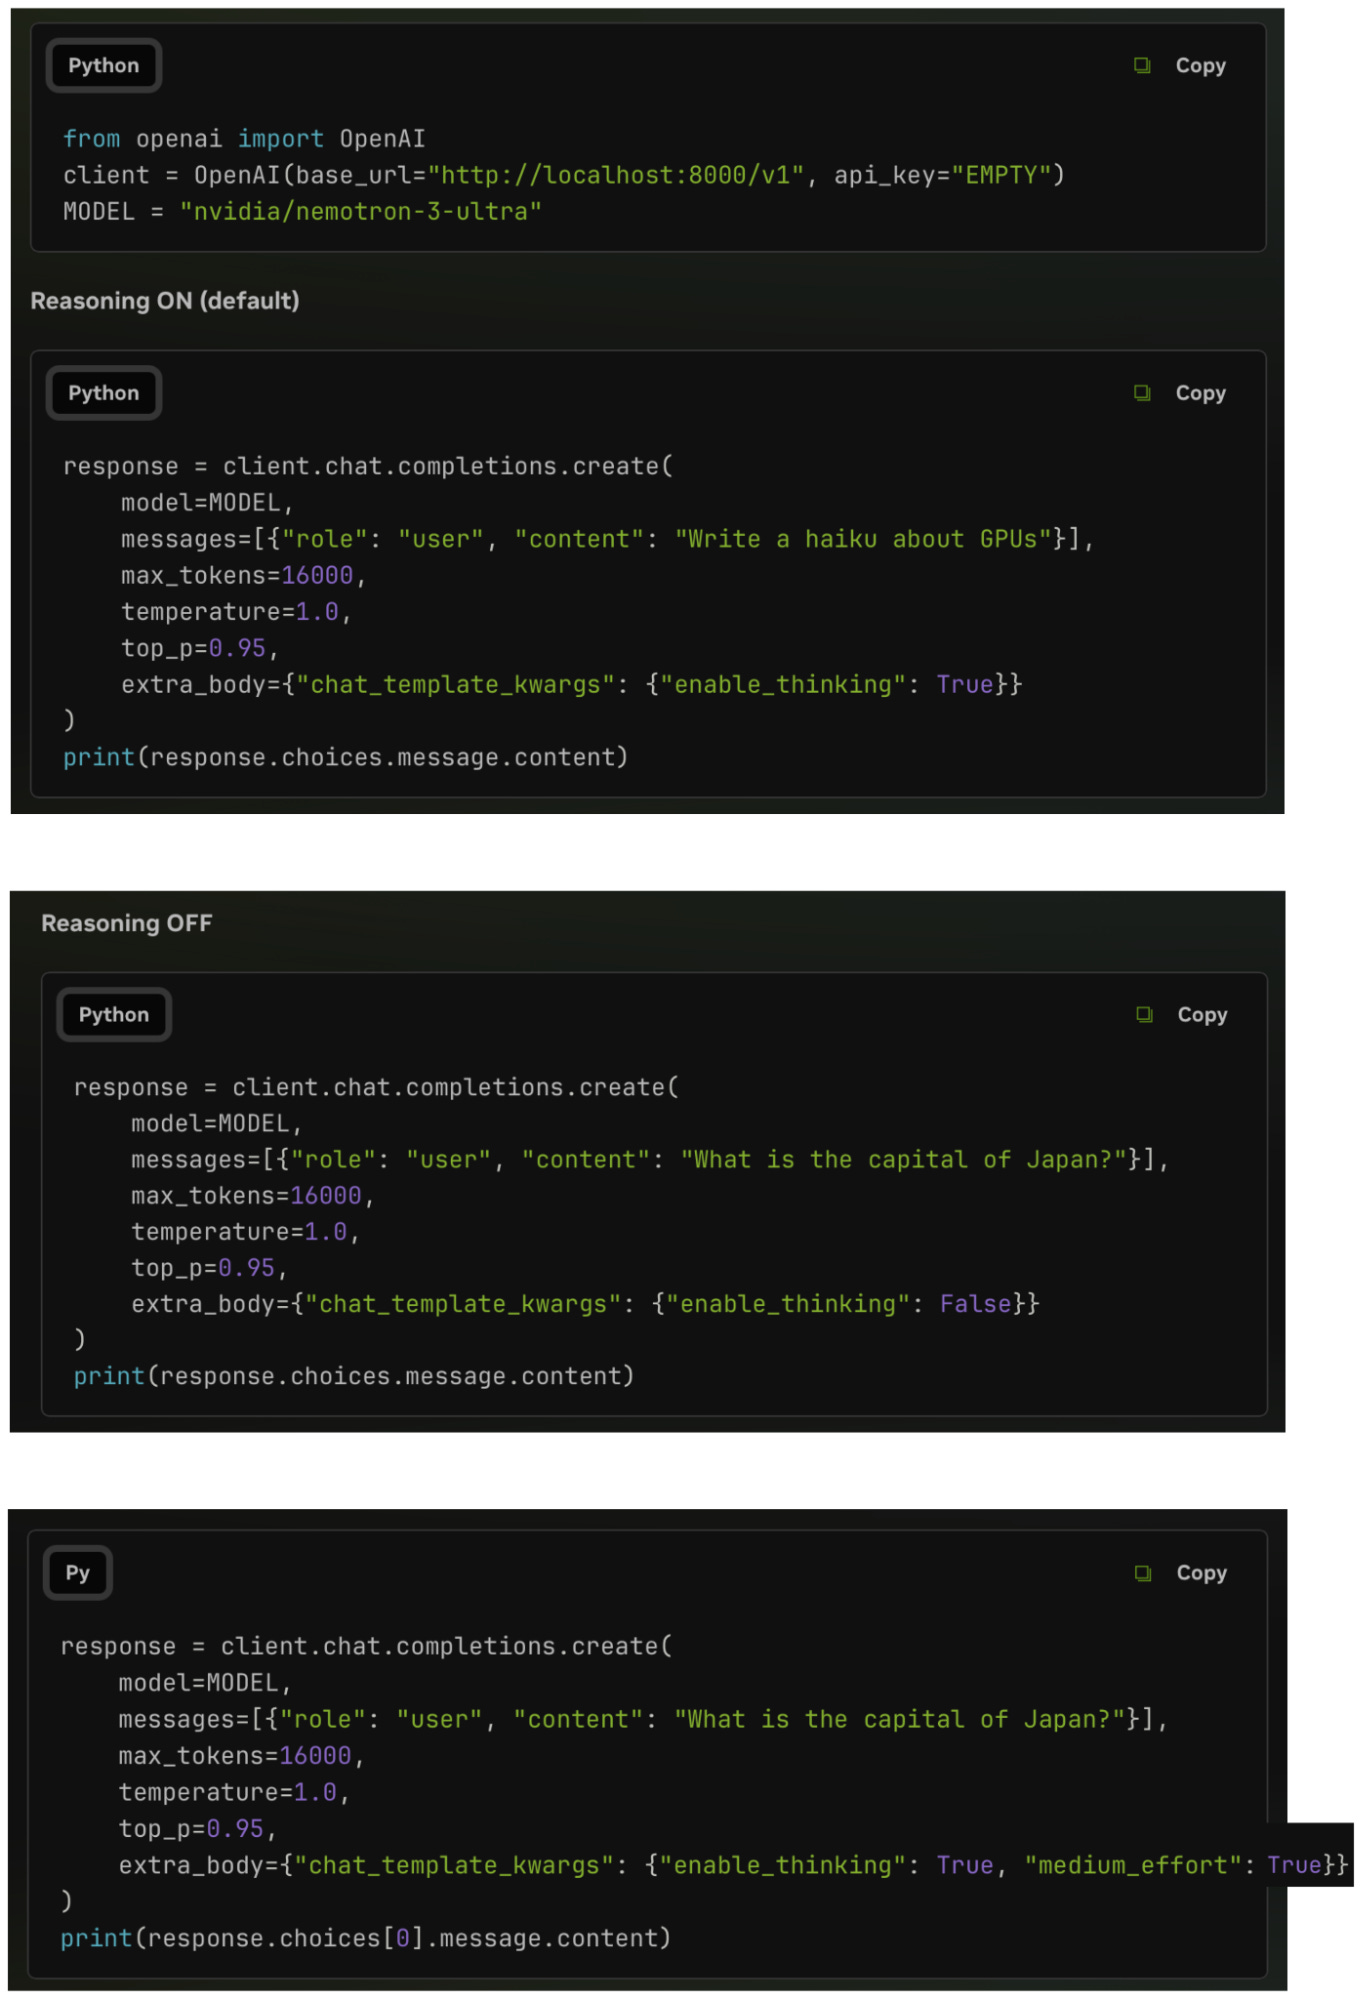
Figure 27: Nemotron 3 Ultra reasoning settings via the chat template (examples from the official model card)
中文图注图 27:通过 chat template 配置 Nemotron 3 Ultra 的推理设置。(示例取自官方 model card。)
- Regular is the default and uses
enable_thinking=True, which starts the assistant response with an opening<think>tag.
中文译文1)**Regular** 为默认模式,使用 `enable_thinking=True`,在 assistant 响应开头加入起始标签 `
- Medium-effort uses
enable_thinking=Truetogether withmedium_effort=Truewhere the latter setting also appends {reasoning effort: efficient} to the latest user message.
中文译文2)**Medium-effort** 同时使用 `enable_thinking=True` 与 `medium_effort=True`;后一个设置还会在最近一条用户消息后附加 `{reasoning effort: efficient}`。
By the way, to further complicate things, the regular and medium-effort modes can also be combined with a separate inference-time reasoning budget. This budget acts as an external stopping mechanism. In the released implementation, the chat client asks the model to end the reasoning trace near the chosen token limit. If the model has not emitted </think>, the client closes the reasoning block and continues generation to produce the final answer. The learned effort mode determines how the model uses its reasoning tokens, while the budget constrains how long the reasoning trace can continue. This makes it possible to pair either mode with a tighter or looser budget depending on the desired cost and accuracy.
中文译文此外,regular 与 medium-effort 模式还可以叠加一个独立的推理阶段 token 预算,使机制进一步复杂化。该预算充当外部停止条件:在已发布实现中,chat client 会要求模型在接近指定 token 上限时结束推理轨迹;如果模型尚未生成 ``,client 会主动闭合推理区段,再继续生成最终答案。学习得到的强度模式决定模型如何使用推理 token,而预算则限制推理轨迹能够持续多长时间。因此,可根据目标成本与准确率,为任一模式配置更紧或更宽松的预算。
- Reasoning-off uses
enable_thinking=False, which prefills an empty<think></think>block (similar to Qwen3 discussed in section 4) so that the model proceeds directly to the final response. Thus, these are chat-template controls rather than system prompts.
中文译文3)**Reasoning-off** 使用 `enable_thinking=False`,预填一个空的 `
6.2.2 Reasoning budget-aware training in Nemotron
中文6.2.2 Nemotron 中的推理预算感知训练
The inference controls described above are backed by two related SFT components. The first introduces medium-effort behavior using GPT-OSS-120B traces, as discussed earlier. The second prepares the model for hard reasoning budgets.
中文译文上述推理控制由两个相互关联的 SFT 组件支撑。第一个组件使用 GPT-OSS-120B 的推理轨迹引入 medium-effort 行为;第二个组件则使模型适应硬性推理预算。
To construct this training data, the authors take regular reasoning traces, truncate them at randomly selected token budgets, and keep the original final answers. The inserted </think> token is masked from the SFT loss. As a result, the model sees examples where it has to move from an incomplete reasoning trace to the answer after the reasoning block has been closed externally.
中文译文为构造此类训练数据,作者从常规推理轨迹出发,按照随机选取的 token 预算截断轨迹,同时保留原始最终答案。插入的 `` token 不计入 SFT loss。由此,模型会接触这样的训练样本:推理轨迹尚未完成时,推理区段被外部强制闭合,模型需要直接从不完整轨迹过渡到最终答案。
Medium-effort training then continues during RLVR. About 2.5% of the RL prompts use the medium-effort setting across math, STEM, and coding tasks. The report notes that the mode can be calibrated through reward hyperparameters where length-based reward adjustments provide additional control over the cost-quality trade-off.
中文译文medium-effort 训练随后在 RLVR 阶段继续进行。数学、STEM 与编码任务中,约 2.5% 的 RL 提示词采用 medium-effort 设置。报告指出,可通过奖励超参数校准该模式,其中基于长度的奖励调整能够进一步控制成本—质量权衡。
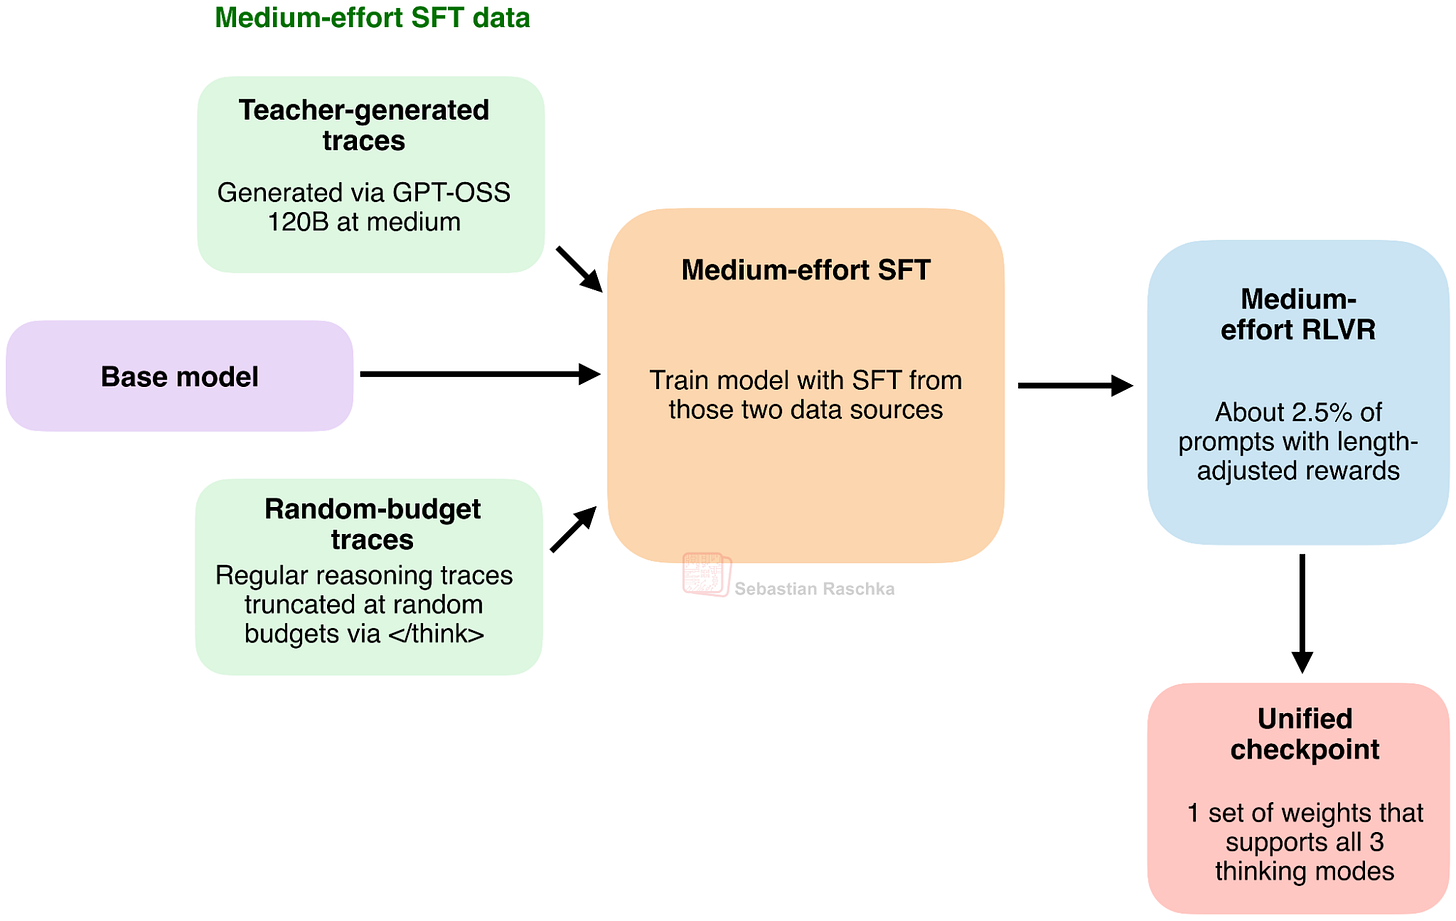
Figure 28: Nemotron 3 Ultra introduces medium effort with teacher-generated SFT data, random-budget truncation, and a small medium-effort subset during RLVR.
中文图注图 28:Nemotron 3 Ultra 通过教师生成的 SFT 数据、随机预算截断,以及 RLVR 中占比较小的 medium-effort 子集,引入中等推理强度。
6.3 Kimi K2.5 alternates budgeted and unconstrained RL
中文6.3 Kimi K2.5 在有预算与无预算 RL 之间交替训练
The Kimi K2.5 technical report discusses a training method called Token Efficient RL for lower reasoning effort. (While there was a K3 announcement this week, the reasoning-effort methodology of K3 is not publicly disclosed, but it could be similar or related to K2.5.)
中文译文Kimi K2.5 技术报告讨论了一种名为 Token Efficient RL 的训练方法,用于降低推理强度。(本周虽已发布 K3,但 K3 的推理强度方法尚未公开;它可能与 K2.5 相同或相关。)
6.3.1 Kimi’s Toggle method
中文6.3.1 Kimi 的 Toggle 方法
The report mentions that a fixed token budget can make a reasoning model overfit to short solutions. That means the model becomes more concise (i.e., faster and cheaper), but it may lose the ability to benefit from additional inference-time compute and can thus perform poorly.
中文译文报告指出,固定 token 预算可能使推理模型对短解法产生过拟合。模型虽然会变得更简洁,即速度更快、成本更低,但可能失去从额外推理阶段计算中获益的能力,因而出现性能下降。
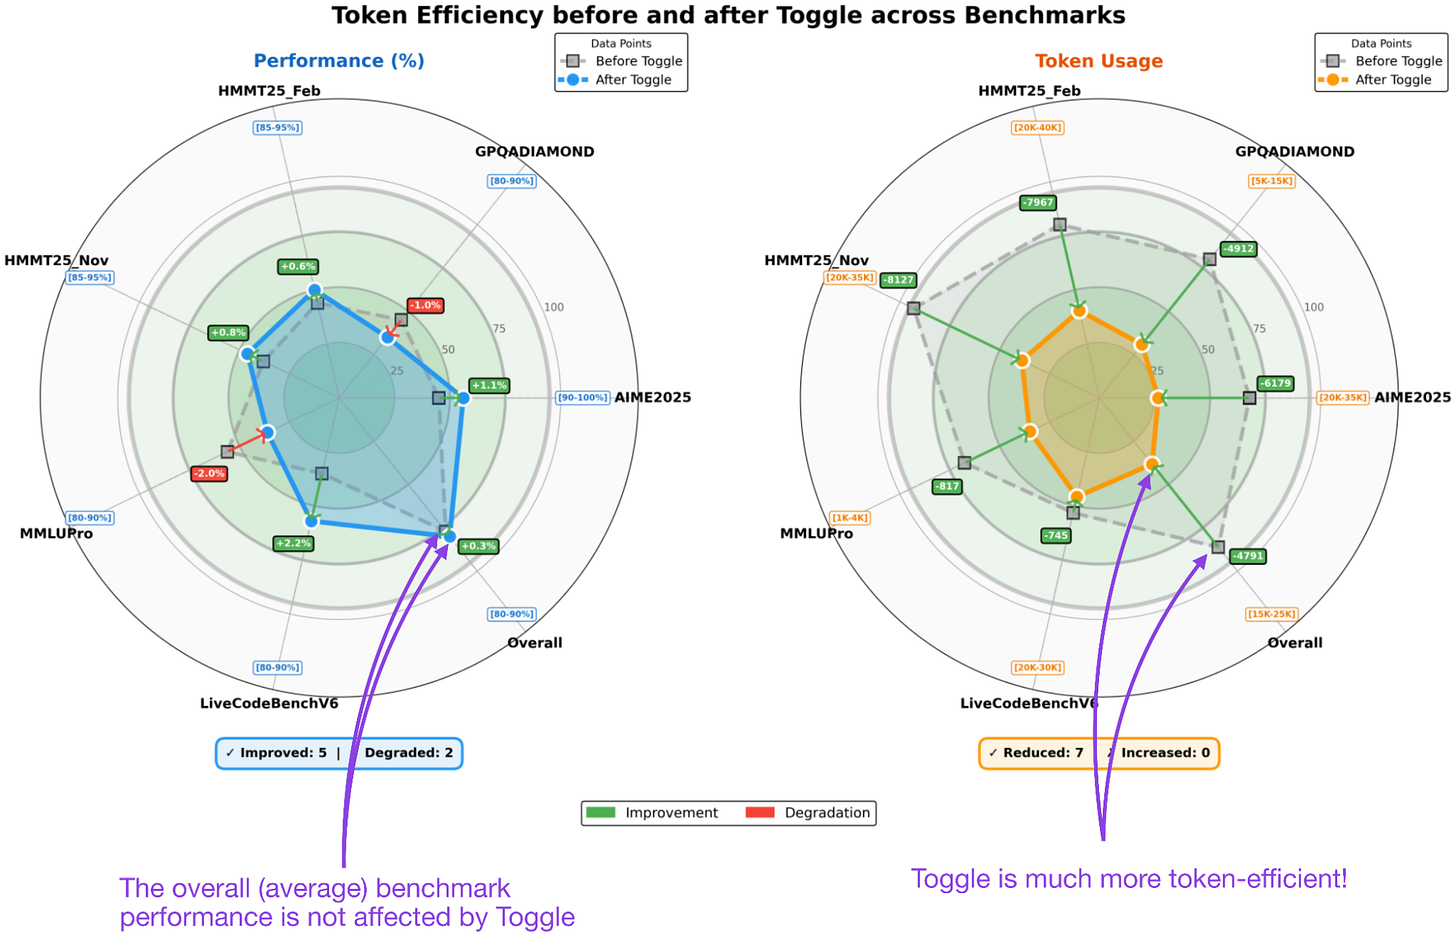
Figure 29: The proposed Toggle method makes Kimi K2.5 much more token-efficient while keeping the overall benchmark performance similar. Annotated figure from https://arxiv.org/abs/2602.02276
中文图注图 29:所提出的 Toggle 方法显著提高 Kimi K2.5 的 token 效率,同时整体基准性能基本不变。标注图取自 arXiv:2602.02276。
Kimi K2.5’s method, called Toggle, alternates between two RL phases every fixed number of training iterations:
中文译文Kimi K2.5 的方法称为 Toggle:每经过固定数量的训练迭代,就在两个 RL 阶段之间切换:
1. In the budgeted phase, correct solutions are encouraged to stay within a problem-specific token budget.
中文译文1. 在有预算阶段(budgeted phase),鼓励正确解答控制在针对该问题设定的 token 预算以内。
2. In the unconstrained phase, the usual maximum generation length is restored so that the model can still learn from longer solutions.
中文译文2. 在无约束阶段(unconstrained phase),恢复通常的最大生成长度,使模型仍能从较长解答中学习。
For each problem, the budget is estimated from a selected percentile of response lengths among correct rollouts in RLVR. The budget constraint is then only activated once the mean accuracy on that problem exceeds a threshold. This avoids forcing the model to shorten its reasoning before it can solve the problem reliably.
中文译文对于每个问题,预算根据 RLVR 正确 rollout 的响应长度分布,从选定百分位数估计得到。只有当该问题的平均准确率超过阈值后,预算约束才会启用,从而避免模型在尚不能稳定求解问题时,就被迫缩短推理过程。
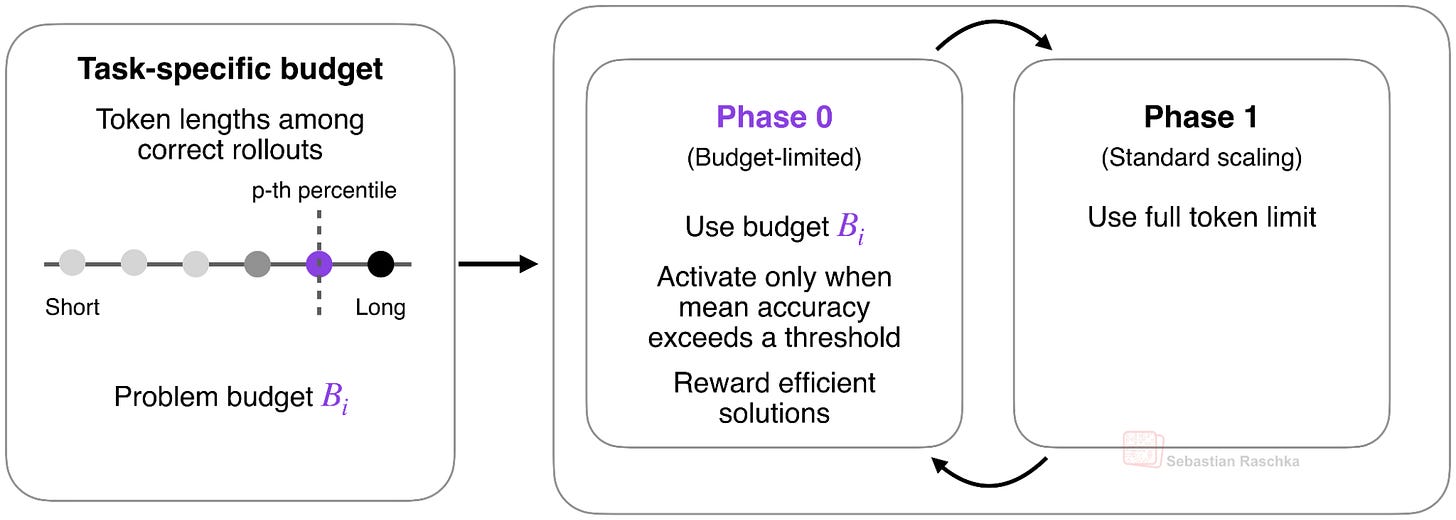
Figure 30: Overview of the two phases of the Toggle method.
中文图注图 30:Toggle 方法两个阶段的概览。
The report evaluates Toggle on K2 Thinking and finds that it reduces generated tokens by about 25 to 30% with little change in benchmark performance. The same behavior also transfers from math and coding RL tasks to GPQA and MMLU-Pro.
中文译文报告在 K2 Thinking 上评估 Toggle,发现其可将生成 token 数减少约 25%–30%,而基准性能变化很小。该行为还能从数学与编码 RL 任务迁移到 GPQA 和 MMLU-Pro。
Toggle supplies a concrete flagship-model recipe for training a more token-efficient reasoning policy while preserving its ability to scale at test time.
中文译文Toggle 提供了一套已用于旗舰模型的具体训练方案:在保持测试时扩展能力的同时,训练出 token 效率更高的推理策略。
6.3.2 What Toggle changes at inference
中文6.3.2 Toggle 在推理阶段改变了什么
Toggle operates entirely during RL training. Both alternating phases update the same policy (i.e., LLM), and the final (unified) checkpoint has no budgeted-versus-unconstrained selector. At inference, the resulting model then runs in thinking mode by default.
中文译文Toggle 完全作用于 RL 训练期间。两个交替阶段更新的是同一个策略,即同一个 LLM;最终统一检查点不存在“有预算/无约束”选择器。推理时,所得模型默认以 thinking mode 运行。
Interestingly, though, Kimi K2.5 itself exposes a separate binary choice between thinking and instant modes in some APIs I checked (like vLLM or SGLang). Thinking mode is enabled by default. Instant mode disables the reasoning trace through thinking: {”type”: “disabled”} in the official API or chat_template_kwargs={”thinking”: False} when serving the model through vLLM or SGLang. However, these settings are separate from Toggle.
中文译文不过,在我检查的部分 API(例如 vLLM 或 SGLang)中,Kimi K2.5 还另外提供 thinking 与 instant 两种二元模式。thinking mode 默认启用;instant mode 则通过官方 API 中的 `thinking: {“type”: “disabled”}`,或在 vLLM/SGLang 服务中设置 `chat_template_kwargs={“thinking”: False}`,关闭推理轨迹。但这些设置与 Toggle 本身相互独立。
Also, the official Kimi report does not provide a separate training recipe for instant mode. However, K2.5’s SFT data were generated using both the earlier K2 model, which produces direct responses without long reasoning, and K2 Thinking, which produces extended reasoning traces. This likely exposes the unified checkpoint to both response formats similar to what’s done in Nemotron 3 above. At inference time, the chat template selects between them by prefilling either an open <think></think> block for instant mode. But again, unfortunately, the report does not disclose the exact data mixture or whether additional mode-specific RL was used.
中文译文Kimi 官方报告也没有为 instant mode 提供单独的训练配方。不过,K2.5 的 SFT 数据同时由较早的 K2 模型和 K2 Thinking 生成:前者直接回答,不产生长推理;后者会输出扩展推理轨迹。这可能使统一检查点同时接触两种响应格式,与前述 Nemotron 3 的方法相似。在推理阶段,chat template 通过预填开放的 `
The newer Kimi K3 provides a more direct inference-time effort interface. The current Kimi Code documentation lists three settings called low, high, and max, with max as the default. These are passed through the reasoning_effort parameter. However, Moonshot has not yet explained how the three effort levels were created during training. Its launch post says that these details will appear in a future K3 technical report, so I’ll stay tuned for that.
中文译文更新的 Kimi K3 提供了更直接的推理阶段强度接口。当前 Kimi Code 文档列出 low、high 和 max 三档设置,其中 max 为默认值,并通过 `reasoning_effort` 参数传递。不过,Moonshot 尚未说明这三档强度在训练中如何形成;其发布文章称相关细节将在后续 K3 技术报告中披露。
6.4 GLM-5 introduces turn-level and interleaved thinking through SFT
中文6.4 GLM-5 通过 SFT 引入逐轮思考与交错思考
The GLM-5 technical report extends the binary on/off thinking switch introduced with GLM-4.5 to multi-turn and tool-using scenarios. It describes three related behaviors (rather than three effort levels):
中文译文GLM-5 技术报告将 GLM-4.5 引入的二元思考开关,扩展到多轮对话与工具使用场景。报告描述了三种相关行为,而不是三档推理强度:
-
Interleaved thinking: this inserts a reasoning block before each response and tool call.
-
Preserved thinking: here, the chat retains earlier reasoning blocks across turns so that the model can reuse them later.
-
Turn-level thinking: this enables or disables reasoning separately for each request in a conversation.
中文译文**Interleaved thinking(交错思考)**:在每次响应和工具调用之前插入一个推理区段。
**Preserved thinking(保留思考)**:跨轮次保留先前推理区段,使模型能够在后续轮次中复用。
**Turn-level thinking(逐轮思考)**:针对一次对话中的每个请求,分别启用或关闭推理。
At inference time, turn-level thinking is the actual on-off switch. In the Z.ai API, thinking is enabled by default and can be disabled for an individual request with thinking: {”type”: “disabled”}. The hosted implementation is not disclosed but the open GLM-5 chat template shows the equivalent mechanism when self-hosting with Transformers, vLLM, or SGLang.
中文译文推理阶段真正承担开关作用的是 turn-level thinking。在 Z.ai API 中,thinking 默认启用,可针对单次请求使用 `thinking: {“type”: “disabled”}` 关闭。托管实现的内部细节未公开,但开放的 GLM-5 chat template 展示了使用 Transformers、vLLM 或 SGLang 自托管时的等价机制。
It starts the assistant response with <|assistant|><think> when thinking is enabled and <|assistant|></think> when it is disabled. The latter closes the reasoning block immediately, so generation proceeds directly to the final answer.
中文译文启用 thinking 时,assistant 响应以 `<|assistant|>
The report says that these behaviors are introduced during multi-task SFT together with an updated chat template.
中文译文报告称,这些行为是在多任务 SFT 阶段,结合更新后的 chat template 引入的。
After SFT, GLM-5 goes through reasoning RL, agentic RL, and general RL. And a final on-policy distillation step uses checkpoints from the preceding stages as teachers. This helps the final model recover capabilities that may have weakened during the sequential RL stages.
中文译文SFT 之后,GLM-5 依次经历 reasoning RL、agentic RL 与 general RL;最后的 on-policy distillation 阶段,将前述各阶段的检查点用作教师模型,从而帮助最终模型恢复在连续 RL 阶段中可能减弱的能力。
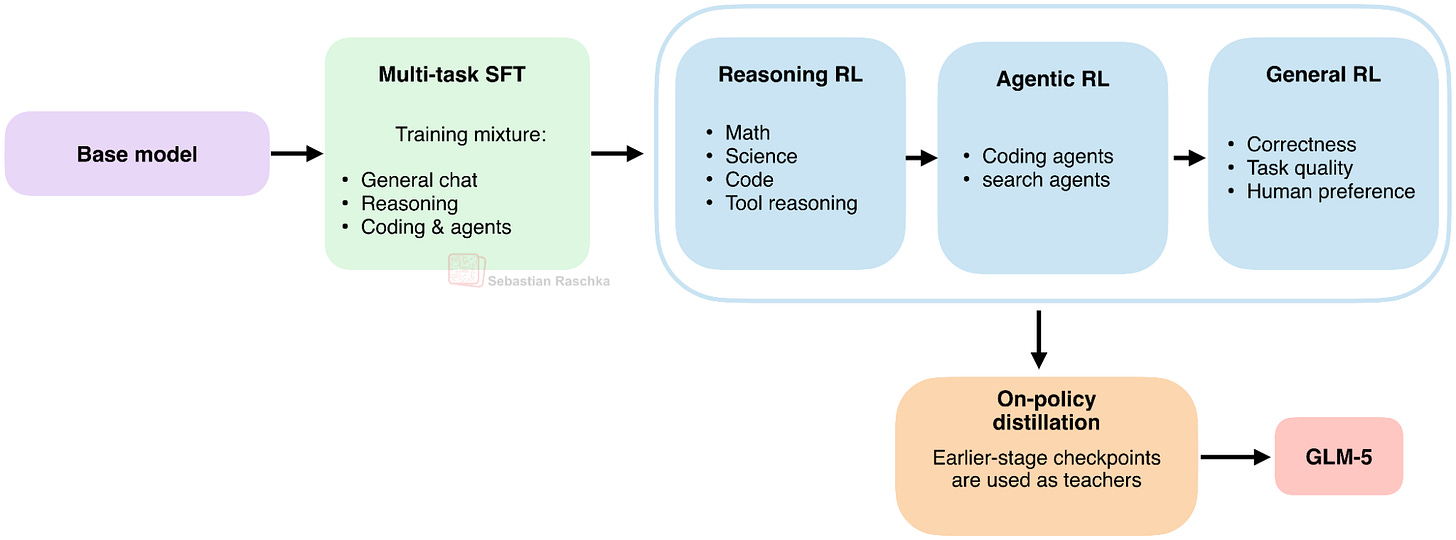
Figure 31: GLM-5 training pipeline.
中文图注图 31:GLM-5 训练流水线。
6.5 Qwen3 uses mode fusion and inference-time truncation
中文6.5 Qwen3 使用模式融合与推理阶段截断
Qwen3 was already covered in Section 4, so I will only summarize the parts that matter for this comparison. According to the Qwen3 technical report, its post-training pipeline has four stages. These are long-chain-of-thought SFT, reasoning RL, Thinking Mode Fusion, and general RL.
中文译文第 4 节已经讨论过 Qwen3,此处仅概括与横向比较相关的部分。根据 Qwen3 技术报告,其后训练流水线包含四个阶段:长链式思维 SFT、reasoning RL、Thinking Mode Fusion,以及 general RL。
Thinking Mode Fusion is the key stage for the effort on-off switch. Here the model is trained via SFT on a mixture of thinking and non-thinking examples. The /think examples contain a reasoning trace, while /no_think examples begin with an empty <think></think> block that is accompanied by a short answer. The following general RL stage reinforces instruction and format following for both behaviors.
中文译文Thinking Mode Fusion 是实现推理开关的关键阶段。模型在此通过 SFT 学习由 thinking 与 non-thinking 样本构成的混合数据:`/think` 样本包含推理轨迹;`/no_think` 样本则以空的 `
Qwen3 also supports a hard thinking budget. At the requested threshold, the reasoning span is stopped and a stop-thinking instruction is inserted before the model continues with its final answer. The report says that this partial-reasoning behavior was not trained explicitly. It emerged after Thinking Mode Fusion.
中文译文Qwen3 还支持硬性 thinking budget。达到指定阈值时,系统会停止推理区段,并在模型继续生成最终答案前插入一条停止思考指令。报告称,这种“部分推理后继续作答”的行为并未被显式训练,而是在 Thinking Mode Fusion 后自然出现。
This gives Qwen3 a learned on-off switch plus an inference-time budget. It is similar but simpler than the DeepSeek V4 and Nemotron recipes.
中文译文因此,Qwen3 同时具备学习得到的开关与推理阶段预算。其机制与 DeepSeek V4、Nemotron 相似,但更为简化。
6.6 Inkling conditions RL on a continuous effort value
中文6.6 Inkling 使用连续强度值对 RL 进行条件化
Inkling was already discussed in Section 5.3. The short v ersion is that its technical report mentions that they use continuous effort conditioning (values between 0.0 and 1.0) rather than fixed effort labels.
中文译文第 5.3 节已经讨论 Inkling。其核心特点是:技术报告采用 0.0 到 1.0 之间的连续强度条件,而非固定的离散强度标签。
After a relatively small initial SFT stage, most of Inkling’s post-training comes from asynchronous RL with more than 30 million rollouts. The desired effort is included in the system message, and the token length penalty is adjusted according to that value during RL. As previously discussed, a higher token cost encourages a shorter response. A lower token cost gives the model more room to reason.
中文译文在规模相对较小的初始 SFT 阶段后,Inkling 的大部分后训练来自异步 RL,累计超过 3000 万次 rollout。目标强度写入 system message,并在 RL 期间根据该值调整 token 长度惩罚。如前所述,更高的 token 成本会鼓励更短响应;更低的 token 成本则为模型提供更大的推理空间。
6.7 Overview of the known recipes
中文6.7 已知训练配方概览
The table below summarizes what is actually documented in the six technical reports.
中文译文下表概括了六份技术报告中实际公开的实现信息。
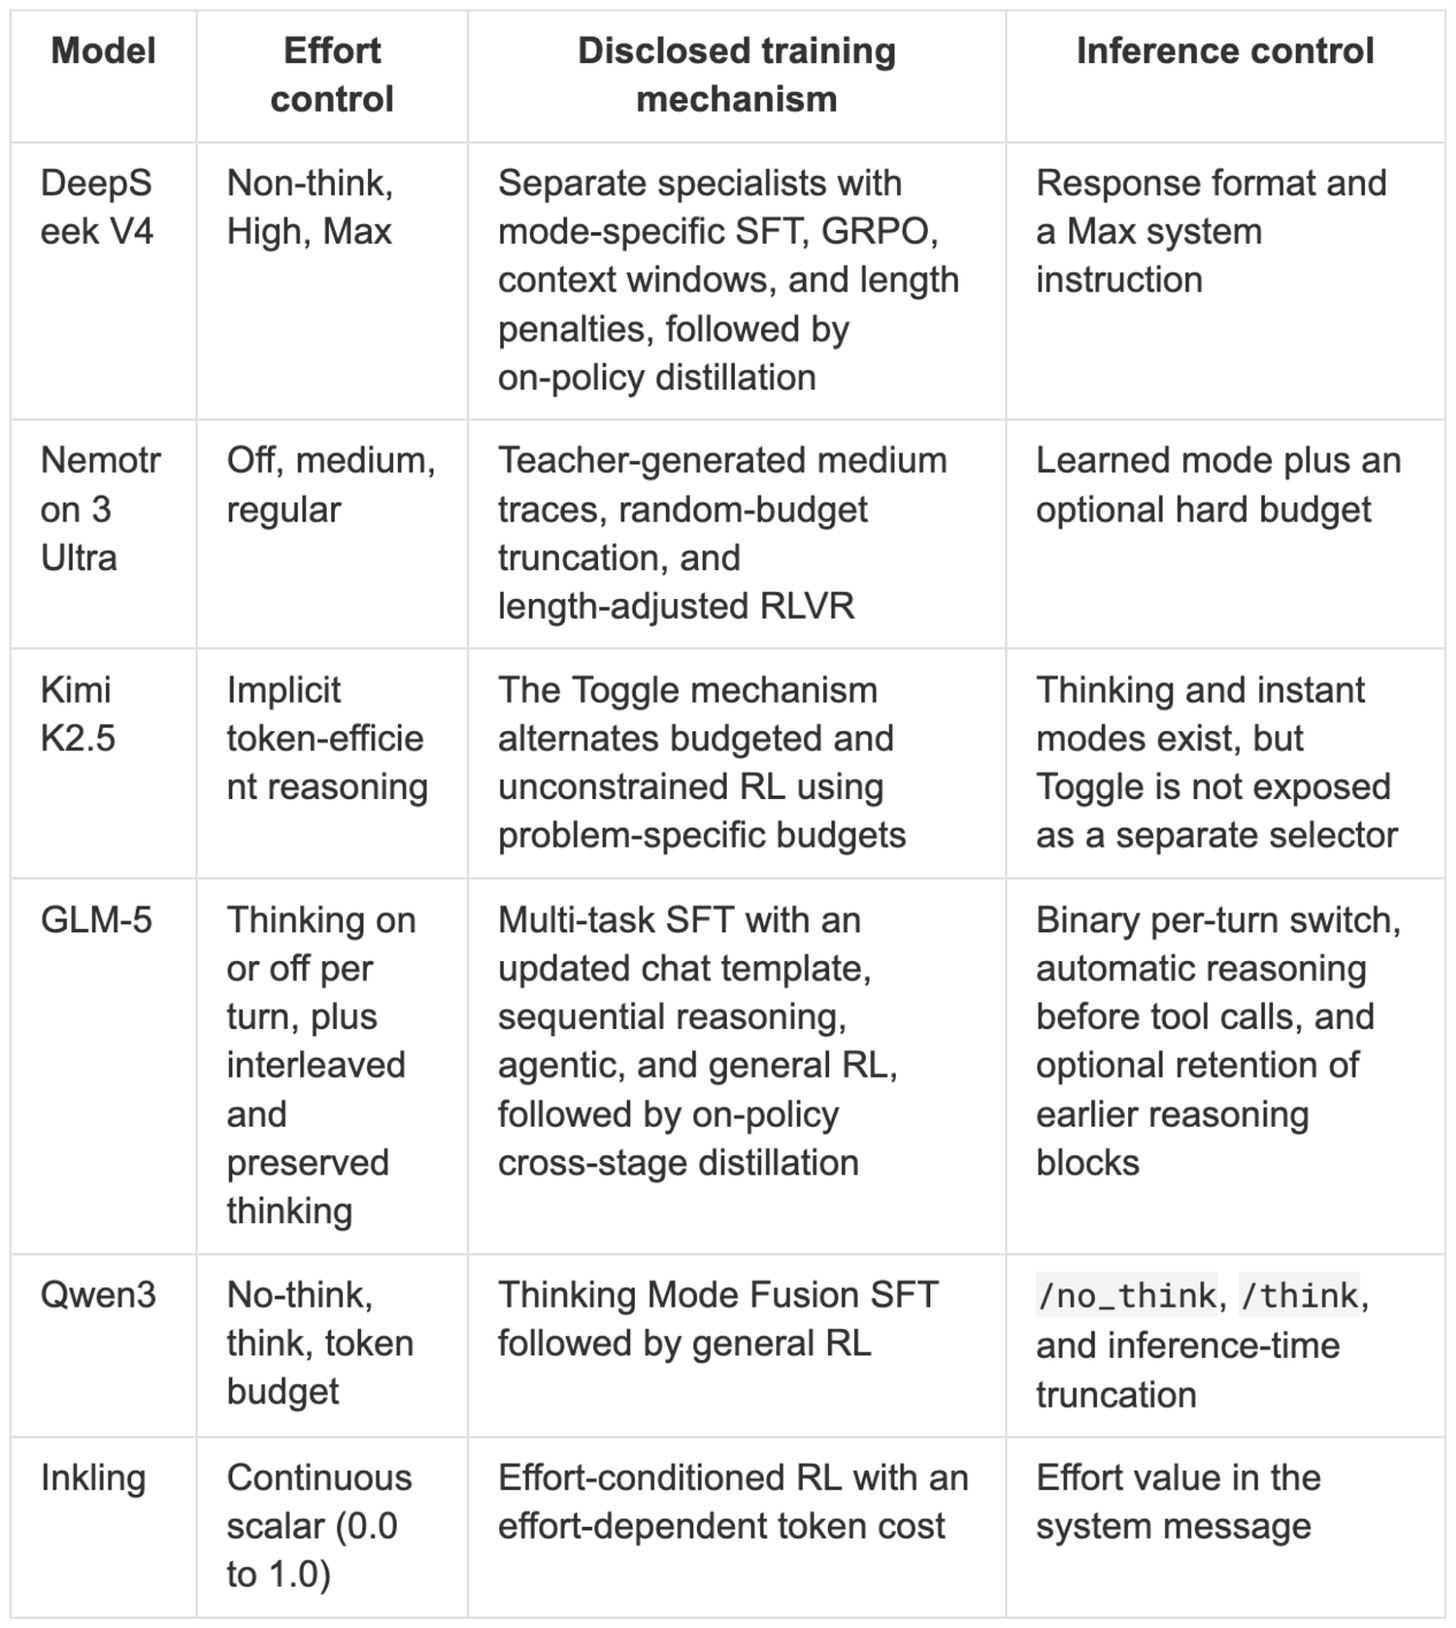
Figure 32: Comparison of the disclosed training mechanisms and inference controls for six open-weight models with reasoning-effort settings.
中文图注图 32:六种支持推理强度设置的开放权重模型,其公开训练机制与推理控制方式对比。
So, looking at the six different open-weight models, they have a shared framework. First, they introduce effort mode control through SFT and the chat template. Qwen3 explicitly mixes thinking and non-thinking examples, while GLM-5 adds interleaved, preserved, and turn-level thinking patterns.
中文译文综合考察这六种开放权重模型,可以看到一套共享框架。第一,它们通过 SFT 与 chat template 引入强度模式控制。Qwen3 明确混合 thinking 与 non-thinking 样本;GLM-5 则加入 interleaved、preserved 与 turn-level thinking 模式。
The second shared component is a mode-conditioned RL stage, where context windows and length penalties change with the requested effort. DeepSeek V4, Nemotron 3 Ultra, and Inkling use this approach.
中文译文第二个共同组件是按模式条件化的 RL 阶段:上下文窗口和长度惩罚会随请求的推理强度而变化。DeepSeek V4、Nemotron 3 Ultra 与 Inkling 都采用了这种方式。
A third ingredient improves robustness under explicit budgets. Nemotron trains on randomly truncated traces, Qwen3 can continue from a forcibly stopped reasoning span, and Kimi alternates budgeted with unconstrained RL. These methods help preserve answer quality when the available reasoning length changes and is even cut short.
中文译文第三类机制用于提高模型在显式预算约束下的鲁棒性。Nemotron 使用随机截断的推理轨迹训练;Qwen3 能够在推理区段被强制停止后继续生成;Kimi 则在有预算和无约束 RL 之间交替。这些方法有助于在可用推理长度发生变化、甚至被提前截断时,维持答案质量。
7. Conclusion
中文7. 结论
The open-weight examples in this article implement reasoning effort through several different mechanisms. Similar labels can be backed by separate specialists, mixed SFT data, mode-conditioned rewards, hard token budgets, or combinations of these methods.
中文译文本文讨论的开放权重模型通过多种机制实现推理强度。相似的强度标签背后,可能是独立专家、混合 SFT 数据、按模式条件化的奖励、硬性 token 预算,或这些方法的组合。
It is difficult to say which approach is best. The models differ in their base checkpoints, training data, post-training compute, benchmarks, and serving goals. Their reports also omit many details needed for a controlled comparison. (Also, there may not be a one-size-fits-all, and a method that works well for an interactive assistant may be a poor fit for a long-running coding agent.)
中文译文目前很难判断哪种方法最优。各模型的基础检查点、训练数据、后训练计算、评测基准与服务目标均不相同;其技术报告也省略了许多受控比较所需的细节。此外,这一问题可能不存在通用解:适合交互式助手的方法,未必适合长时间运行的编码代理。
The holy grail is of course automatic effort selection. We saw this a while back with GPT 5’s Auto mode. It’s a tricky problem to solve, and in the end, the implementation was probably more miss than hit, which is why it got removed from the UI (at least, I can’t find it anymore).
中文译文理想目标当然是自动选择推理强度。GPT-5 曾提供 Auto 模式,但这一问题很难解决;从最终效果看,其实现可能并不理想,因此后来被从界面中移除——至少我目前已经找不到该选项。
In the near future, I think reasoning effort will remain an explicit model input, which will most often be delivered through the system prompt. However agent wrapper/harness around the LLM, or an internal router may increasingly infer the appropriate mode and budget from the task state and available resources automatically (while of course still allowing a user override).
中文译文在近期内,推理强度很可能仍会作为模型的显式输入,并通常通过 system prompt 传递。不过,围绕 LLM 的 agent wrapper/harness 或内部 router,可能会越来越多地依据任务状态与可用资源自动推断合适的模式和预算,同时保留用户覆盖选项。
I still hope that effort selection will become more automatic. Similar to GPT 5’s auto mode, a cheap model or router could choose the mode from the request, tool state, and remaining time or token budget while still allowing a user override. The override is useful if you want to optimize for latency or cost, or maximum performance.
中文译文我仍希望推理强度选择能够进一步自动化。与 GPT-5 的 Auto 模式类似,可以由低成本模型或 router 根据用户请求、工具状态,以及剩余时间或 token 预算选择模式,同时允许用户手动覆盖。用户覆盖对于优化延迟、成本或追求最高性能仍然必要。
I realize that this was a long article, and it was perhaps not the flashiest topic. But I thought that given all the talk about LLMs, reasoning models, and agents, a look at reasoning models was something not covered before, and I hope it was a unique and somewhat useful overview!
中文译文本文篇幅较长,主题也未必最具吸引力。但在 LLM、推理模型与智能体受到广泛讨论的背景下,推理强度机制此前仍缺少系统梳理;希望本文能够提供一份具有独立价值的概览。
Further resources
中文延伸资源
If you want a hands-on implementation of the core training methods behind reasoning models, my Build a Reasoning Model (From Scratch) book walks through reinforcement learning with verifiable rewards and inference-time scaling step by step, with code.
中文译文若希望亲手实现推理模型背后的核心训练方法,我的《Build a Reasoning Model (From Scratch)》会结合代 码,逐步讲解可验证奖励强化学习与推理阶段扩展。
This article focused on how a trained reasoning model can support different effort modes. The book takes a step back and shows how to turn a conventional LLM into a reasoning model in the first place. It is a sequel to Build a Large Language Model (From Scratch) and starts where that book leaves off.
中文译文本文聚焦于训练完成的推理模型如何支持不同强度模式;该书则进一步回到基础问题,说明如何首先把传统 LLM 转化为推理模型。它是《Build a Large Language Model (From Scratch)》的续作,并从前一册结束之处继续展开。
The print edition has now started shipping
中文译文纸质版现已开始发货。
Build a Reasoning Model (From Scratch) [Manning] [Amazon]
中文图注《Build a Reasoning Model (From Scratch)》[Manning][Amazon]
If you liked my previous Build a Large Language Model (From Scratch) book, this is essentially a sequel implementing inference-time scaling techniques and reinforcement learning algorithms from scratch.
中文译文如果你读过此前的《Build a Large Language Model (From Scratch)》,本书可以视为其续篇:从零开始实现推理阶段扩展技术与强化学习算法。
And if you want to support future long-form articles like this one, consider becoming a paid subscriber. It helps me keep writing these independent deep dives and sharing the accompanying code, figures, and experiments.
中文译文如需支持今后继续发布此类长篇文章,可以考虑订阅付费版本。这将帮助我持续撰写独立的深度分析,并分享配套代码、图表与实验。